
Start Your Consistent AI Video Workflow
Key Takeaways
- Text-to-video AI has no memory, so every generation re-interprets a character from scratch unless you anchor it with a locked reference image and verbatim identity block.
- Consistency comes from a pipeline, not a single prompt. The reliable workflow is reference-first: build a locked reference image, write a fixed identity block, generate with reference-to-video, lock environments separately, and stitch in post.
- Image-to-video and reference-to-video beat pure text-to-video for consistency because the first frame anchors identity across the clip, while text alone samples from a broad appearance space.
- Environment and product drift follow the same pattern as character drift. Treat rooms and objects as locked reference assets built from multi-angle photos instead of re-describing them in every prompt.
- Sozee brings this entire consistency pipeline into one studio, with locked likeness, reusable environments, saved outfits and objects, and native scheduling.
Start Creating Consistent Videos With Sozee
Why AI Characters Change Between Shots
Most AI videos show the same pattern: a new face in every clip, outfits that shift between angles, and rooms that quietly morph by shot three. These outcomes follow from how the models work. They are not random glitches.
Each generation is stateless, meaning the model has no persistent memory of a specific character across separate clips. Every text-to-video call denoises a fresh block of noise guided by the prompt. The text encoder converts that prompt into numbers that steer generation only loosely. Text conditioning turns a description into a statistical tendency, not an enforced constraint. Run the same prompt ten times and you get ten plausible but different people. Even a 1% per-frame drift in face geometry compounds into a visibly new person across a 20-shot film.
The fix lives in the workflow. Consistency is a pipeline problem. A reference-first production pipeline that anchors identity, environment, and objects before generation gives the model a stable visual target on every shot. Character consistency is a workflow problem rather than purely a model-quality problem, because even the strongest model drifts when the pipeline around it does not carry a persistent visual identity from scene to scene.
Five-Step Pipeline To Keep A Character Consistent
This workflow is tool-agnostic. Follow the steps in order to reduce character drift across clips.
- Build A Locked Reference Image. Before generating any video, create a multi-angle character sheet with an image model. Include a front view, quarter turn, and side profile. This sheet becomes your character’s master file. Multi-angle character reference sheets function like the turnaround sheets human illustrators use. They supply details the model would otherwise invent, such as the back of a jacket, the nose profile, or the exact shade of an accessory.
Pitfall: Generating video before locking a reference image. Fix: Lock the still image first. The video model re-animates what the still already decided.
- Write A Fixed Identity Block. Create a short, descriptive block of text and reuse it verbatim in every prompt. Do not rephrase it between shots. Synonyms tokenize differently — “brunette” and “shoulder-length dark brown hair” are treated by the model as different people. Treat the identity block like source code. Any edit is a regression and every synonym risks a new character.
Pitfall: Rephrasing the identity block. Fix: Keep it identical across prompts and treat it as immutable source code.
- Generate With Reference-To-Video. For any shot that must match, use image-to-video or reference-to-video instead of pure text-to-video. Feed the model your locked reference image. Image conditioning fixes actual latent content, while text conditioning only nudges generation. The first frame carries special weight in a video diffusion model. Once pinned, it influences the entire clip through temporal attention.
- Lock The Environment Separately. Environment drift is one of the main failure modes in multi-shot AI video. Environment drift is one of six specific failure modes behind disjointed multi-shot AI video, and the direct fix is a single, reusable location reference image. Treat the room as a locked asset built from reference photos instead of a description you re-type in every prompt. A re-typed description becomes a fresh interpretation, which produces a different room.
- Stitch In Post-Production. Assemble the clips in an editor with consistent clip length, aspect ratio, and audio continuity. Longer videos are assembled, not generated. Standard practice is to stitch independent short clips with cuts and chain via the last frame. Stitching preserves consistency that you locked at generation time.
Fixed Identity Block Template You Can Reuse
The identity block is the most important text element in this pipeline. Every word must stay identical across generations, because changing “auburn hair” to “reddish hair” changes the embedding and therefore the face. In a practitioner test of 30 shots, prompts that locked both a single reference image and a verbatim identity block held facial features stable on 24 of 30 shots, versus 9 of 30 with prompt-only consistency — roughly a 2.7x improvement.
Use this template as your starting point and fill each bracket with a single fixed value:
Template:
CHARACTER: [Name], [Age], [Ethnicity], [Hair description], [Eye color], [Face shape], [Skin tone]. Wearing: [Clothing item 1], [Clothing item 2], [Accessory].
Here is a completed example. Notice how each attribute is specific enough to reproduce.
Example:
CHARACTER: Maya, woman, 28 years old, East Asian, shoulder-length straight black hair, center-parted, dark brown eyes, slim oval face, light olive skin. Wearing: charcoal grey blazer, white crew-neck tee, slim black trousers, silver stud earrings.
Add a negative prompt line to the block, such as “wrong age, beard, glasses, hat, duplicate faces, deformed hands.” Update this list whenever a new artifact appears. The negative list should be updated when new artifacts appear so the block gets sharper with every project.
Pitfall: Mixing aspect ratios across shots. Fix: Decide on a single aspect ratio for the entire project before generating the first clip.
Choosing Image To Video Instead Of Text To Video
Text-to-video works well for speed and ideation. Image-to-video and reference-to-video work better for control and reliability. For any multi-shot project where the same character must appear in every clip, reference-first holds up far more often.
Text-to-video drifts because it lacks a persistent visual anchor. Relying on text alone is the weakest anchor for identity, because the model samples from a broad appearance space rather than preserving a fixed subject. In field tests, a pure text rerun of an emotional close-up produced a softer jaw and different eyelid fold. The same master still used for image-to-video kept eye ratio and jaw within a believable range across multiple reruns.
Animating from a locked still image with a video tool’s reference feature gives far better consistency than text-to-video, because text-to-video relies on encoding the character in a prompt. The practical rule is simple. Anchor identity in a still image first, then animate it.
Four breakdown points appear often when you move from image to video. These include frame-to-frame drift as the head rotates, profile and back views where most systems are trained on front-facing faces, outfit and prop drift because models prioritize the face, and length limits that force chaining where every hop can drift. Short clips of 5–15 seconds reduce all four issues.
How Kling, Runway, Veo, And Luma Use References
The pipeline stays the same across tools. The main difference is how each model accepts and applies references. The comparison below shows that every major model now supports reference binding, with variation in how many references you can use and how long consistency holds.
- Kling: Kling 3.0’s Elements 3.0 asset library supports up to four multi-angle reference images for full 360-degree visual consistency. A “Bind Subject” toggle locks a character’s face and clothing across a 15-second multi-shot video. AI Multi-Shot then renders the same character from multiple angles off a single reference, and AI Director can generate up to six distinct camera cuts in one pass while subject-binding keeps the character identical across all six.
- Runway: Runway’s consistency model is reference-driven and generation-time based rather than a training step. A single reference can preserve a character across different lighting, locations, and treatments, and up to three references can be active in one image generation. Gen-4.5 animates an approved character plate into 2–10 second clips, and Edit Studio with Aleph 2.0 can change backgrounds, clothing, and lighting without regenerating the entire scene.
- Veo: Veo 3.1’s “Ingredients to Video” mode takes multiple reference images and composes them into a scene. Google’s published tip is to build ingredient images with Nano Banana Pro first, then feed those into Veo 3.1 as the reference set for a tighter, model-matched reference.
- Luma: Luma AI excels at high-fidelity cinematic video generation and handles character consistency well when paired with strong reference images, but its consistency degrades over long sequences. It works best for short, controlled shots where the reference image is clean and front-facing.
For a deeper comparison, see our guide: Best Text To Video AI Tools In 2026: The Complete Guide.
Fixing Environment And Product Drift
Character drift draws the most attention, yet environment and product drift break continuity just as quickly. The same reference-first logic solves both problems.
Environment Consistency: The room changing between shots disappears when you build reusable environments from reference images instead of re-describing the room in each prompt. Establishing and reusing one location reference image is the direct fix for environment drift. Build the set once from reference photos and attach it to each generation.
The same logic applies to products. Product And Brand Consistency: A product works best as a locked reference object. Use a product reference sheet with multiple angles so logos, colors, and surface details stay identical across shots. The same consistency failure mode that affects faces also affects product shapes, colors, and surface details. Validate the reference sheet by generating the same product at three focal distances, including close-up, mid, and wide, before committing to a full run.
Pitfall: Re-describing the environment instead of reusing a reference. Fix: Build a reusable environment asset from reference photos and attach it to every generation.
Post-Production Stitching For Seamless Sequences
Stitching preserves the consistency you locked earlier. Facial structure drift cannot be fixed with color grading. Regenerate any clip where the face or body structure has changed, and reserve post-production for color, lighting, and minor wardrobe tweaks.
Focus on four variables during assembly: clip length, aspect ratio, audio continuity, and timeline structure. Trim the first and last 6–10 frames of each generated clip, since artifacts often cluster there. Then hide cuts inside motion, such as a turn, a door opening, or a passing object, so the viewer never sees a seam. Finally, color-match across shots to cover any drift that survived generation.
Pitfall: Assuming post-production can repair drift. Fix: Lock consistency at generation time and use editing to maintain it.
The Sozee Solution: A Unified Consistency Studio
Running this pipeline usually means juggling several tools: an image generator for the reference sheet, a separate video model, a prompt manager for the identity block, and an editor for stitching. Sozee builds the entire consistency pipeline into one studio, so you never assemble it from four separate tools.
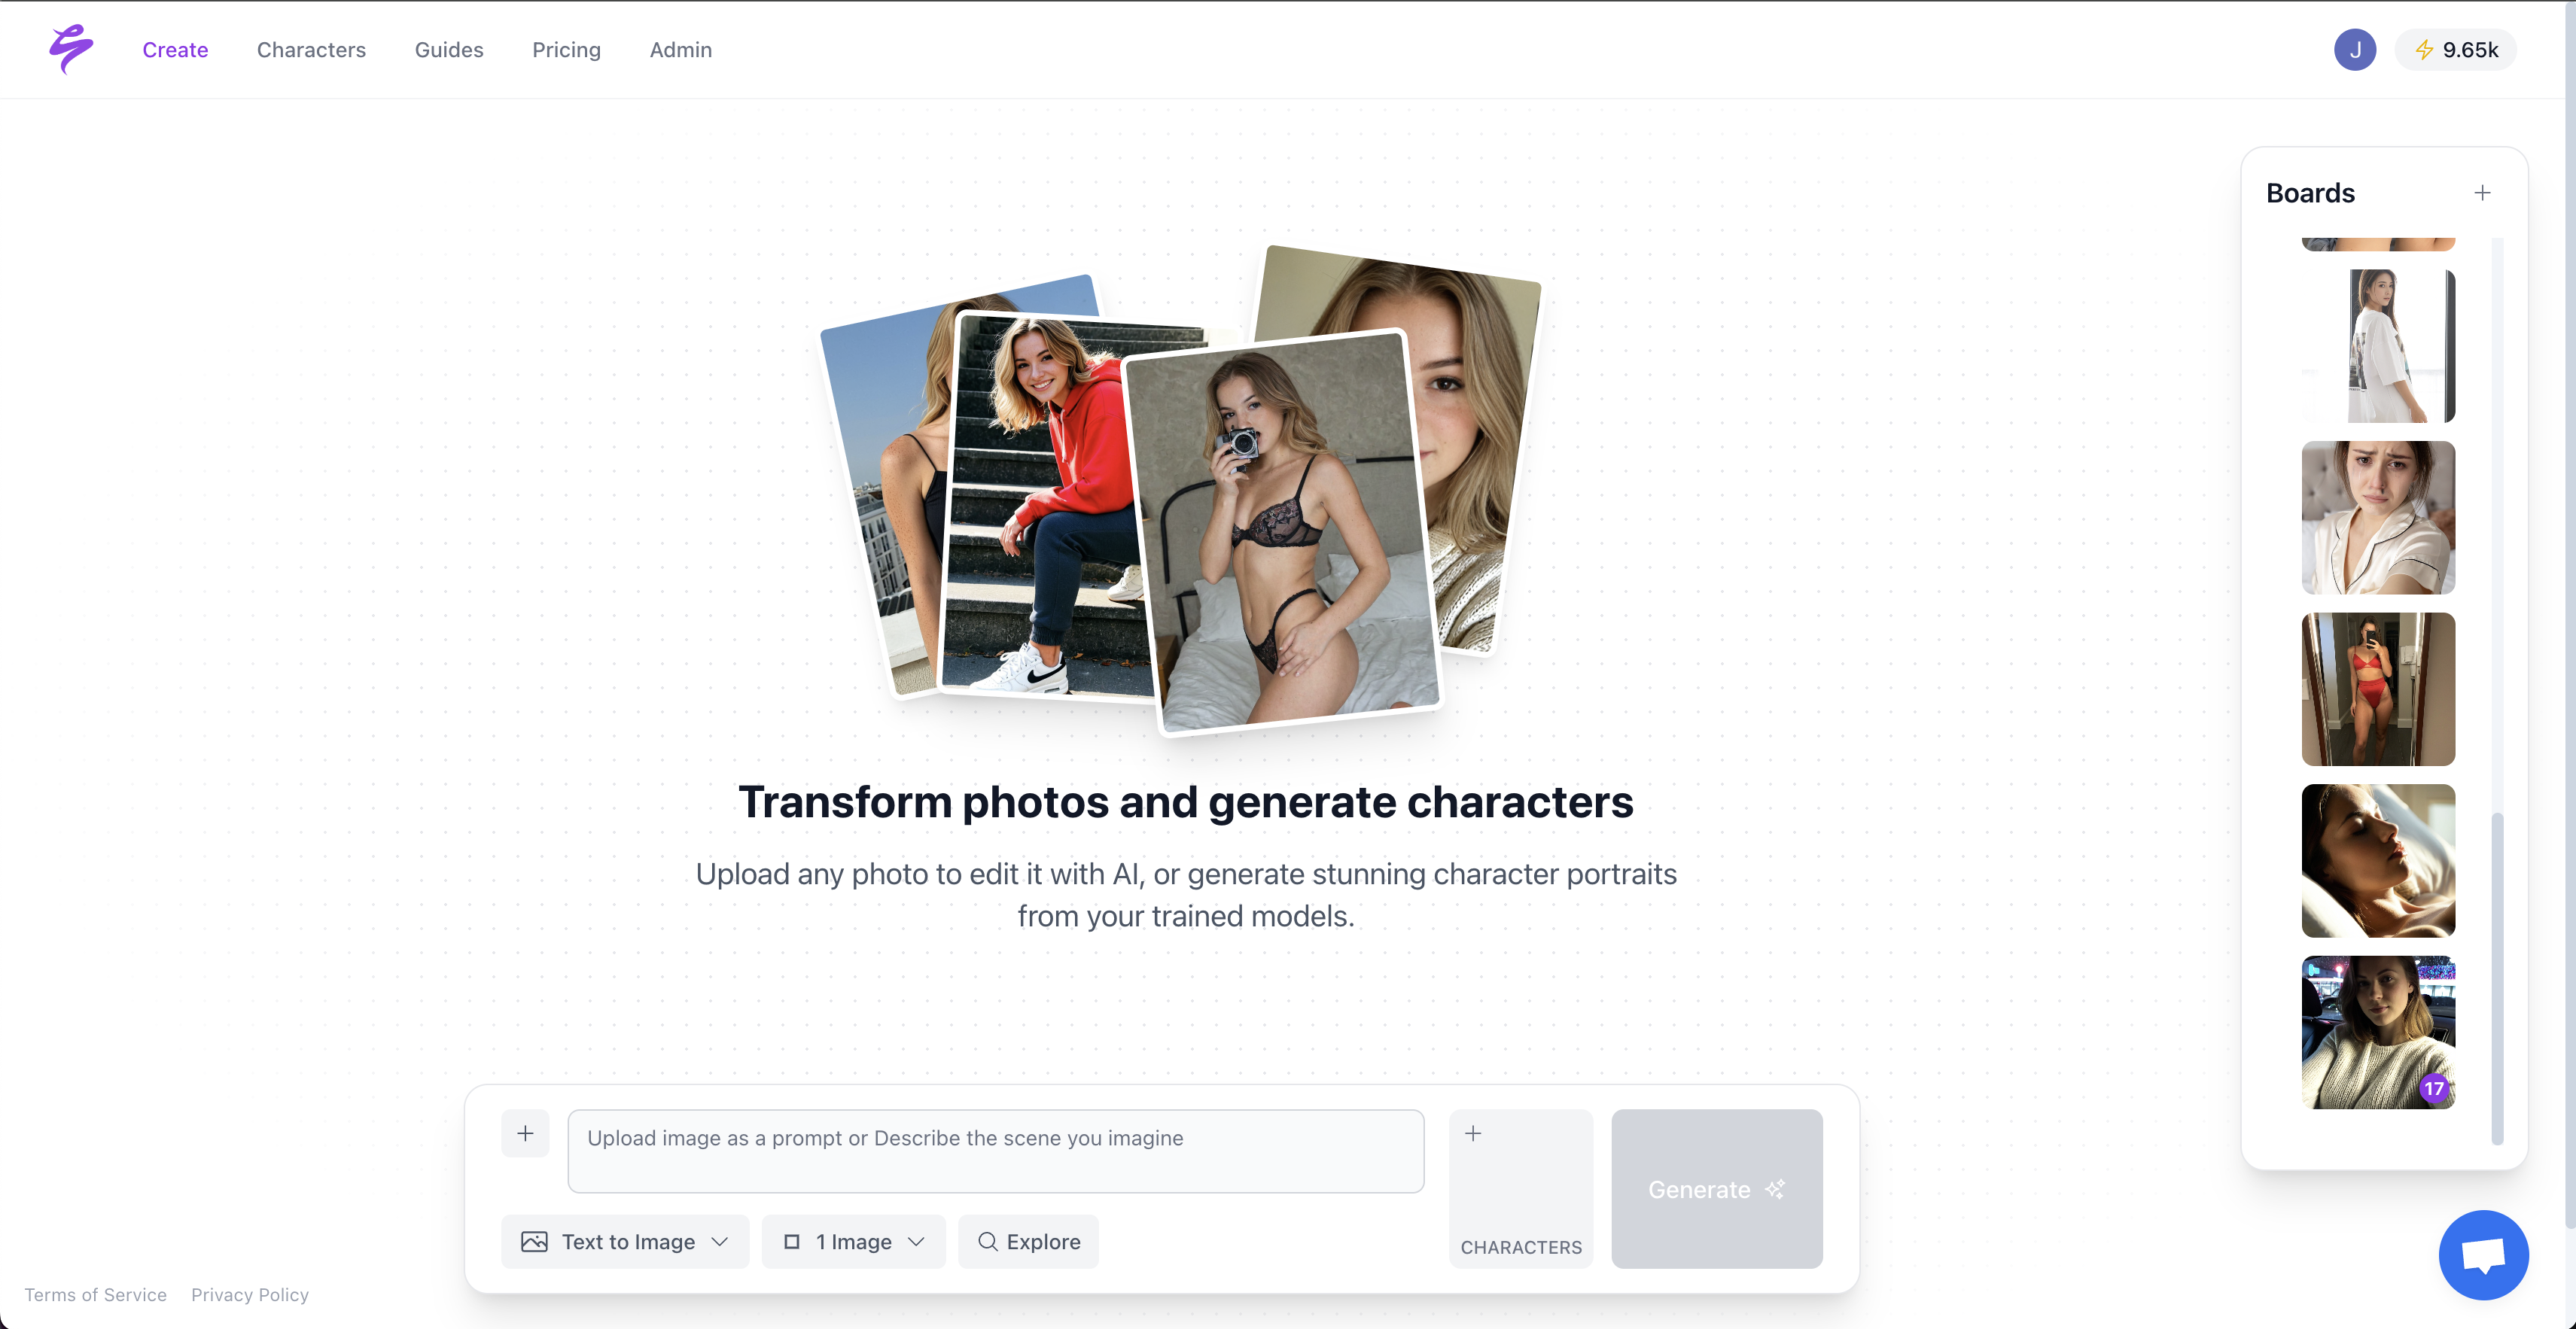
General-purpose tools ship a prompt box. Sozee ships a studio with controls for each decision in the workflow.
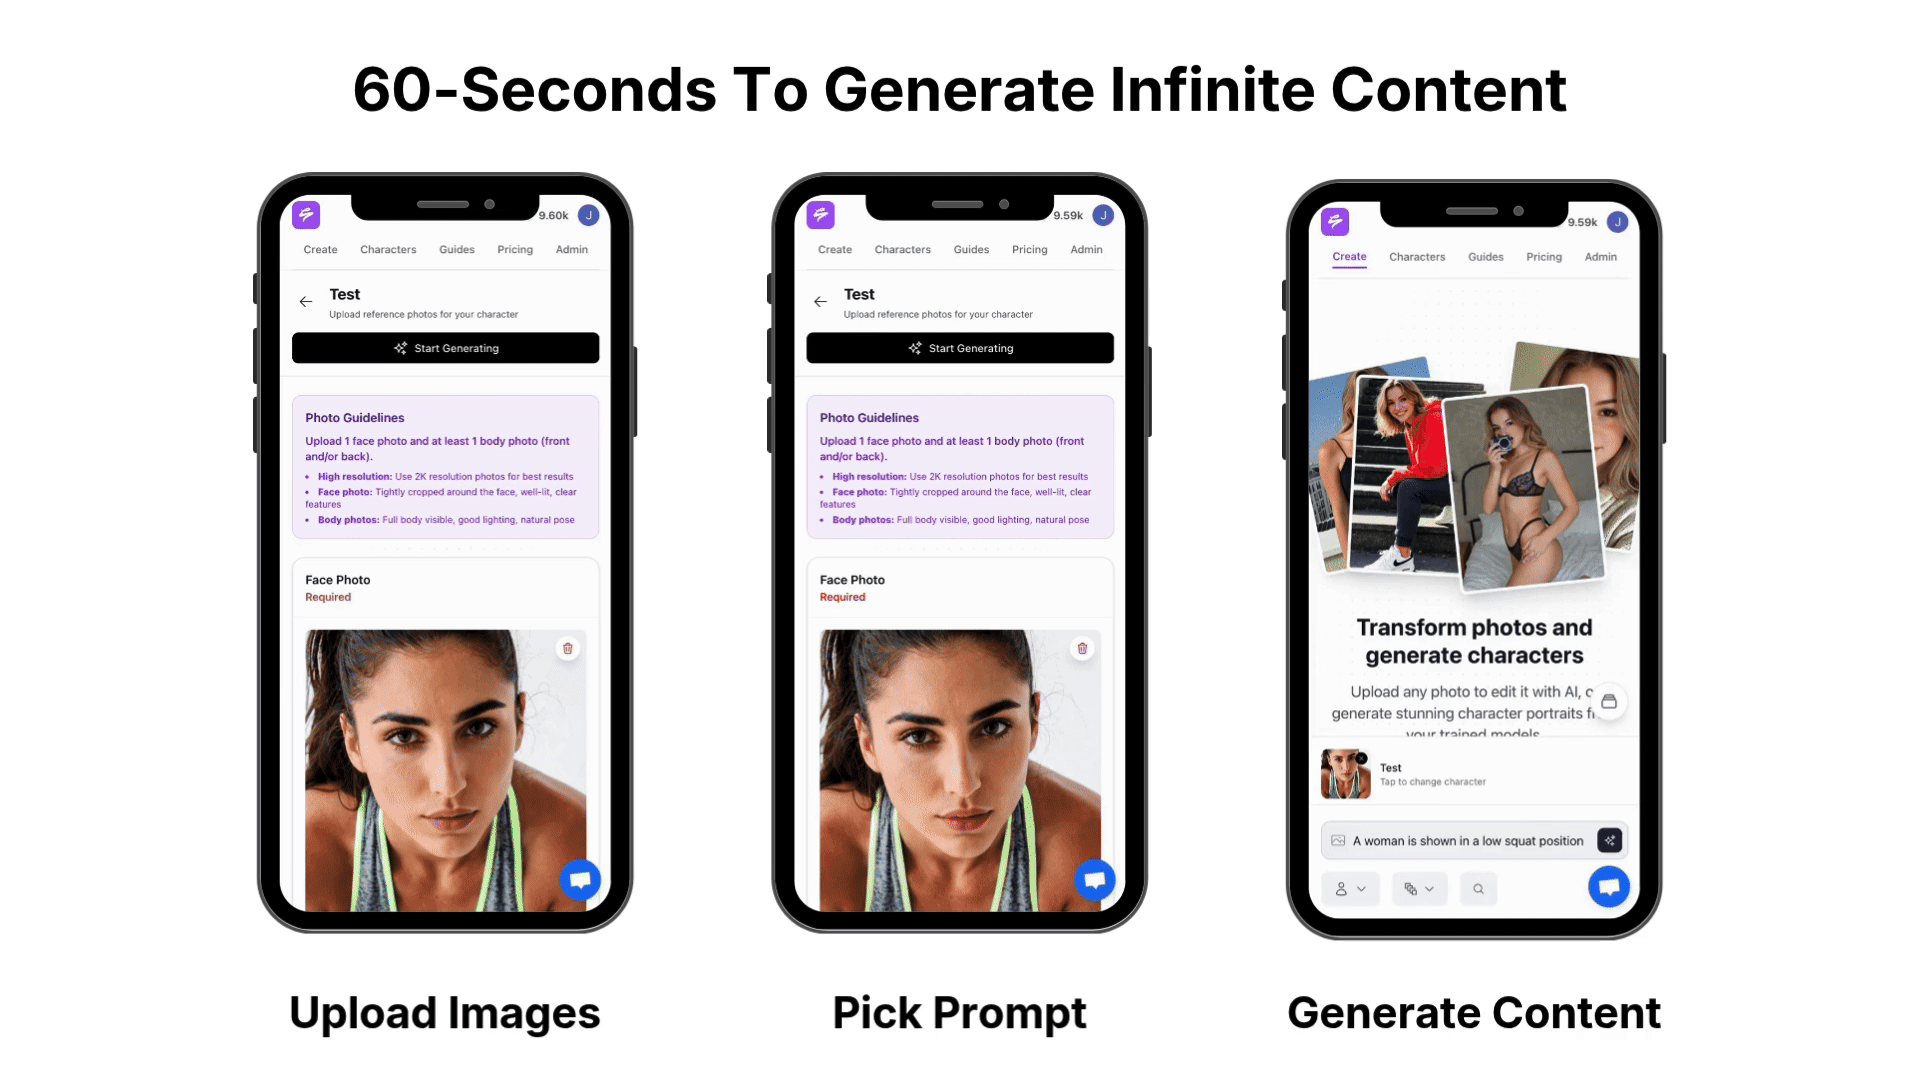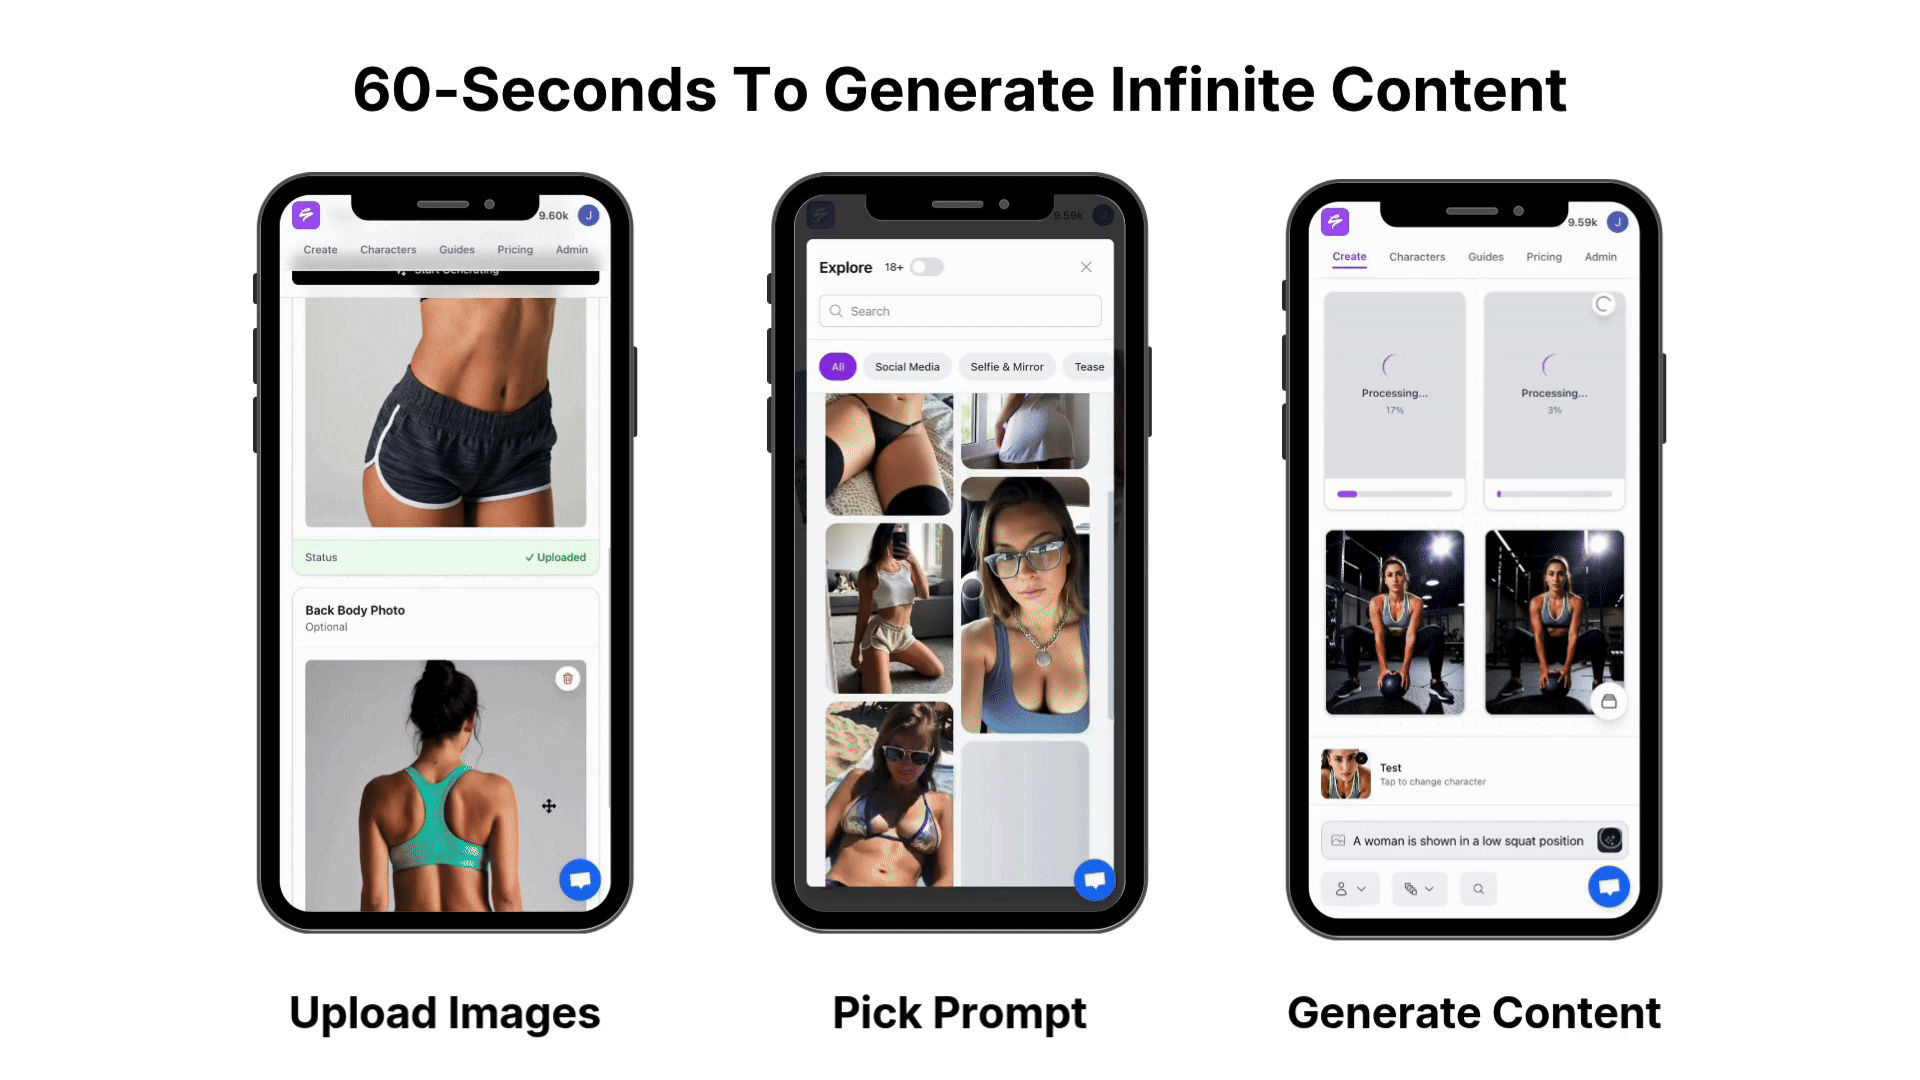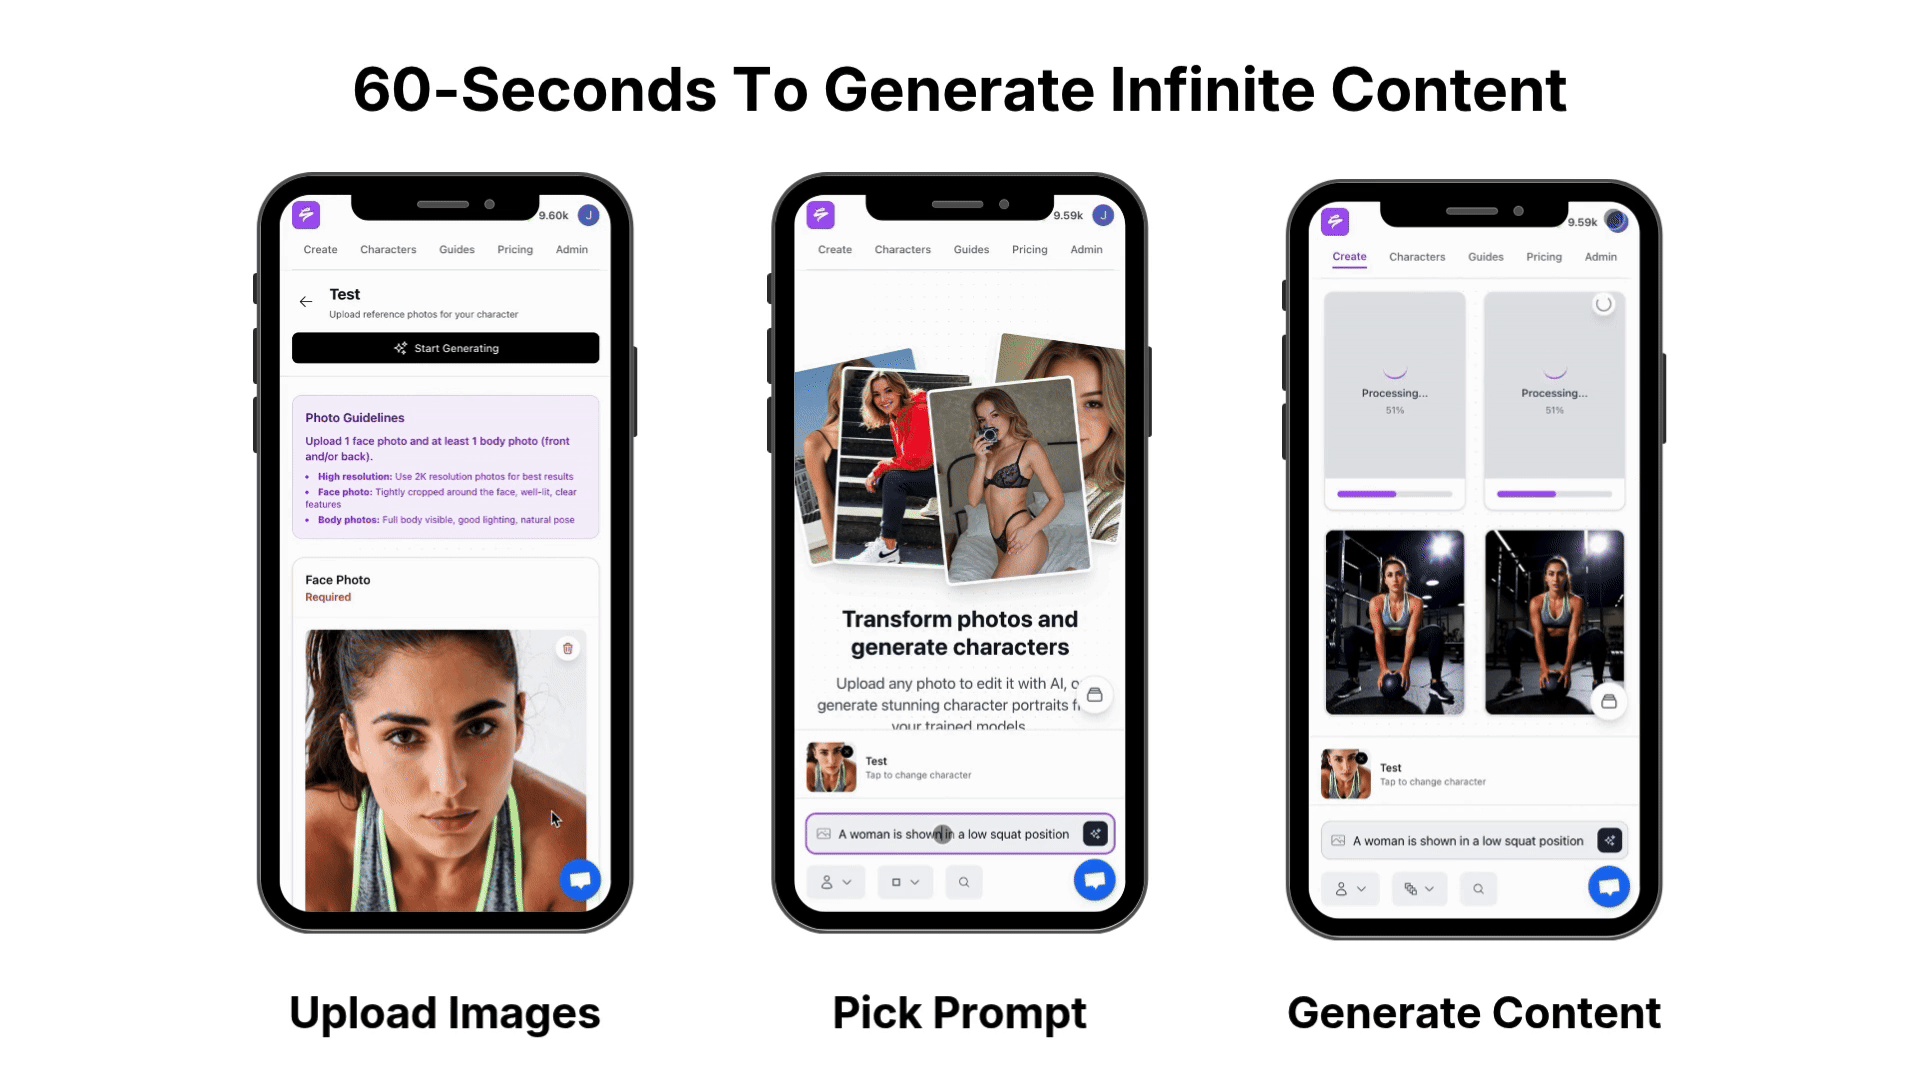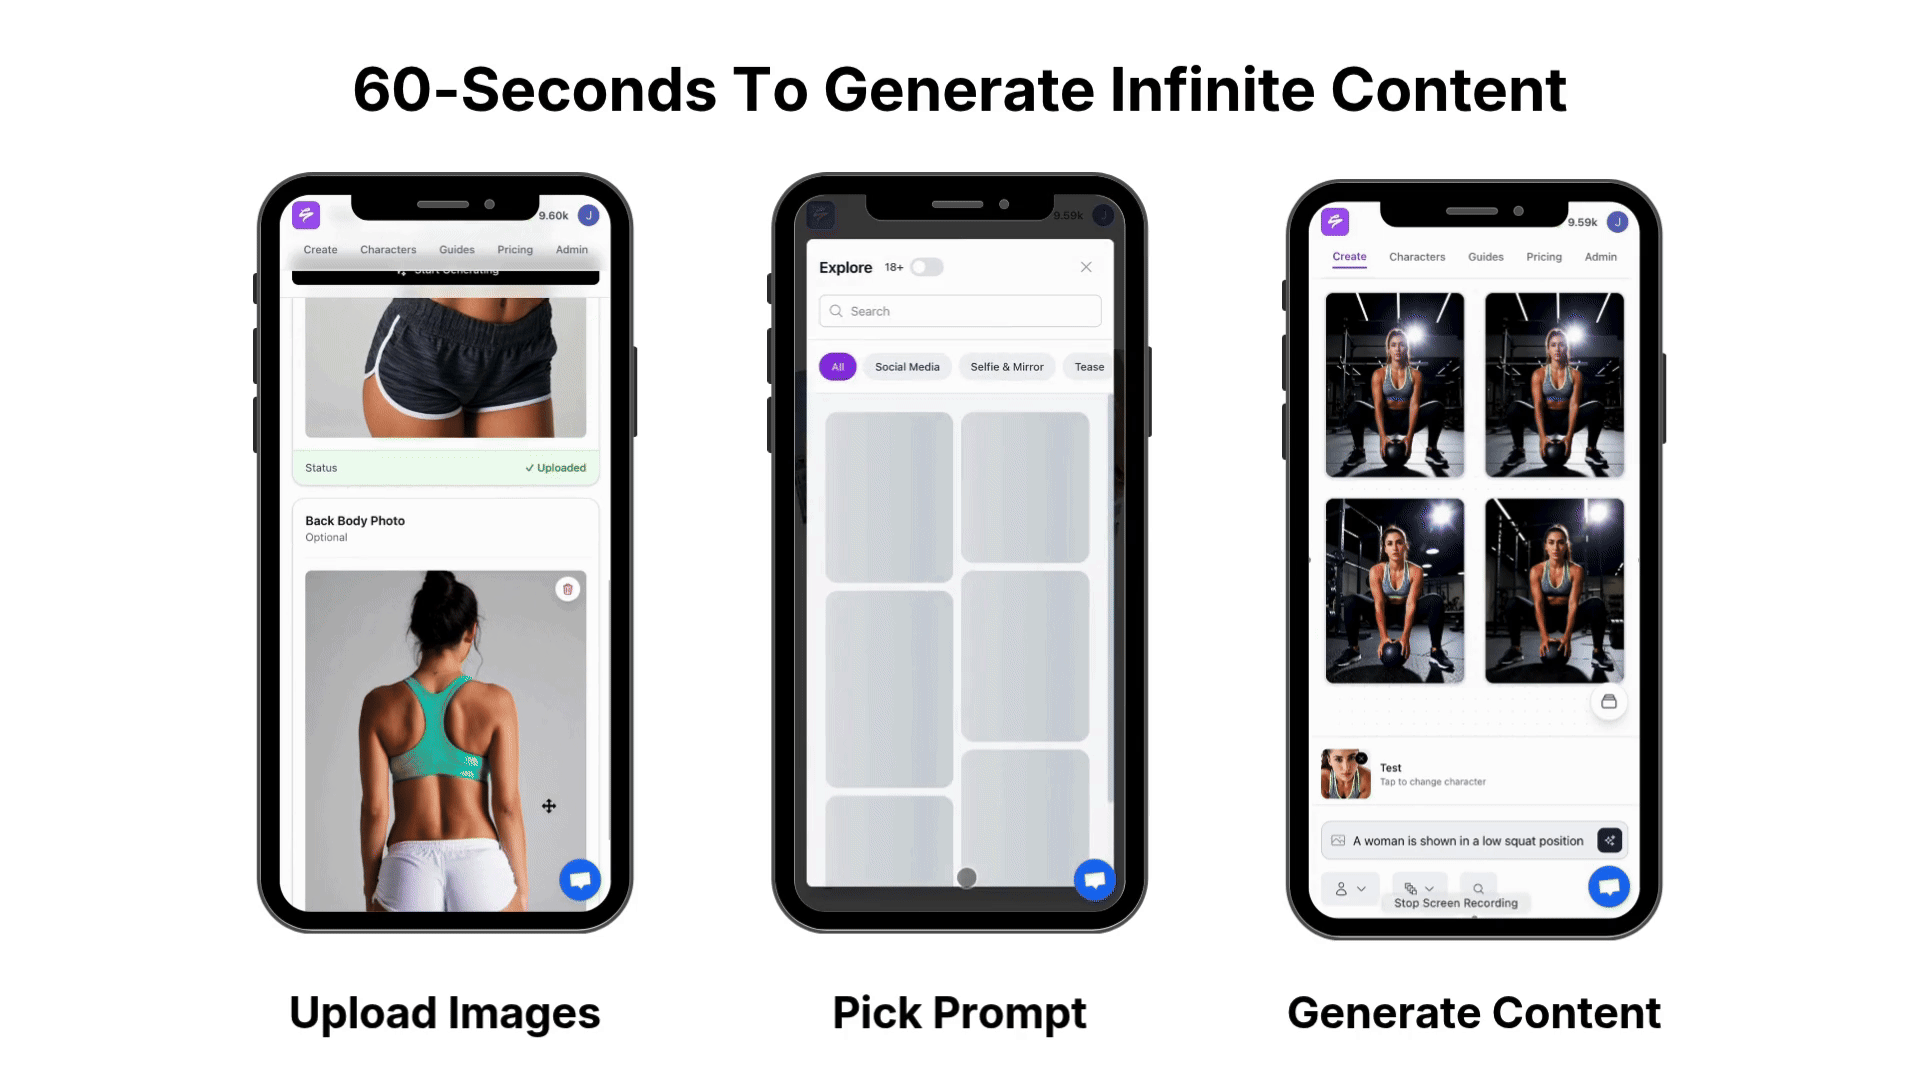
- Locked Likeness: Upload as few as three photos and Sozee reconstructs your likeness with hyper-realistic accuracy. Likeness stays locked across every frame, set, and week. You can also generate an original character from scratch without source photos.
- Photo Control: Setting, outfit, shot style, expression, and object are all controls you set deliberately instead of re-rolling a prompt. Every meaningful decision can be set once and reused.
- Reusable Assets: Environments, outfits, and objects become saved assets you can re-attach at will. Build a room from up to four reference photos and reuse it across projects so the room stays the same room.
- Photo Shoot: Turn one image into a coherent set of up to ten. Identity, outfit, and environment stay locked while angle, pose, and expression change.
- Text-To-Video: Expand a rough idea into a concrete prompt you review before it runs, so you direct the output instead of gambling on it.
- Scheduler And Analytics: Publish per character across major platforms and measure what worked with a clear split between what Sozee posted and what you posted.
For more on how custom characters work inside a consistent pipeline, see Text To Video AI With Custom Characters: Stay Consistent and Text To Video Same Face Generator: Lock Consistent Likeness. For the technical foundations behind these models, see How Text-To-Video AI Works: Models, Motion & Limits.
Lock Your First Character In Sozee
Frequently Asked Questions
The questions below focus on practical details that extend the workflow above.
How Do I Lock A Character In Kling AI?
Use Kling’s Element Library and the “Bind Subject” toggle in Image-to-Video mode. Upload three to four reference images of your character from different angles, such as front, side, back, and a detail shot, to build a Visual DNA that the model binds to across scenes. Kling’s AI Multi-Shot feature can then render the same character from multiple angles automatically. Pair the Element binding with a locked prompt template that uses identical descriptive keywords in every shot, and add a negative prompt listing traits you want to suppress, such as “morphing features, changing clothes, shifting jawline.” If identity starts to soften, generate a fresh clip from the original reference image and cut it into the sequence.
How Do I Keep The Same Room Across Multiple AI Video Clips?
Treat the environment as a locked asset instead of a description you retype. Build a reusable environment from reference photos of the room. Up to four images can define the space as a whole so it stays coherent. Attach that environment asset to each generation. Avoid re-describing the room from scratch, because each new description invites a new interpretation. In Sozee, saved environments function as reusable assets you attach across shoots, so the room stays consistent.
What Is A Character Bible Or Identity Block?
A character bible is a specification document that records every fixed visual trait of a character, including age, ethnicity, hair length and color, eye color, face shape, skin tone, and default outfit. The identity block is the distilled, copy-pasteable version of that bible. It is a short block of text pasted verbatim at the top of every prompt. The model treats every word as a token that steers generation, so edits change the embedding and shift the face. As with the source-code rule from Step 2, any edit to the identity block is a regression. As noted earlier, pairing a locked reference image with a verbatim identity block produced roughly 2.7 times more consistent results than prompt-only generation.
Can I Keep A Product Consistent Across AI Video Shots?
Yes. Use the same reference-first workflow you use for characters. Treat the product as a locked reference object with its own multi-angle reference sheet that includes front, side, back, and detail views. This gives the model enough information to reproduce logos, colors, proportions, and surface details accurately. Avoid relying on text alone for any product that must stay exact. Validate the reference sheet by generating the product at three focal distances before a full run. If the product drifts at one distance, add the missing angle or scale reference to the sheet before spending more credits.
How Long Should Each Clip Be For A Coherent 60-Second Video?
Generate clips of roughly 5 to 15 seconds each, since every major AI video tool in 2026 generates native clips of 5–10 seconds and coherence generally holds within that window, though exact duration options vary by model. Shorter clips behave more reliably because consistency decays with distance from an anchor. A 60-second AI video usually comes from 8 to 12 short clips of 5–10 seconds each assembled in post-production. Trim the first and last 6–10 frames of each clip to remove artifacts, hide cuts inside motion so the viewer never sees a seam, and color-match across shots to cover any residual drift. Plan for approximately three generations per usable shot and budget accordingly.
Assemble Your First Coherent 60-Second Video
Conclusion: Ship A Coherent Video This Week
Character drift is solvable with a structural fix. Stateless generation with no persistent memory creates the problem, and a reference-first production pipeline that locks identity, environment, and objects before video generation solves it. Shifting from pure text-to-video to a reference-first workflow, and treating the identity block as immutable source code, lets creators escape the re-roll loop and ship multi-shot content that feels like one story.
The five steps stay the same across tools: build a locked reference image, write a fixed identity block, generate with reference-to-video, lock the environment separately, and stitch in post. In 2026, what separates amateur from professional AI video is a repeatable workflow that survives a 20-shot film.
Sozee builds this entire consistency pipeline into a single studio, giving you direct control over likeness, environments, outfits, objects, and scheduling in one place. You can run your content operation without exporting to a stack of extra tools.
Create Consistent AI Videos With Sozee Today