
Last updated: September 10, 2026
Key Takeaways
- Open source AI video synthesis lets you download public-weight models and run them locally or on rented GPUs without per-generation fees, though setup usually takes 4–8 hours.
- Model choice depends on your VRAM tier, license permissiveness, and output mode. Wan 2.2 fits 8 GB cards under Apache 2.0, while Mochi 1 and LTX-2 need 16–22 GB.
- Apache 2.0 models like Wan 2.2, Mochi 1, and Open-Sora 2.0 permit unrestricted commercial use, whereas HunyuanVideo 1.5 excludes EU/UK/South Korea and LTX-2 adds a $10 M revenue gate.
- ComfyUI suits creators who want node-based visual workflows, while Diffusers suits developers building production pipelines. Both support the major open-weight families.
- Skip the hardware headaches and start publishing today. Create your first AI video on Sozee.
The Ranked Shortlist: 6 Open-Weight Video Models, Ordered By Who Should Install Them
The ranking below is ordered by fit for a stated constraint, such as VRAM tier, license permissiveness, and output mode, not by a numeric score or invented benchmark. Because hardware and license are hard gates, you should pick the first model you can actually run and legally ship. Quality only matters when two models clear both gates, which is why it serves as the tiebreaker. The table below summarizes each model’s license, VRAM floor, and supported modes so you can scan for the first row you clear.
| # | Model | License | VRAM Floor | Supported Modes |
|---|---|---|---|---|
| 1 | Wan 2.2 TI2V-5B | Apache 2.0 | ~8 GB with ComfyUI native offloading (official implementation documents 24GB) | T2V, I2V |
| 2 | LTX-2 | LTX-2 Community License Agreement (proprietary free license from Lightricks Ltd.) | ~16 GB (distilled builds, FP8) | T2V, I2V, A2V |
| 3 | CogVideoX-2B | Apache 2.0 (model card metadata lists license as ‘other’ / ‘cogvideox’) | ~4 GB with diffusers optimizations (FP16); ~12 GB with optimizations disabled | T2V (I2V via separate CogVideoX-5B-I2V checkpoint) |
| 4 | HunyuanVideo 1.5 | Tencent Hunyuan Community License | ~14 GB with model offloading enabled | T2V, I2V |
| 5 | Mochi 1 | Apache 2.0 | ~22 GB (bf16) | T2V only |
| 6 | Open-Sora 2.0 | Apache 2.0 | Varies by config | T2V |
If you want to skip the stack entirely and start publishing today, skip the setup and generate your first clip.
Open Source vs. Open Weights: What Each License Actually Permits
Before you can act on that ranking, you need to understand what each model’s license actually permits, because “open source” and “open weights” are not the same thing. “Open source” implies that training code, inference code, and weights are all published under a permissive license, meeting the OSI’s Open Source AI Definition, which requires enough disclosure for a downstream user to substantially recreate the system. “Open weights” means only that the learned parameters are downloadable, while the training data and training code may be withheld entirely. CASRAI’s model-weight licence dictionary entry calls this the “three-license problem,” where a single release can carry separate terms for weights, software, and training data.
The practical consequence, as Fora Soft’s self-hosting guide states plainly, is that a model can be a free download and still be illegal to embed in a product you sell. Because the license terms can differ from what the model card advertises, check the LICENSE file in the model’s own repository, not the model card or the announcement blog, before you render a single commercial frame.
Here is what each major model’s license actually permits:
- Wan 2.1 and Wan 2.2 (Apache 2.0): Licensed under Apache 2.0, which permits unrestricted commercial use with no revenue ceiling and includes an explicit patent grant, though that patent license terminates if the licensee institutes patent litigation alleging that the work constitutes patent infringement. The Wan 2.2 model card states the licensors claim no rights over generated contents. Safe to monetize.
- Mochi 1 (Apache 2.0): Mochi 1 preview permits personal and commercial use of the weights, including derivative works and commercial inference services, with no royalty or use-case restriction beyond standard Apache 2.0 terms, which require attribution and preservation of the license notice; Genmo additionally advises organizations to implement safety protocols before deploying the weights in commercial services or products. Safe to monetize.
- LTX-2: Lightricks released LTX-2’s weights, inference code, and training code on 5 January 2026 under the LTX-2 Community License Agreement. That license retains a revenue gate requiring entities with annual revenues of at least $10,000,000 to obtain a paid commercial use license, so review it carefully before commercial use. The earlier LTX-Video 13B carried a similar revenue-gated open-weights license (free under $10M annual revenue). Read the license before monetizing.
- CogVideoX-2B (Apache 2.0): Released under the Apache 2.0 License, though its Hugging Face model card metadata lists the license as ‘other’ with the name ‘cogvideox’. Safe to monetize. The larger CogVideoX-5B carries a separate research license, not Apache 2.0, and commercial use requires reading that license carefully before shipping.
- Open-Sora 2.0 (Apache 2.0): Permits unrestricted commercial use, provided the copyright and permission notices are included in all copies or substantial portions, modified files carry prominent change notices, and any NOTICE file attribution notices are retained. Safe to monetize.
- HunyuanVideo 1.5 (Tencent Hunyuan Community License): Explicitly excludes the European Union, the United Kingdom, and South Korea; requires a separate license above 100 million monthly active users; prohibits using outputs to train competing AI models; and is governed by Hong Kong law. Not safe to monetize without reading the full license. EU, UK, and South Korean creators should use Wan 2.2 or Mochi 1 instead.
How Much VRAM You Need For Local AI Video Generation
License is only half the gate, and VRAM forms the other half. This is the question AI overviews and chatbots consistently fail to answer with specifics. The tiers below map stated VRAM floors from model repositories and vendor documentation to the models that fit them. No invented benchmark numbers appear here.
- 8 GB Tier: ComfyUI’s official documentation states that the Wan2.2 TI2V-5B version should fit well on 8GB VRAM with ComfyUI native offloading, while the official Wan2.2 repository recommends at least 24GB VRAM (e.g., RTX 4090) for its default command. LTX-2 distilled builds have a practical VRAM floor of about 16 GB, the minimum for preview iteration on the distilled checkpoint with FP8 quantization. CogVideoX-2B runs at approximately 12.5 GB VRAM using diffusers with FP16 precision, though the current README lists diffusers FP16 as starting from 4 GB but can be pushed lower with aggressive CPU offloading and VAE tiling. These three techniques are what make the 8 GB tier viable at all: ComfyUI native offloading moves weights to system RAM between steps, distilled few-step inference cuts the number of denoising passes, and CPU offloading keeps the text encoder off the GPU. Without them, the models above would not fit.
- 12–16 GB Tier: HunyuanVideo 1.5 at FP8 with the text encoder offloaded to CPU peaks at approximately 10–12 GB VRAM, with about 12 GB on 12 GB cards like the RTX 4060 Ti 16GB. It generates 4–6 second clips at 480p in approximately 3–8 minutes on a 12 GB card (e.g., RTX 4070/4070 Super) when using FP8 quantization with the text encoder offloaded to CPU RAM. CogVideoX-5B requires about 33 GB of VRAM at bf16 without memory-saving optimizations, but approximately 19 GB with enable_model_cpu_offload() enabled. LTX-2’s 13B distilled build targets this tier. The key techniques here are FP8 quantization and CPU offloading of large text encoders. FP8 layerwise casting cuts a 9B diffusion transformer’s weight storage from ~18 GB in BF16 to ~9 GB in FP8. The forward pass still uses BF16 compute, so quality risk stays low.
- 24 GB+ Tier: Wan 2.2’s T2V-A14B and I2V-A14B MoE variants support both 480P and 720P; the official 720P recipe requires at least 24GB VRAM (e.g., a single RTX 4090), while 480p can run on 16GB cards using FP8 with T5 CPU offload (~14–16 GB). Mochi 1 in bf16 can run on a single 24 GB consumer GPU such as the RTX 4090 via ComfyUI’s native Mochi nodes, which use multiple attention backends and memory optimizations to fit within the card’s VRAM. HunyuanVideo 1.5 at full FP16 with the text encoder on GPU at all times requires approximately 24–28 GB VRAM for 720p, so it runs on a 24 GB card only tightly, and its 480p I2V step-distilled model generates a 4-second clip in about 75 seconds on a single RTX 4090, while the standard (non-distilled) model takes several minutes per clip.
The three optimization techniques that unlock each tier are quantization, distilled few-step inference, and CPU offloading. GGUF/FP8 quantization reduces weight precision from 16-bit to 8-bit or lower, cutting VRAM by roughly 50% at 8-bit (Q8_0/FP8) and up to about 72–75% at 4-bit (Q4_K_M). Distilled few-step inference trains a student model to match a teacher’s generative trajectory in a few steps, for example 4–8 steps, instead of the teacher’s full-step decoding, such as 50 steps. In Diffusers’ enable_model_cpu_offload(), CPU offloading roughly halves VRAM (SDXL drops from 7GB to ~4GB) at a ~10-20% speed cost on NVIDIA hardware, though AMD GPUs (ROCm) incur higher latency overhead of ~15-25% due to PCIe bandwidth differences.
If tuning quantization and offloading is not how you want to spend your week, generate your first video without touching a config file.
Text-To-Video vs. Image-To-Video vs. Video-To-Video: What Each Open Model Handles
Each model below is described in one extractable line covering its supported modes, license, and VRAM floor, with links for deeper specs.
- Wan 2.2 TI2V-5B: T2V + I2V in a single checkpoint, with the 8 GB floor and Apache 2.0 license noted above. Wan2.2-Animate-14B is a unified model for character animation and replacement with holistic movement and expression replication, supporting an animation mode (V2V character animation) and a replacement mode, while Wan2.2-S2V-14B adds audio/speech-driven video generation. Both are documented to run on a GPU with at least 80GB VRAM in the single-GPU workflow, though memory-reduction options and multi-GPU setups can lower the per-GPU requirement.
- LTX-2: T2V, I2V, and A2V generation in a single pass, producing synchronized audio and video, released under the LTX-2 Community License Agreement, with a practical floor of about 16 GB on distilled builds. LTX-2 is a production-ready open model that generates synchronized video and audio natively at up to 4K resolution and 50 fps, with this maximum fidelity delivered via its Ultra mode and clips limited to 10 seconds at 1440p/4K, with lip-sync and ambient sound from 14B video parameters plus 5B audio parameters.
- CogVideoX-2B: T2V generation, while I2V generation is provided by the separate CogVideoX-5B-I2V checkpoint, Apache 2.0, with the ~12 GB tier noted earlier. Generates coherent 6-second clips at 720×480 at 8 fps.
- CogVideoX-5B: T2V and I2V, released under the CogVideoX LICENSE, and uses BF16 precision, with SAT BF16 requiring 26GB of single-GPU VRAM. It delivers higher fidelity than the 2B but carries commercial restrictions.
- HunyuanVideo 1.5: T2V and I2V from a unified architecture, Tencent Hunyuan Community License (EU/UK/South Korea excluded), with the ~14 GB offloaded tier described above. Native resolutions of 480p and 720p at 24 fps with a built-in cascaded super-resolution stage that upscales to 1080p.
- Mochi 1: T2V only, Apache 2.0, ~22 GB bf16 on a single 24 GB card. Generates 480p at 30 fps up to approximately 5.4 seconds. It delivers strong motion realism and has an acknowledged weakness on animation styles.
- Open-Sora 2.0: T2V, Apache 2.0 license, with hardware requirements that vary by configuration. The license permits unrestricted commercial use, provided the copyright and permission notices are included in all copies or substantial portions, modified files carry prominent change notices, and any NOTICE file attribution notices are retained.
ComfyUI vs. Diffusers: Picking Your Inference Pipeline
ComfyUI is the default environment for creators. Its node-based visual workflow lets you wire together model loading, sampling, VAE decoding, and upscaling as a reusable graph that runs identically every time. ComfyUI ships native workflow templates for Wan 2.2 5B text/image-to-video, 14B text-to-video, 14B image-to-video, and first/last-frame video generation. ComfyUI added native HunyuanVideo 1.5 support on November 24, 2025, with no third-party wrapper required. Community nodes such as Kijai’s ComfyUI-WanVideoWrapper push cutting-edge optimizations, including FP8 quantization, offloading, and experimental research features, faster than the core can integrate them.
The Hugging Face Diffusers library is the right choice for developers building production applications. It is Python-native, integrates with device_map sharding for multi-GPU setups, and provides CogVideoXPipeline, MochiPipeline, and equivalent classes for every major model. All five major open-weight video families ship with both ComfyUI and Diffusers support, so the surrounding code barely changes when swapping one model for another. For hands-on ComfyUI walkthroughs, search YouTube for model-specific setup guides, because the SERP for those queries is already stacked with video results that out-demonstrate any written tutorial.
Is Sora 2 Open Source?
No. Sora 2 is a proprietary, API-only model from OpenAI, available via the OpenAI API until its September 24, 2026 sunset. Its weights are not published, it cannot be run locally, and there is no open-weight version. The open-weight alternatives to consider instead are Wan 2.2 (Apache 2.0, 8 GB floor with ComfyUI offloading), HunyuanVideo 1.5 (14 GB floor with model offloading, license restrictions apply), and LTX-2 (LTX-2 Community License, audio-sync, ~16 GB distilled builds).
The Long-Form Problem: Stitching 5-Second Clips Into Sequences
Open-weight video models generate clips of varying lengths, typically ranging from about 4 seconds (e.g., Stable Video Diffusion XT) up to 15–16 seconds (e.g., Open-Sora), with many models producing 5–10 second clips. Turning those clips into a publishable sequence requires a stitching layer that no “best models” listicle covers.
The standard technique is last-frame chaining. The final frame of clip N becomes the conditioning image for clip N+1 in an I2V pass, creating visual continuity across the cut. Overlap sampling extends this by generating a new clip that shares several frames with the tail of the previous one, then scoring every candidate seam inside that overlap window. The AlignedOverlapCutTransition node in the LTXDirector-Extender ComfyUI pack implements this exactly. It scores every candidate cut using mean squared error between source and new frames around the boundary, merges the two batches at the lowest-error seam, and outputs a seam_index that can wire directly into an audio transition node so sound and picture break at the same instant. Three tuning knobs, edge_margin, seam_shift, and blend_frames, control where the cut lands and whether it crossfades.
For script-to-edit automation, OpenMontage is an AGPLv3-licensed agentic video production system that handles research, scripting, asset generation, editing, and final composition from a plain-language description. It supports local open-weight generation via Wan 2.1 (1.3B and 14B variants), HunyuanVideo 1.5, LTX-2, and CogVideoX (2B and 5B), and asks for human approval at creative decision points before final rendering.
Open Source AI Video Editors For Assembly And Finishing
Several open-source and source-available editors handle cutting, color, and assembly of AI-generated clips.
- SynthCut (GNU General Public License v3.0 or later): A self-hosted, AI-native, open-source video editor that exposes itself as an MCP server with 94 tools, so any MCP-compatible client, including Claude Desktop, Claude Code, Cursor, Windsurf, Gemini CLI, and Codex CLI, can drive real, local, offline FFmpeg edits. Capabilities include cut/trim/split/concat, per-clip color grading with LUTs, Whisper captions, subject-tracking auto-reframe, and OpenTimelineIO export to DaVinci Resolve. Note that its motion graphics module uses Remotion, which requires a paid Company License for for-profit organizations of four or more people and is governed by a proprietary license that is not OSI-approved open-source. Isolate that module or swap it for a Puppeteer renderer for a fully GPL-clean build.
- OpenCut AI (MIT): A privacy-first, open-source, self-hosted AI video editor (a fork of OpenCut maintained by Ekaanth) whose v0.4.0 release added six new AI features, including local AI dubbing, background removal, auto B-roll, multilingual captions, edit by speaker, and auto multicam sync, that run on-device by default, though some features also offer optional cloud engines. It includes 20 WebGL shader transitions, an AI Co-Pilot Agent that accepts plain-English goals, auto B-roll matching via on-device CLIP embeddings, AI dubbing using Meta’s NLLB-200 and XTTS v2 locally, and LUFS loudness normalization to platform targets.
- Timeline Studio (MIT License with Commons Clause): Licensed under the MIT License with Commons Clause, which is free for personal use but requires a separate agreement for commercial use. It is a local-first, browser-based AI video editor with a CapCut-style multi-track timeline, WebGPU AI music generation, Whisper-based automatic captions, YOLOS/MODNet smart framing, and a versioned headless command runner for agent-driven edits. It ships the ‘edit-timeline-studio’ AI Video Editing Skill for Codex, Claude Code, GitHub Copilot, and Gemini CLI, synchronized cross-platform in v0.9.2 on August 7, 2026.
- Palmier Pro: A Swift-native macOS editor (requires macOS 26 on Apple Silicon) with MCP support and built-in generative AI. The GPL-to-proprietary caveat is significant. Releases through v0.7.6 were GPLv3, but all later binary releases are proprietary with no published source. Evaluate accordingly before building a workflow around it.
Open Source AI Video Generator vs. API: The Cost Tradeoff
Self-hosting means no per-generation API fees but real hardware, setup, and maintenance costs. Self-hosting rarely beats a paid API on price below roughly five million tokens per day on a single workload, once fully loaded costs, including GPU, utilization, and ops labor, are counted, with the crossover typically sitting between a few million and twenty million tokens per day. A GPU billing $1,700 a month rented can cost $5,000–$8,000 a month once maintenance staff are counted, which is a 3-to-5× multiplier on raw GPU rental.
Three non-price reasons push teams to self-host. Data residency matters when sensitive footage cannot leave your machines. High sustained volume matters once you pass the crossover point and keep GPUs busy. License and customization matter because only a permissively licensed model such as Apache 2.0 lets you fine-tune and ship the customized model inside a product you sell. Self-hosted open-weight deployments may lack provider indemnification or related contractual and technical protections, not only for IP-infringing outputs but also more broadly for harmful, inaccurate, or discriminatory outputs. That responsibility shifts entirely to the deploying organization.
APIs mean predictable spend and no infrastructure ownership. The tradeoff is that every prompt and frame leaves your machine, and you depend on the provider remaining willing to serve you.
When Self-Hosting Is Not The Answer: Sozee As A Managed Studio
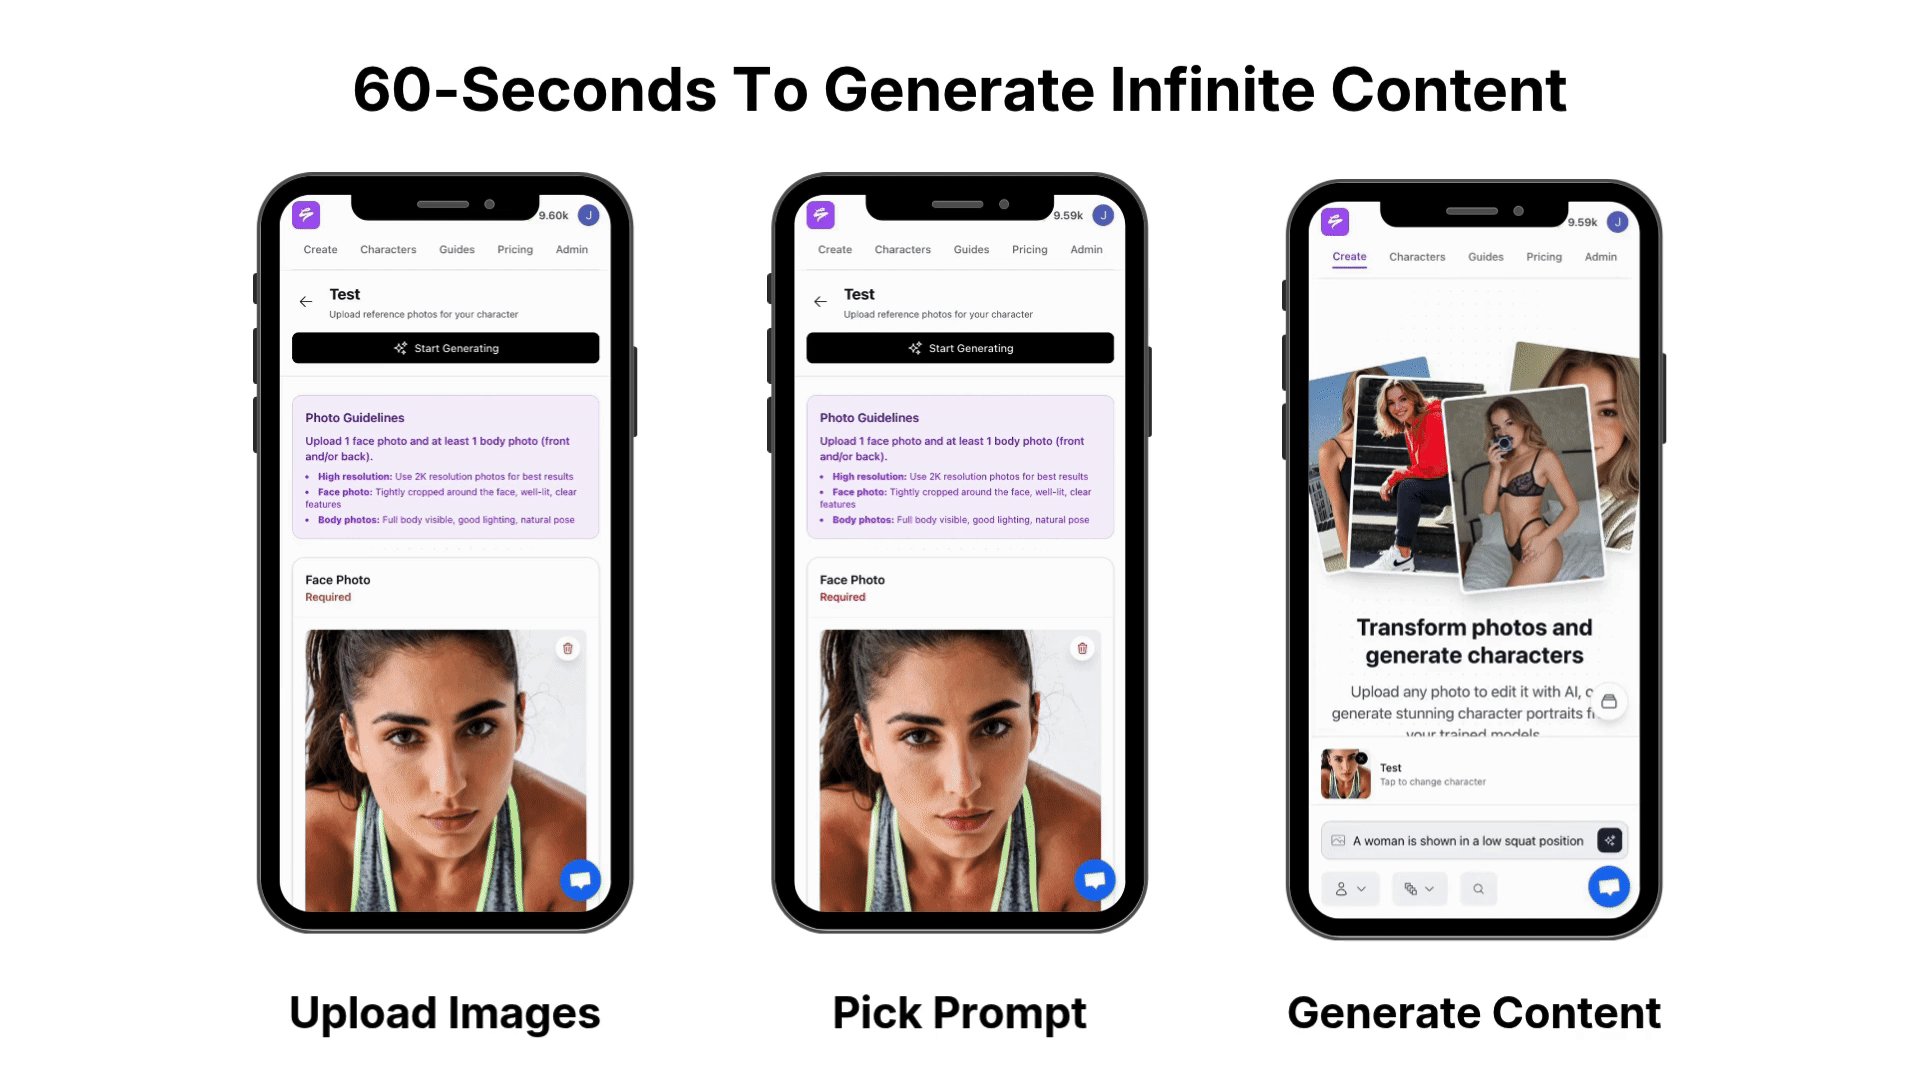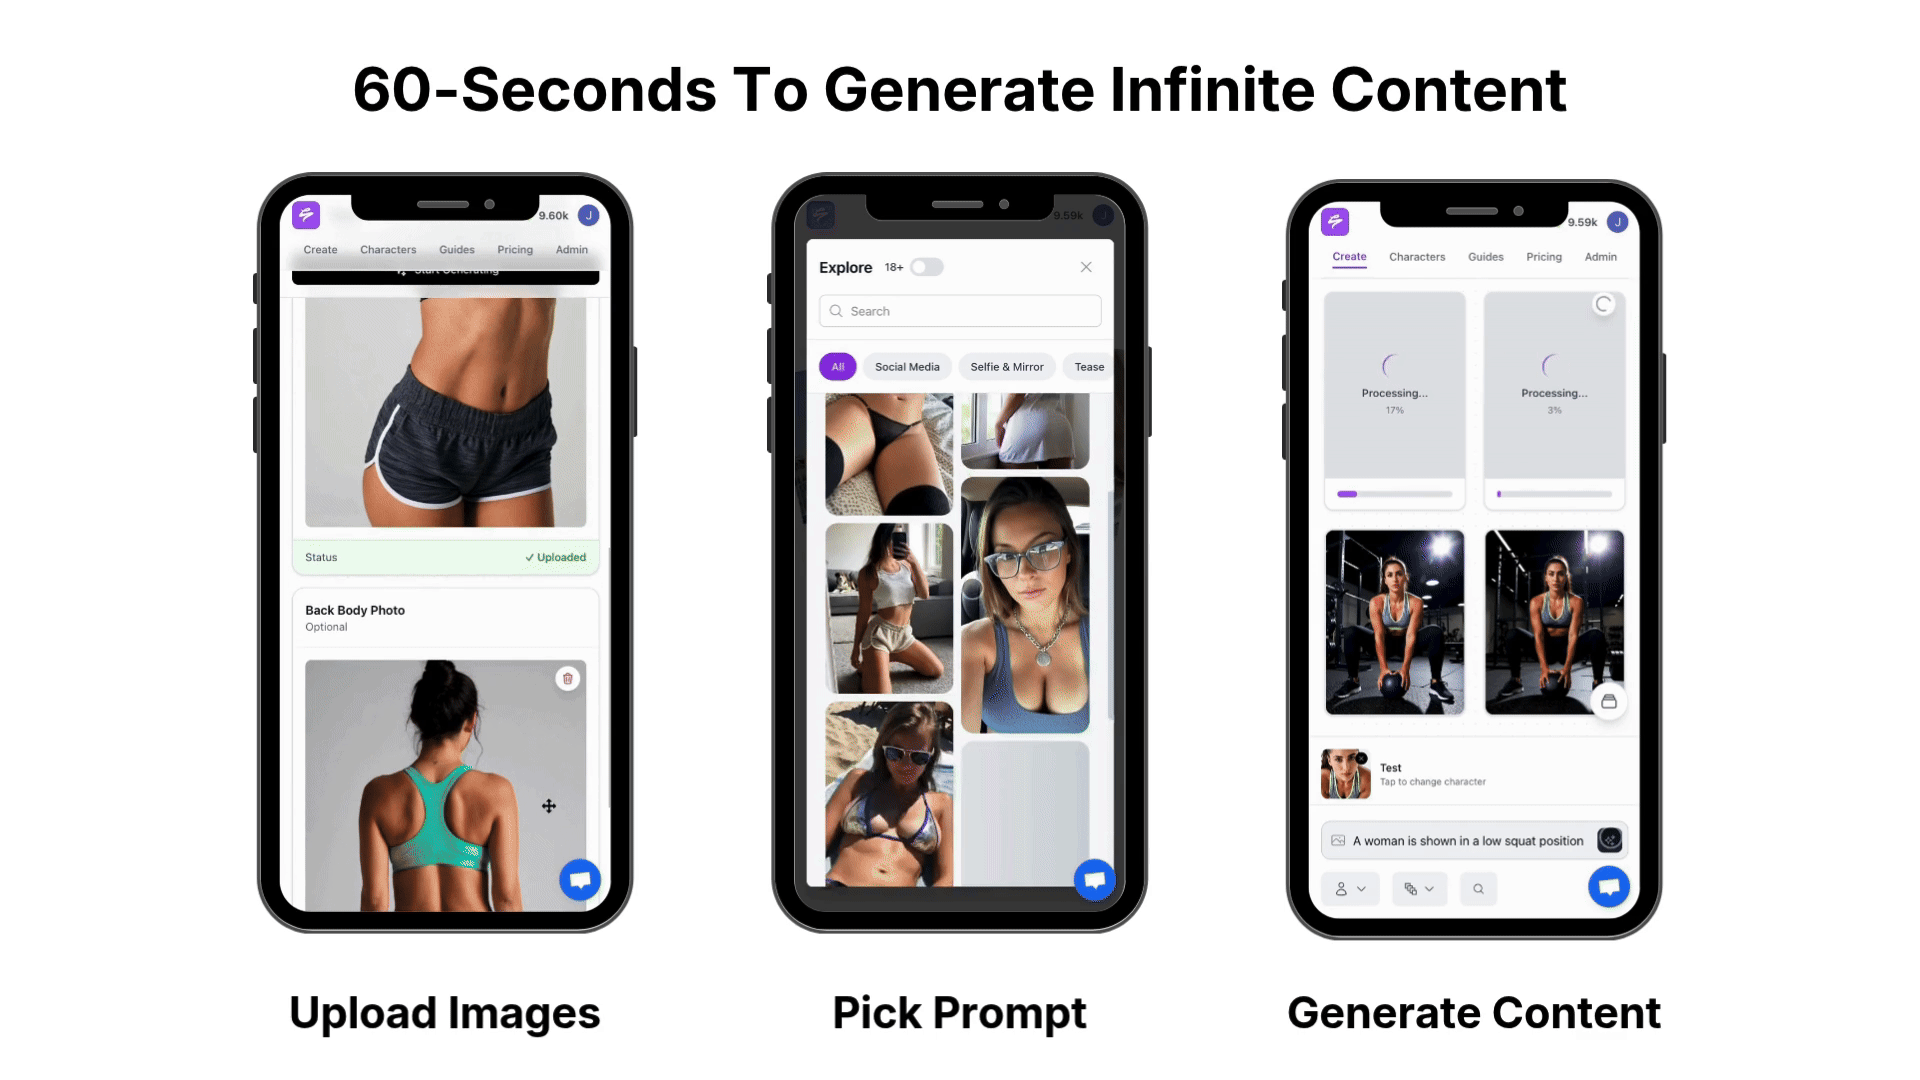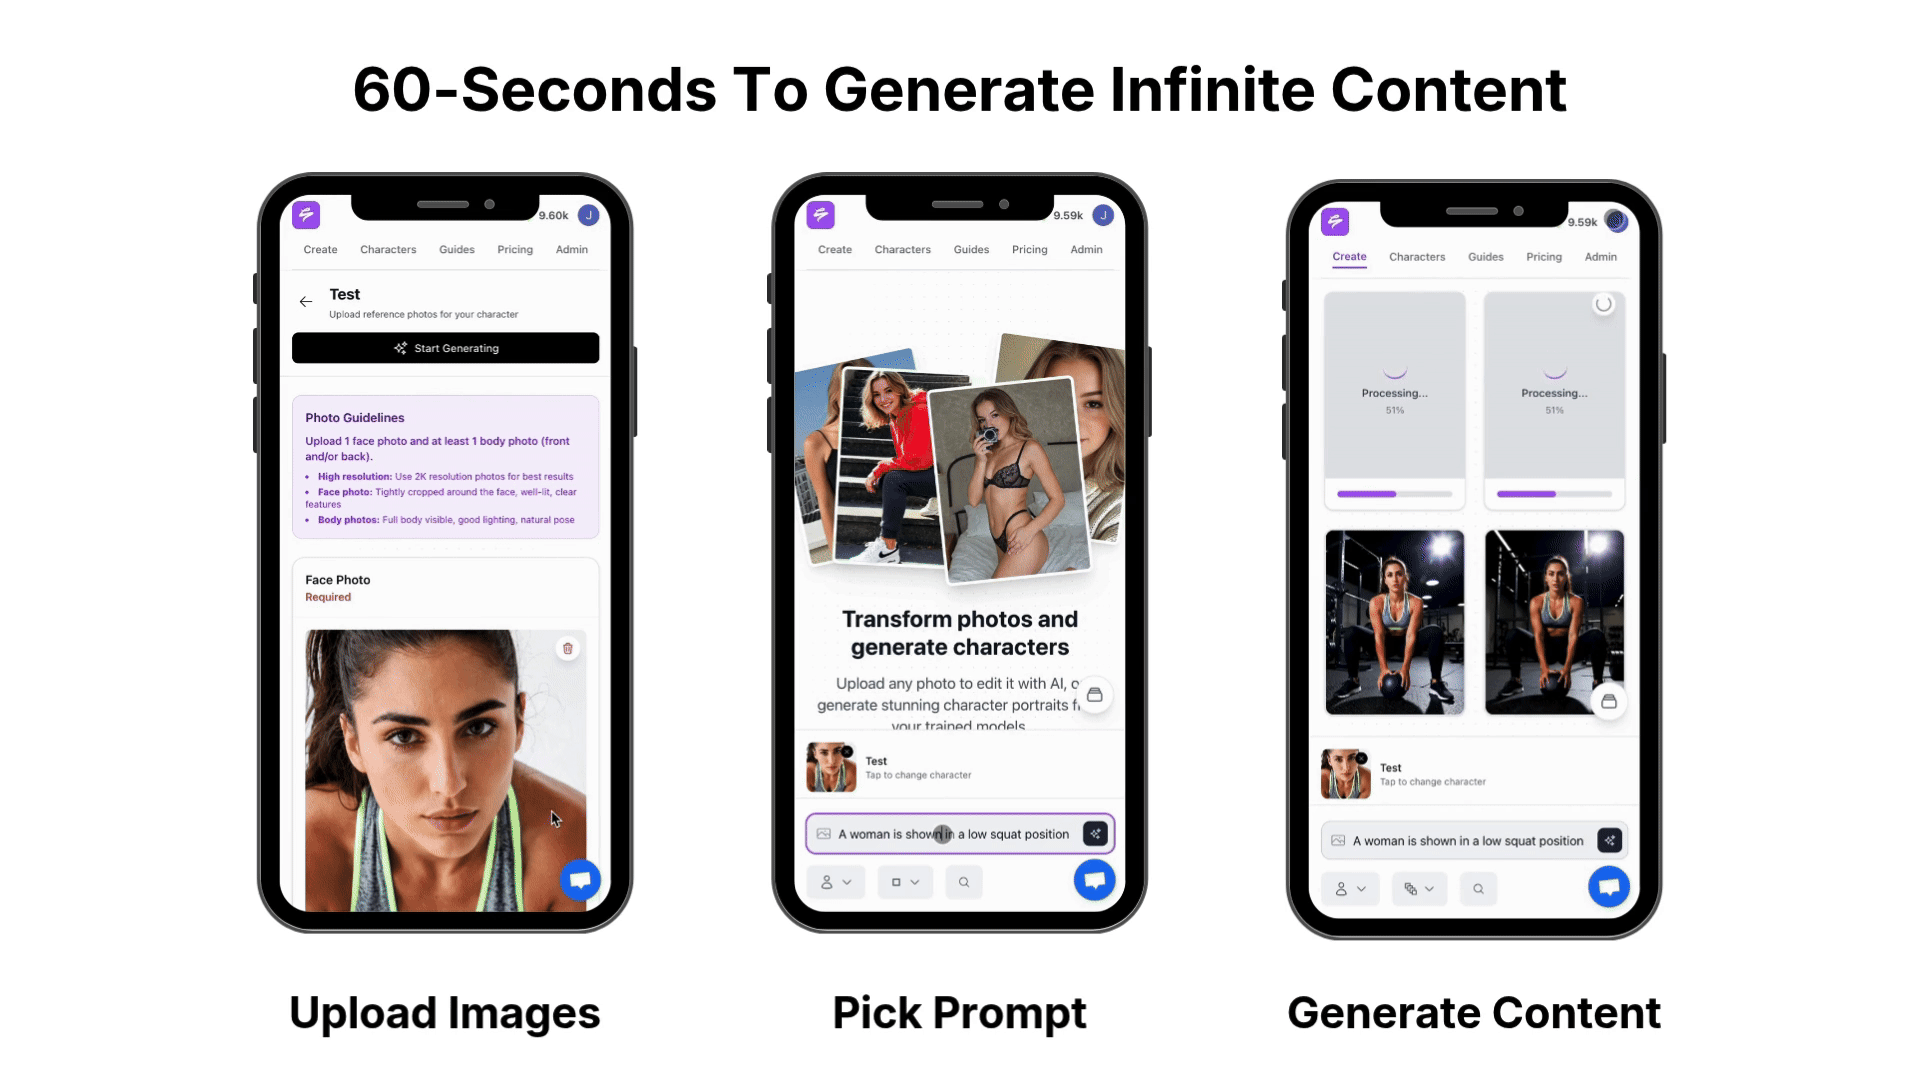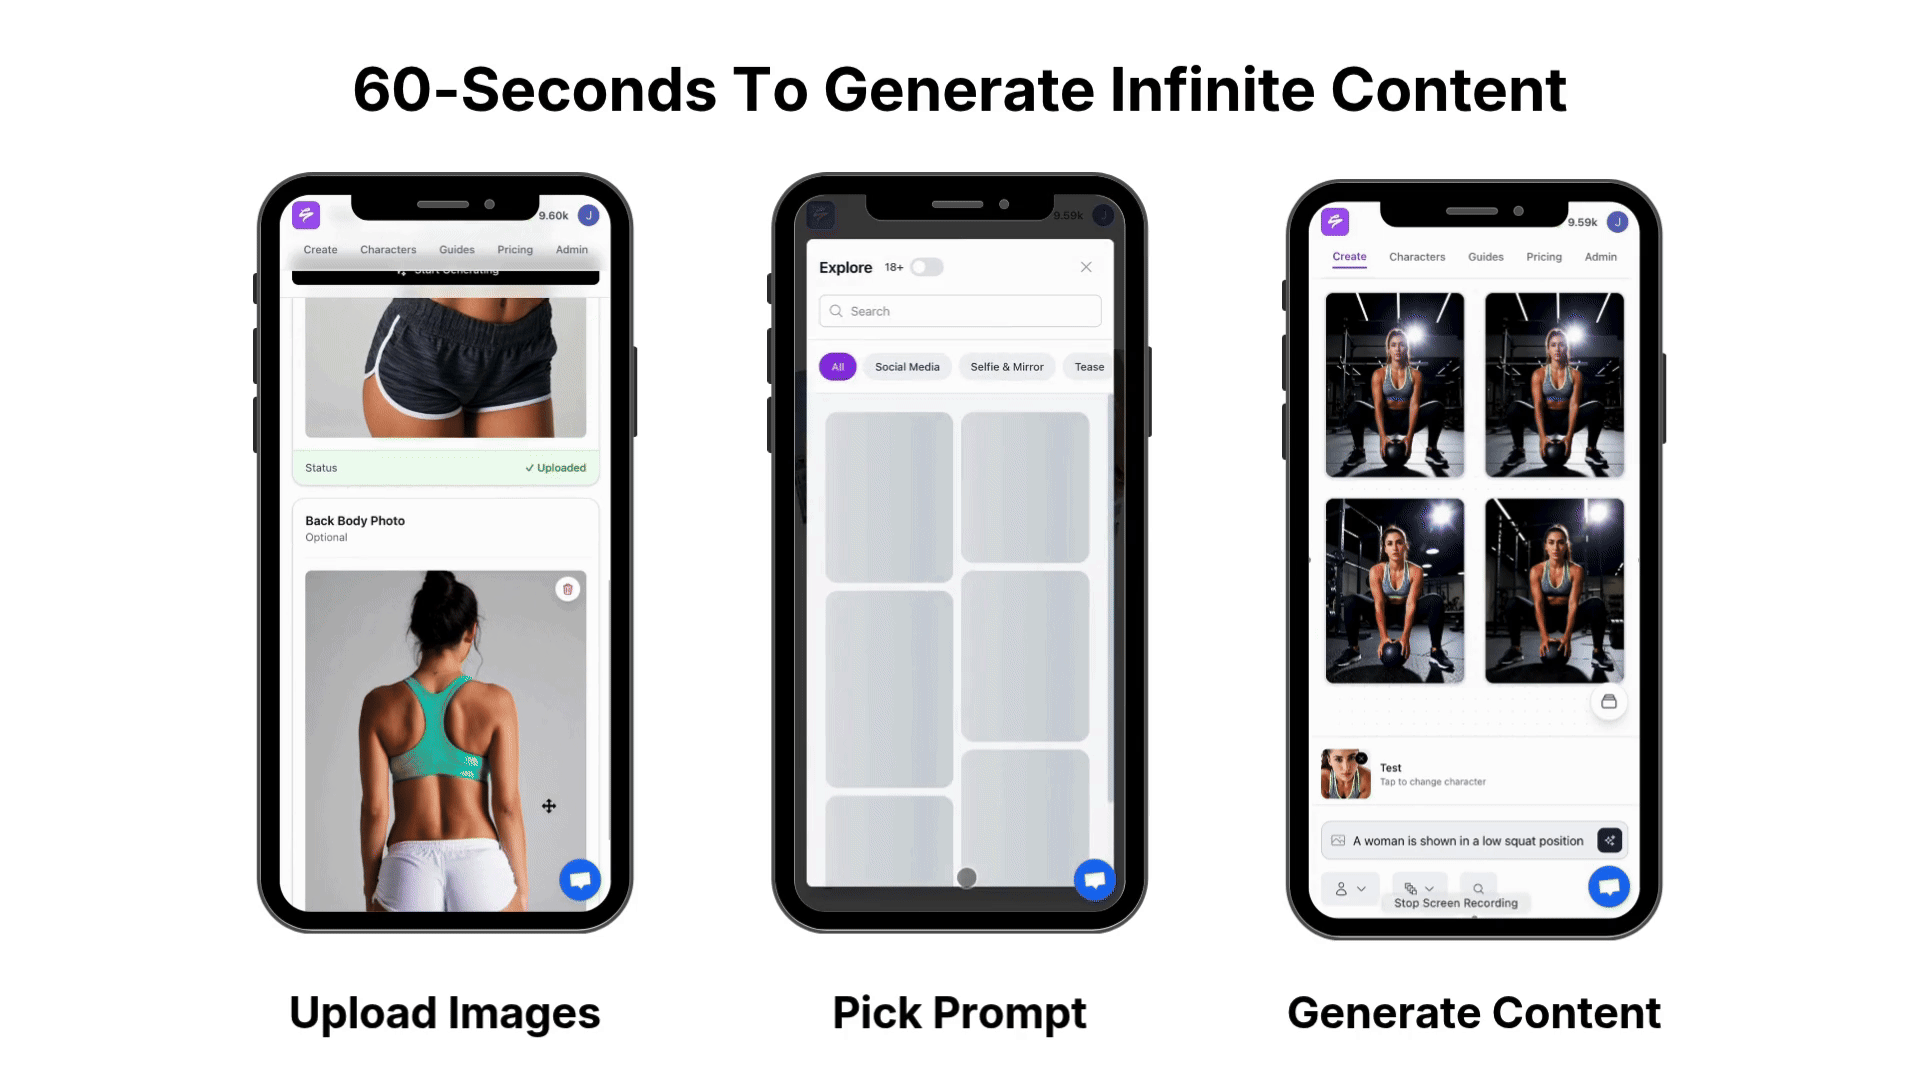
If the hardware and license gates above rule out self-hosting for your workload, a managed studio removes the setup burden entirely. Here is how the same tasks map to a hosted workflow. Sozee is the AI Content Studio for the Creator Economy, the managed alternative to running any of the above yourself.
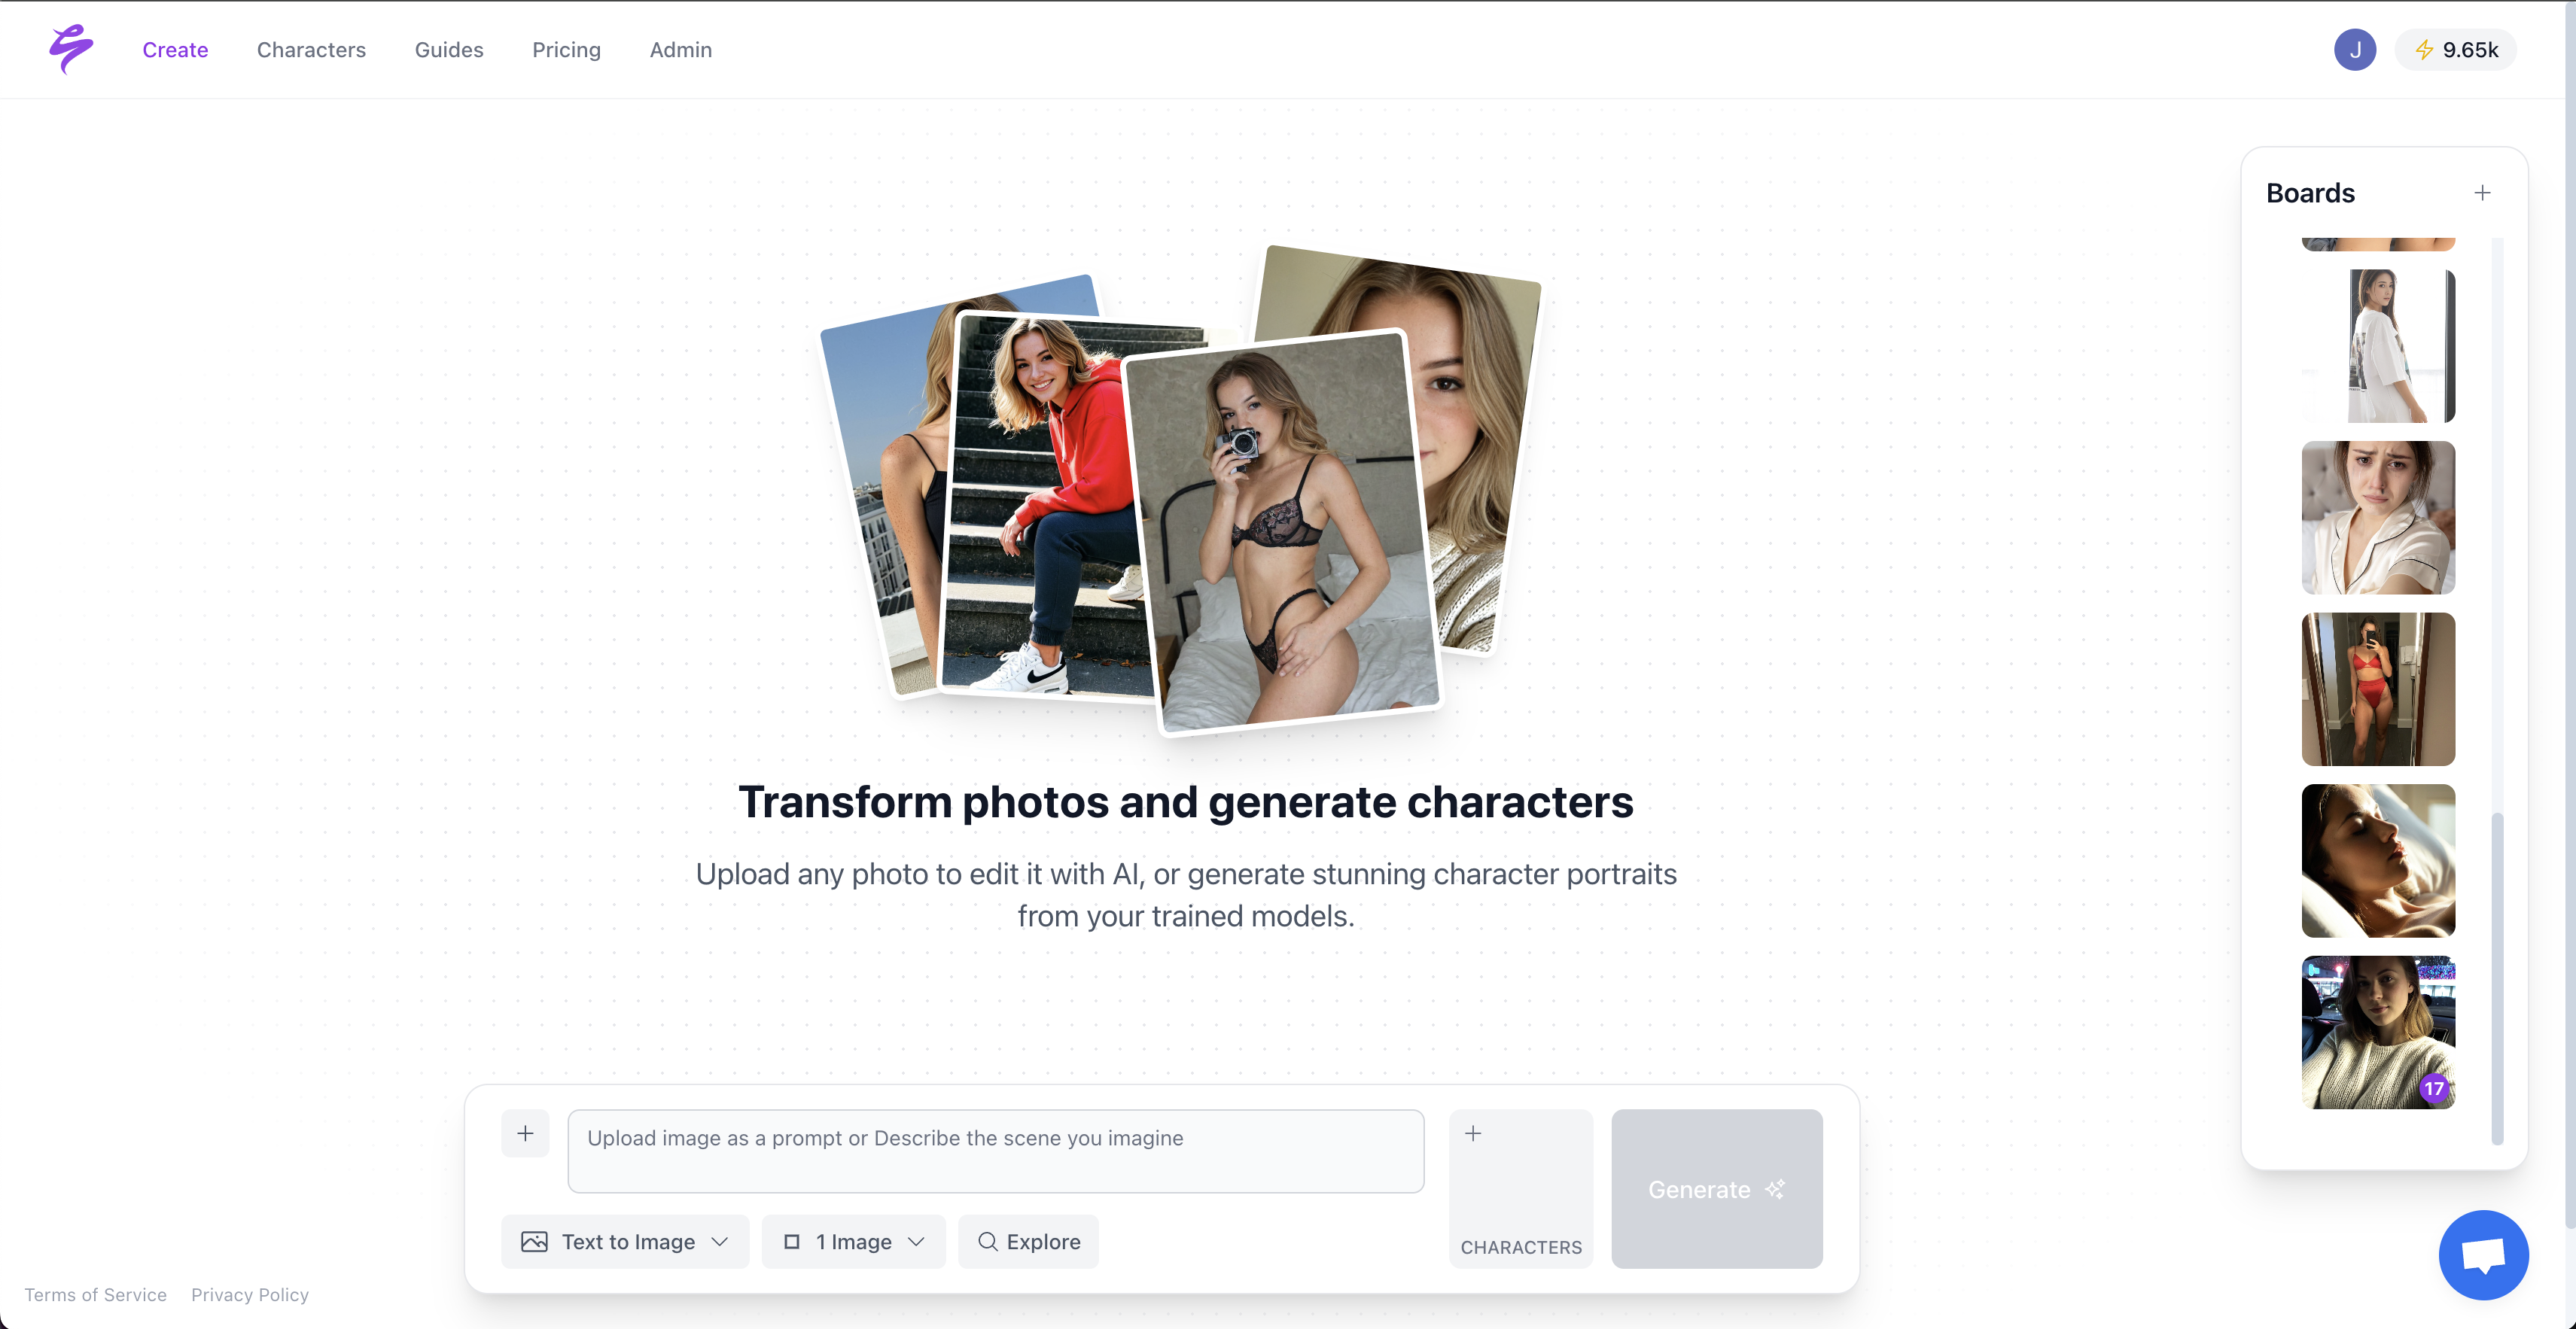
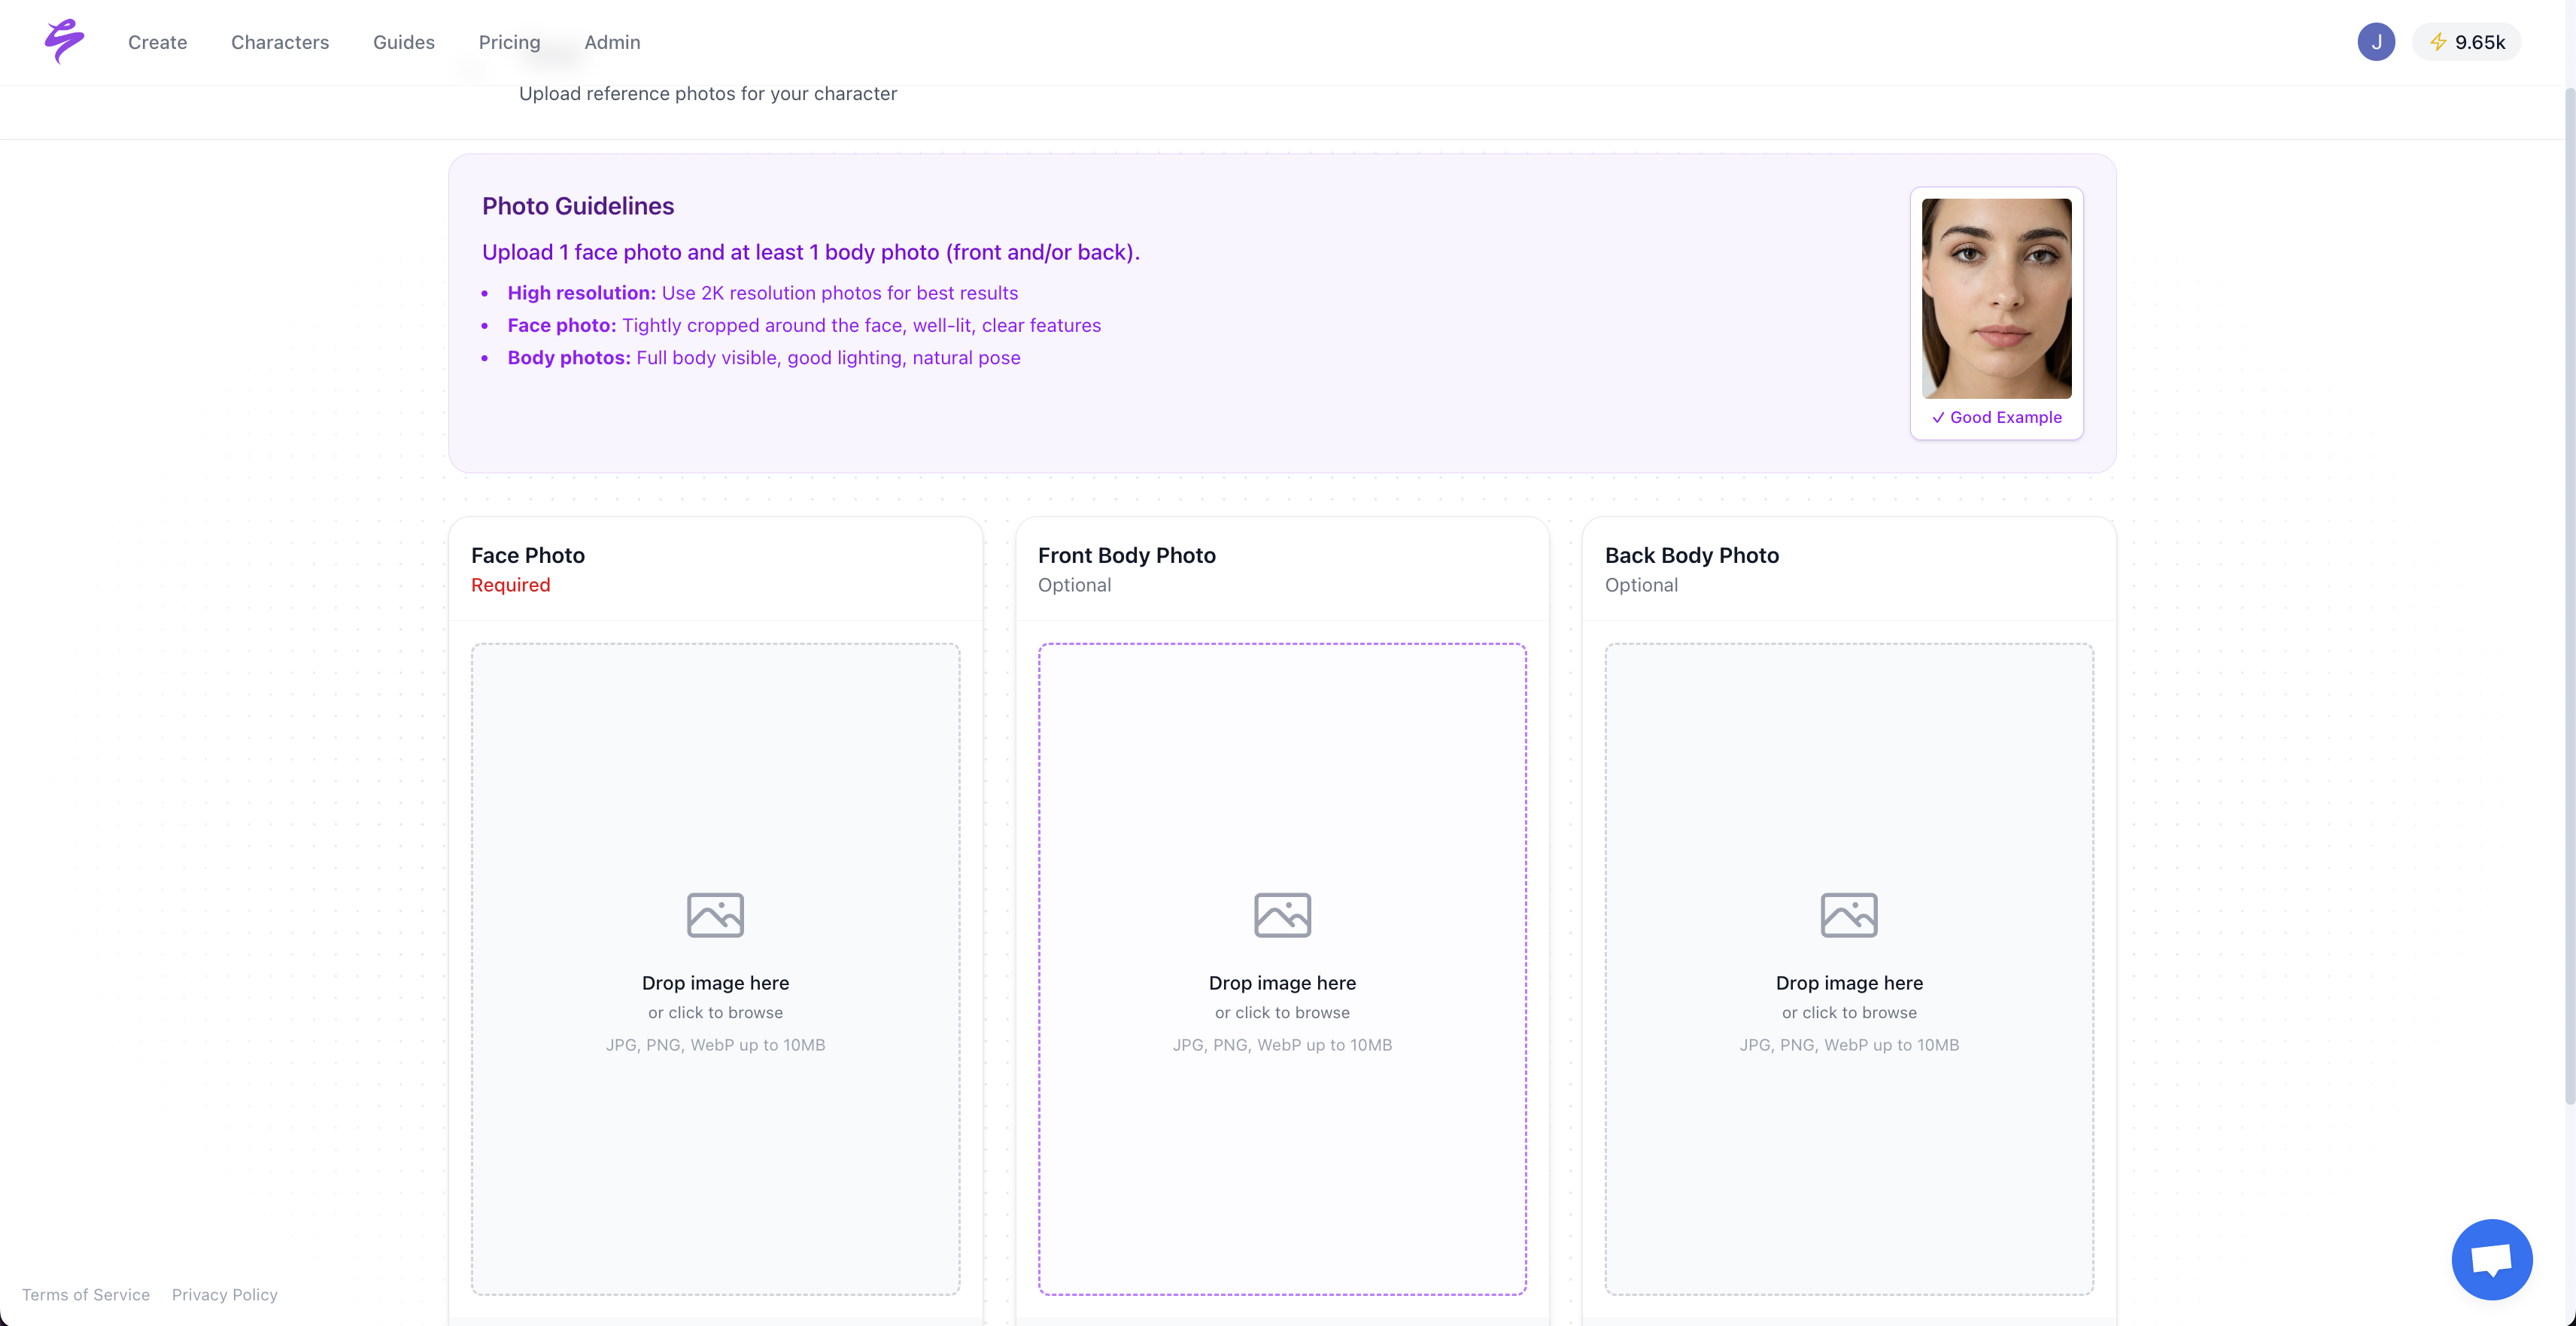
Upload as few as three photos and Sozee reconstructs your likeness with hyper-realistic accuracy. You can also generate an entirely original character from scratch, a face that has never existed, consistent from the very first frame. The setup work, including VRAM planning, quantization, license review, and manual stitching, is handled for you.
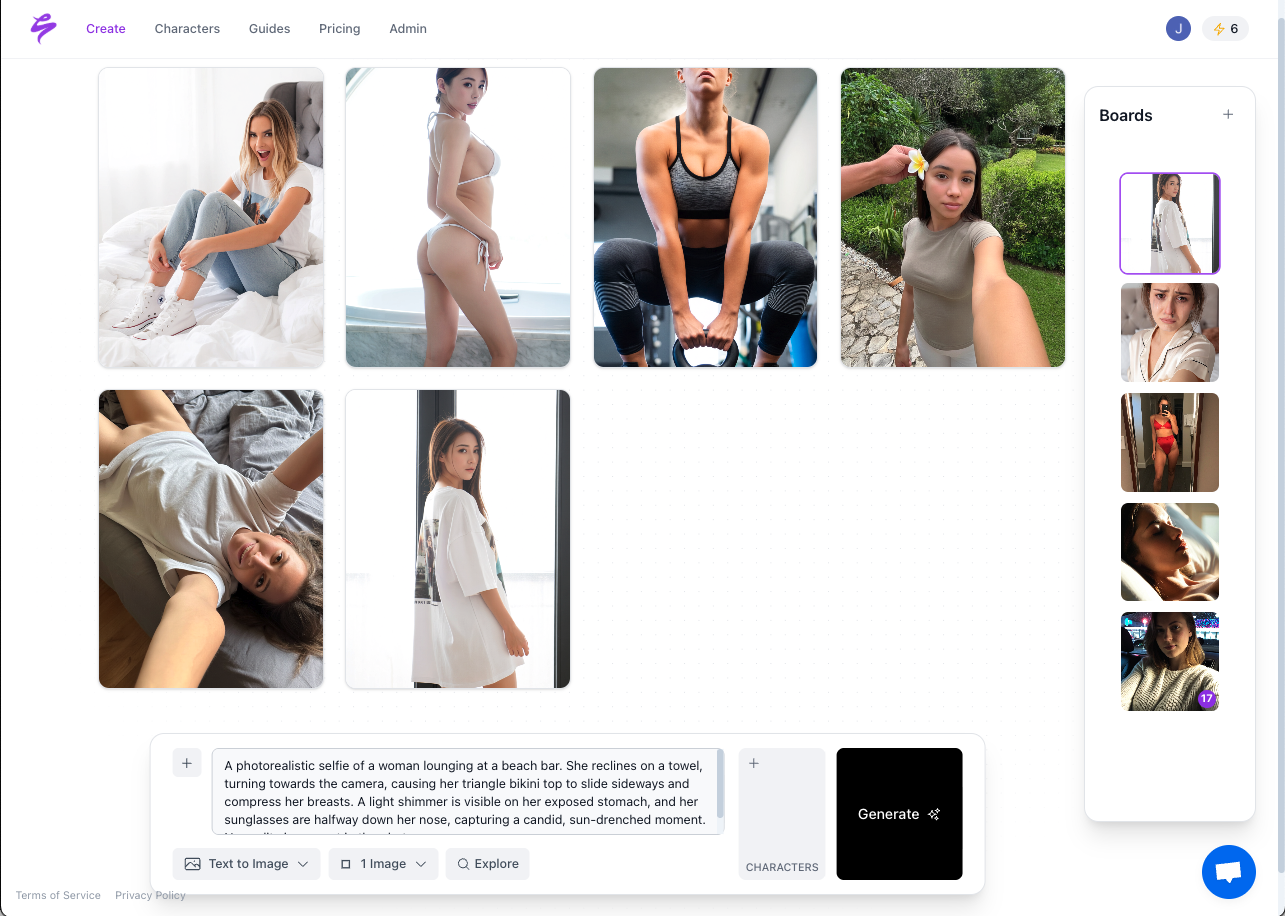
Where self-hosted models give you a generation, Sozee gives you a studio you run. Photo Control turns the prompt bar into a director’s panel with five dimensions you set deliberately every time: Setting, Outfit, Shot style, Expression, and Object. Because those dimensions stay fixed, likeness stays locked across every frame, every set, every week, and that consistency is what turns content into a brand.
The capabilities map directly to the problems raised earlier in this guide.
- Stitching And Length: Video generation up to 1080p and fifteen seconds, in every aspect ratio that matters, with reel cloning from an Instagram, TikTok, or YouTube link, so you start from a finished structure instead of raw clips.
- Reusable Environments: Reusable Settings built from up to four reference photos, Outfit libraries, and Object libraries that compound, so every shoot you set up makes the next one faster.
- Prompt Stability: Photo Shoot turns one image into a locked, coherent set of up to ten. The Agent interviews a half-formed idea into a finished setup and writes straight into the prompt bar and Photo Control panel, one tap from Generate.
- Publishing And Analytics: Native scheduling across Instagram, TikTok, X, Facebook, Reddit, and Fanvue, with a split between what Sozee posted and what you posted, so you can see exactly what the platform is worth.
Start your first managed studio session.
FAQ
Is Sora 2 Open Source?
As covered above, Sora 2 is proprietary and API-only, with a September 24, 2026 sunset. The open-weight alternatives are Wan 2.2, Mochi 1, and Open-Sora 2.0.
Can You Run Open Source Video Models On A Consumer GPU?
Yes, with the right model and the right optimization techniques. The tier breakdown above still applies: 8 GB fits Wan 2.2 TI2V-5B with offloading, 12–16 GB adds HunyuanVideo 1.5 at FP8, and 24 GB covers the 14B variants and Mochi 1 in bf16. The techniques that make lower tiers viable are quantization, distilled few-step inference, and CPU offloading.
What Is The Difference Between Open Source And Open Weights?
As defined earlier, open source requires full disclosure of training data, code, and weights under the OSI definition, while open weights only publishes the parameters. The practical difference is legal. An open-weight model can be a free download and still carry a license that prohibits commercial use, excludes certain jurisdictions, or restricts using outputs to train competing systems. Always read the LICENSE file in the model’s own repository before shipping.
Is There An Open Source AI Video Editor?
The four editors covered above, SynthCut, OpenCut AI, Timeline Studio, and Palmier Pro, remain the main options, with the same license caveats. Pick based on your platform, license tolerance, and need for MCP or browser-based workflows.
How Much Do AI Video Generators Cost?
Self-hosted open-weight models have no per-generation fee but carry real hardware, setup, and ongoing maintenance costs. The fully loaded cost multiplier discussed earlier, roughly 3-to-5× over raw GPU rental, is the key figure here. Self-hosting becomes economically competitive at high sustained volume, around thousands of clips per month with GPUs kept busy. Below that threshold, a managed API or a managed studio like Sozee typically costs less once fully loaded costs are counted.
Conclusion: Direct The Studio
Pick a model that clears your VRAM and license gates, choose ComfyUI or Diffusers based on how you work, and plan for stitching and editing from day one. If those constraints slow you down, hand the stack to a managed studio like Sozee and focus on directing the content instead of maintaining the hardware.