
Last updated: September 19, 2026
Key Takeaways
- AI content safety verification systems use multi-layer pipelines. They separate harm detection, provenance verification, and policy enforcement into distinct stages, each producing its own evidence.
- Creator platforms must answer three distinct questions: Is this harmful? Was it AI-generated? Does it violate policy? Collapsing them into one score produces false positive rates high enough to make enforcement unreliable.
- A six-stage verification pipeline (ingestion, safety detection, provenance checks, risk scoring, human review, audit logging) produces evidence that supports final policy decisions while keeping those decisions under human and organizational control.
- Provenance tools like C2PA Content Credentials and Google SynthID verify AI generation but cannot determine harm or policy compliance, so platforms must interpret these signals separately from safety classifiers.
- Sozee embeds verification into the creator workflow through locked-likeness characters, reusable assets, and scheduling so provenance is captured at inception instead of reconstructed later.
Start Building Safer Creator Workflows With Sozee
Why Creator Platforms Need A Verification Pipeline
Creator platforms face three separate questions about every piece of content.
- Is This Content Harmful? This is a harm-detection question answered by classifiers trained on categories like sexual content, violence, hate, harassment, and self-harm. Leading providers report 90–97% precision on standard benchmarks, but performance drops significantly for nuanced categories and non-English content.
- Was This Content AI-Generated Or Manipulated? This is a provenance question answered by C2PA Content Credentials, Google SynthID, and metadata analysis.
- Does This Content Violate Platform Policy Or Law? This is a policy question that depends on jurisdiction, age-gating rules, and the platform’s own terms of service.
A single model cannot answer all three questions reliably. A classifier that flags sexual content cannot determine whether that content was AI-generated. A provenance signal that confirms AI generation cannot determine whether the content is harmful or allowed. In 2025 academic testing, GPT-4-based content moderation produced false positive rates of 58–82% depending on content category, which reflects this conflation problem.
The Multi-Layer Verification Pipeline
A defensible verification architecture for creator platforms uses six stages. Each layer answers a different question and produces evidence that supports the final policy decision while keeping that decision separate.
- Ingestion And Metadata Capture. When content enters the platform, the system captures available metadata, including file type, creation timestamp, device information, and any embedded provenance data such as C2PA Content Credentials. This layer establishes what the platform knows about the file before analysis begins. It cannot detect harm or verify provenance if metadata has been stripped.
- Safety Detection. Classifiers evaluate content against harm categories including sexual content, violence, hate, harassment, self-harm, and platform-specific policy categories. These models return confidence scores instead of binary verdicts. Benchmark estimates place hate speech detection at 85–92% accuracy with 5–10% false positives, while self-harm detection runs 82–88% with 8–12% false positives. Hate speech detection in low-resource languages remains a documented gap, with only a handful of African languages handled with any consistency by major models.
- Synthetic-Content And Provenance Detection. This layer checks for C2PA Content Credentials, Google SynthID watermarks, and other provenance signals. C2PA Content Credentials attach cryptographically signed metadata recording how a file was created and edited, but screenshots or re-encoding strip that data. SynthID embeds an imperceptible watermark directly into pixels, audio waveforms, or text token patterns, surviving common transformations. This layer answers whether content was AI-generated, while harm and policy remain separate questions.
- Risk Scoring. The system combines signals from safety detection and provenance detection into a risk score, and the score then feeds into the policy decision instead of replacing it. That distinction matters most when the two signal types diverge. A high-confidence synthetic-content signal should trigger labeling or review, while a high-confidence harm signal should trigger removal or human review depending on severity and jurisdiction.
- Human Review. Edge cases, appeals, and ambiguous content route to human reviewers. Human moderators can review roughly 1,500–2,000 items per 8-hour shift. They catch context-dependent harm, coordinated behavior, and policy evasion that automated systems miss. Human review also protects creators from wrongful bans, which create business risk for platforms that depend on creator retention.
- Audit Logging. Every decision, confidence score, model version, and reviewer action is logged for compliance, incident analysis, and model improvement. NIST AI 600-1 recommends maintaining detailed logging of inputs, outputs, model versions, and environmental conditions to support effective incident analysis and regulatory disclosure.
Build Verification Into Your Pipeline
Pre-Upload Screening And Post-Upload Monitoring
Verification pipelines also depend on when checks run. Timing shapes what each layer can catch.
Pre-upload screening catches obvious violations before distribution but cannot assess context. It operates on the file as submitted, without conversation history, user behavior, or downstream context. It is fast and prevents exposure but produces false positives on legitimate content that superficially resembles violations. A 5% false positive rate on 10 million daily messages produces 500,000 review items per day, which becomes expensive when thresholds are not calibrated per content category.
Post-upload monitoring catches context-dependent harm, coordinated behavior, and policy evasion but allows exposure before removal. It operates on published content and can incorporate user reports, engagement patterns, and cross-content analysis. It is slower and allows harmful content to reach audiences before enforcement.
A hybrid model balances these tradeoffs. Pre-upload screening handles high-confidence violations and provenance checks. Post-upload monitoring handles context-dependent harm, appeals, and emerging abuse patterns. Confidence-based routing—auto-approving items below 0.6, queuing items between 0.6 and 0.9 for human review, and auto-rejecting items above 0.95 with an appeal path provides a practical operational framework for the handoff between automated and human enforcement.
Synthetic Content Detection With C2PA Content Credentials And Google SynthID
C2PA Content Credentials and Google SynthID are complementary provenance tools that solve different halves of the same problem. The table below shows why neither can substitute for the other: C2PA carries rich origin data but is fragile, while SynthID survives editing but only confirms that a participating model was involved.
| Standard | What It Verifies | Persistence | Platform Adoption |
|---|---|---|---|
| C2PA Content Credentials | Origin and edit history via signed metadata manifest | Stripped by screenshots, re-encoding, or unsupported software | TikTok, Meta, Google Pixel, OpenAI |
| Google SynthID | AI generation by participating models via embedded watermark | Survives cropping, compression, and common transformations | Google, OpenAI, NVIDIA, Kakao, ElevenLabs |
| Safety Classifiers | Harm categories via confidence scores | N/A (analysis, not embedded signal) | Azure AI Content Safety, Hive Moderation, OpenAI Moderation |
TikTok became the first video-sharing platform to implement C2PA Content Credentials in May 2024, enabling automatic reading of provenance metadata from tools like DALL-E and Adobe Firefly. When content carries C2PA signals, TikTok applies the AIGC label automatically on upload. C2PA’s effectiveness depends on the manifest being created at the file’s inception and preserved by every subsequent application. If any software that does not support C2PA touches the file, the chain breaks and cannot be repaired.
As of May 2026, Google reports over 100 billion images and videos plus 60,000 years of audio carry SynthID watermarks. OpenAI, NVIDIA, Kakao, and ElevenLabs have adopted SynthID. Unlike C2PA, SynthID embeds a signal distributed across the whole image or passage rather than sitting in one region, so metadata strippers leave the SynthID signal intact.
The critical distinction is that provenance verification answers whether content was AI-generated. A positive SynthID result means the content passed through a participating generation system. A negative result establishes almost nothing: the content may be human-made, generated by a non-participating model, or stripped of its watermark. Treating either result as a harm signal leads platforms to over-remove legitimate AI-generated content.
The Decision Model For Policy Outcomes
Model confidence feeds into the final policy decision, and the platform then chooses an outcome. The table below maps six possible outcomes, from unrestricted publishing to removal, and shows which combination of signals triggers each one.
| Policy Outcome | Trigger Conditions | Platform Action |
|---|---|---|
| ALLOW | No violation detected; provenance confirms authentic capture or acceptable AI use | Content publishes without restriction |
| ALLOW+LABEL | Synthetic-content signal detected; no harm detected | Content publishes with AI disclosure label |
| LIMIT DISTRIBUTION | Moderate harm signal or policy-sensitive content | Content publishes with reduced reach or restricted surfaces |
| AGE_GATE | Adult content detected; platform permits with verification | Content restricted to verified adult users |
| HUMAN_REVIEW | Ambiguous signal, low confidence, or appeal | Content held or flagged for reviewer decision |
| REMOVE | High-confidence harm signal; policy violation confirmed | Content removed; creator notified with appeal path |
The governing rule is straightforward. A high-confidence synthetic-content signal should trigger labeling or review, while automatic removal stays reserved for harm signals. YouTube’s policy confirms that applying AI disclosure labels alone does not impact a video’s recommendations or monetization eligibility. The platform evaluates content independently based on audience signals.
See How Sozee Separates Signals From Policy
Human Review, Appeals, And Creator Protection
Human review provides the safeguard that automated pipelines cannot match. Wrongful bans create business risk for creator platforms because they drive creators to competitors, generate negative press, and erode trust in enforcement.
An appeal overturn rate above 15% for a specific violation category signals a model or policy problem. Every overturned decision should feed back into model training to improve future accuracy.
Appeal and re-review workflows work best with clear timelines, reviewer independence, and feedback loops into model training. A four-hour appeal response SLA is a reasonable baseline for social platforms and 24 hours for forums, tracked as a primary service-level objective.
Verified creator status establishes identity. It does not certify that individual content is safe. A verified creator can still upload content that violates policy. This distinction matters particularly for platforms operating SFW-to-NSFW content workflows, where creator identity verification and content policy enforcement remain separate functions.
Keeping those functions separate reflects the kind of organizational discipline that governance frameworks formalize.
Governance With The NIST AI Risk Management Framework
The NIST AI Risk Management Framework (AI RMF 1.0) organizes risk management into four functions: Govern, Map, Measure, and Manage. The Generative AI Profile (NIST AI 600-1) extends this framework with twelve generative-AI-specific risk categories, including information integrity, obscene or abusive content, and data provenance.
For content moderation, NIST AI 600-1 recommends several practices.
- Pre-Deployment Testing. Organizations deploying generative AI must conduct their own TEVV (Test, Evaluate, Verify, Validate) across all 12 GenAI risk categories. Vendor attestation of model safety testing does not satisfy a deployer’s obligations.
- Provenance Documentation. NIST AI 600-1’s Data Provenance category requires organizations to maintain records of training data lineage and to apply provenance verification where feasible. For third-party models, vendors are expected to supply model cards and system cards as a condition of procurement.
- Incident Disclosure. The logging requirement described earlier forms the foundation for incident disclosure. NIST AI 600-1 adds that platforms should establish clear escalation paths for AI incident response.
- Ongoing Measurement. NIST AI 600-1 recommends that content filtering and moderation systems be continuously updated. Static filtering approaches often prove inadequate against sophisticated prompt engineering and jailbreaking attempts.
NIST AI 600-1 is voluntary but increasingly referenced in federal procurement and sector-specific regulatory guidance. Platforms that align with its recommendations position themselves for future regulatory requirements, including those emerging from EU AI Act Article 50, which became applicable on August 2, 2026, with penalties reaching €15 million or 3% of worldwide turnover for non-compliance. Those requirements collide most sharply with one business model in particular: platforms that monetize legal adult content.
The Creator-Platform Tension: NSFW Monetization And Safety Enforcement
Many creator platforms monetize adult content legally while enforcing safety rules. A blanket ban approach treats all adult content as equivalent and ignores the distinction between legal adult content created by verified adults and prohibited content such as CSAM or non-consensual intimate imagery. NIST AI 600-1 recommends that organizations develop specific acceptable-use policies addressing content that violates laws or organizational values, including CSAM and non-consensual intimate imagery.
Three mechanisms reconcile monetization with compliance, each operating at a different level. Age-gating restricts adult content to verified adult users. Geofencing applies jurisdiction-specific rules. Tiered distribution limits reach for policy-sensitive content without removing it entirely. TikTok’s enforcement model illustrates this tiered approach: C2PA auto-detection labels incoming content, systems flag realistic synthetic media that should have been labeled, and prohibited content triggers immediate removal and account action. These tracks operate in parallel.
Platforms that cannot distinguish legal adult content from prohibited content face both business and regulatory risk. Over-removal drives creators and revenue to competitors. Under-enforcement invites payment-processor and regulatory scrutiny.
How Sozee Fits Into Verification Architecture
Sozee gives creator platforms a way to operationalize verification without slowing creators down. Sozee builds compliance and verification into creator onboarding and content setup instead of adding it as a late-stage gate.
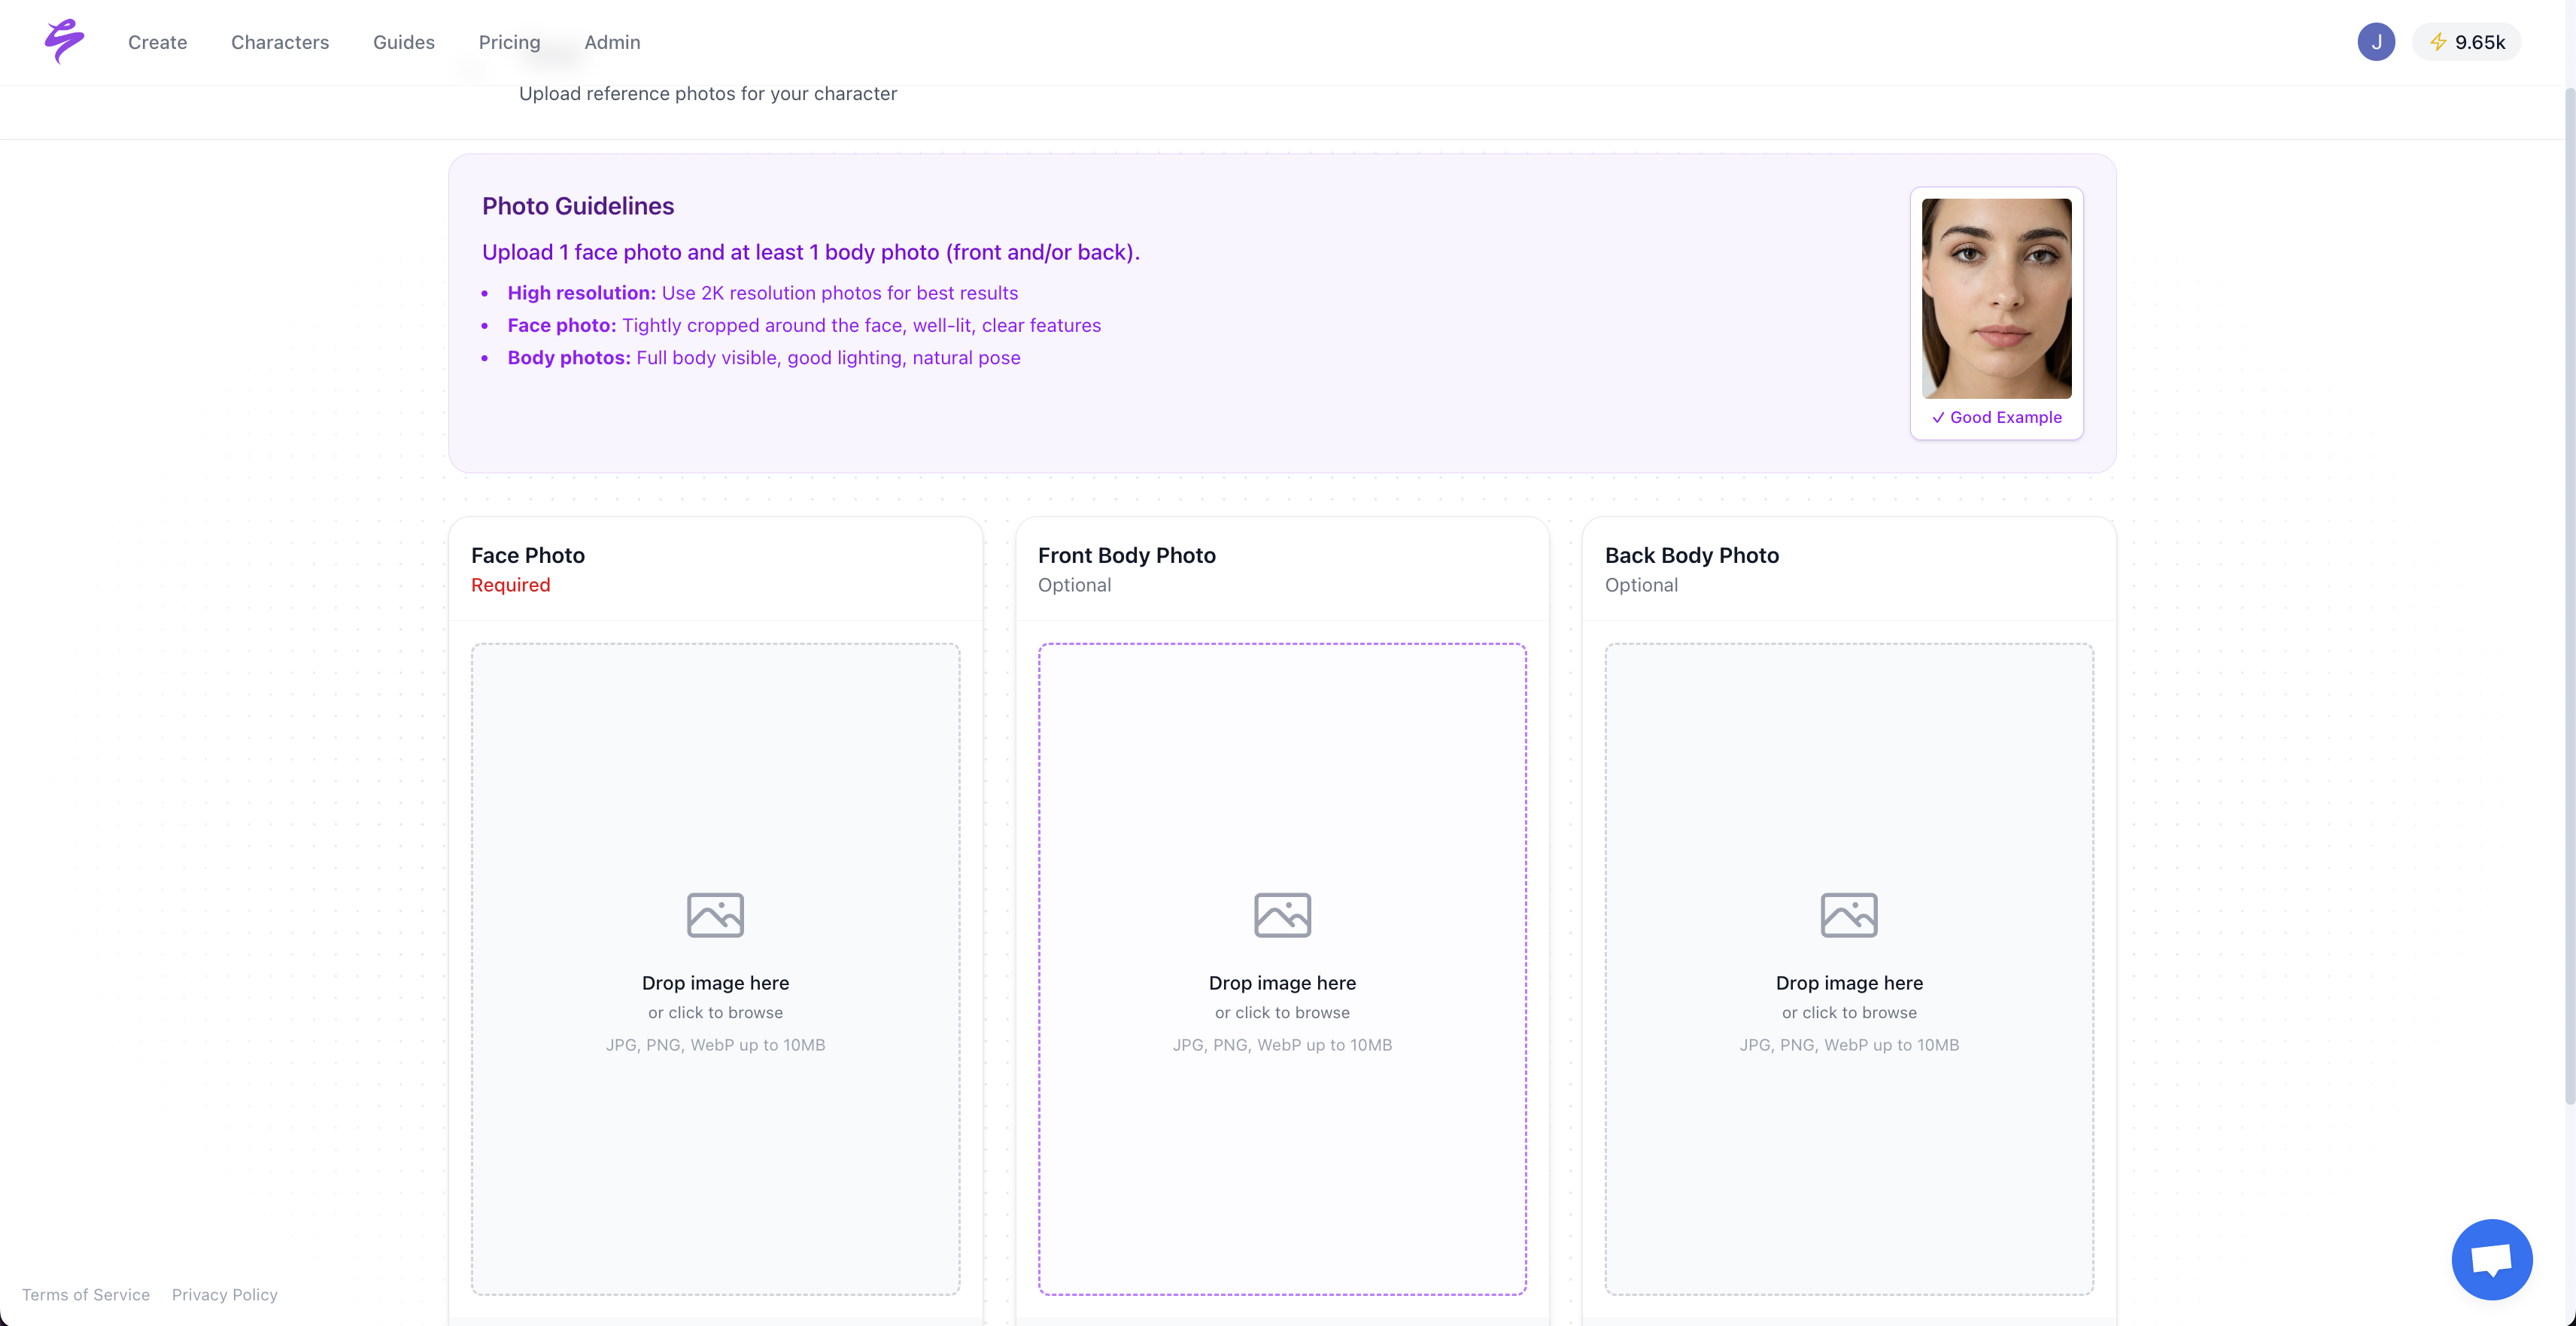
For platforms and agencies evaluating verification architecture, Sozee provides several building blocks.
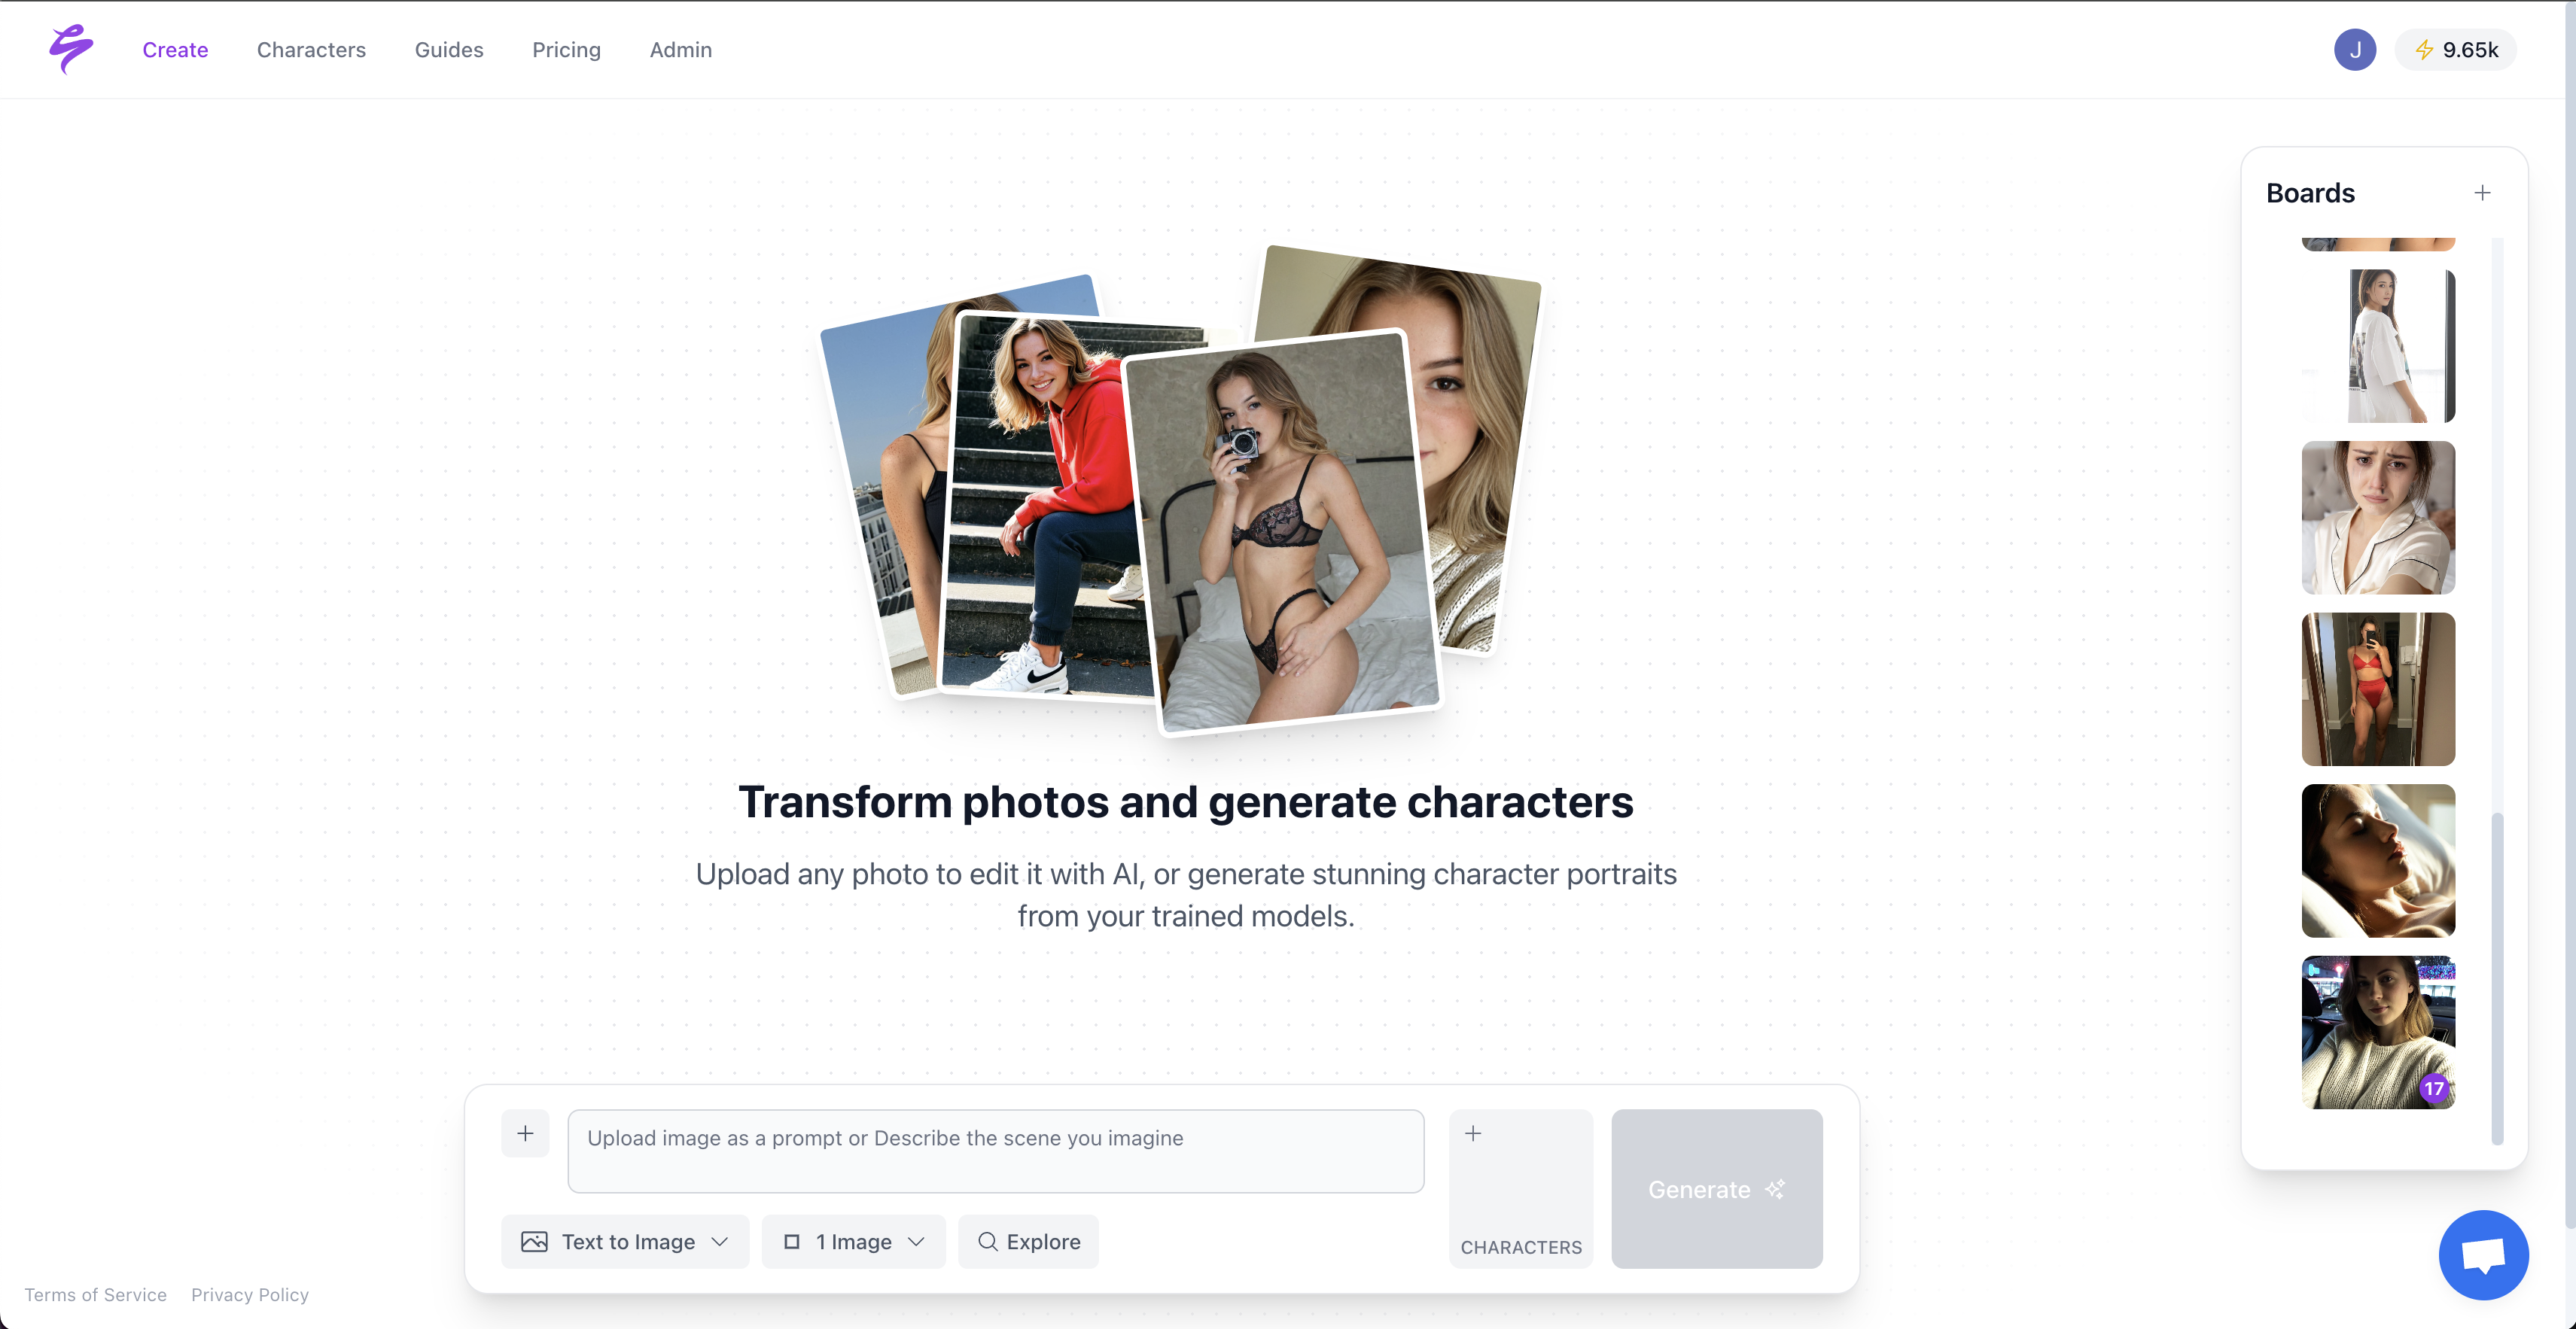
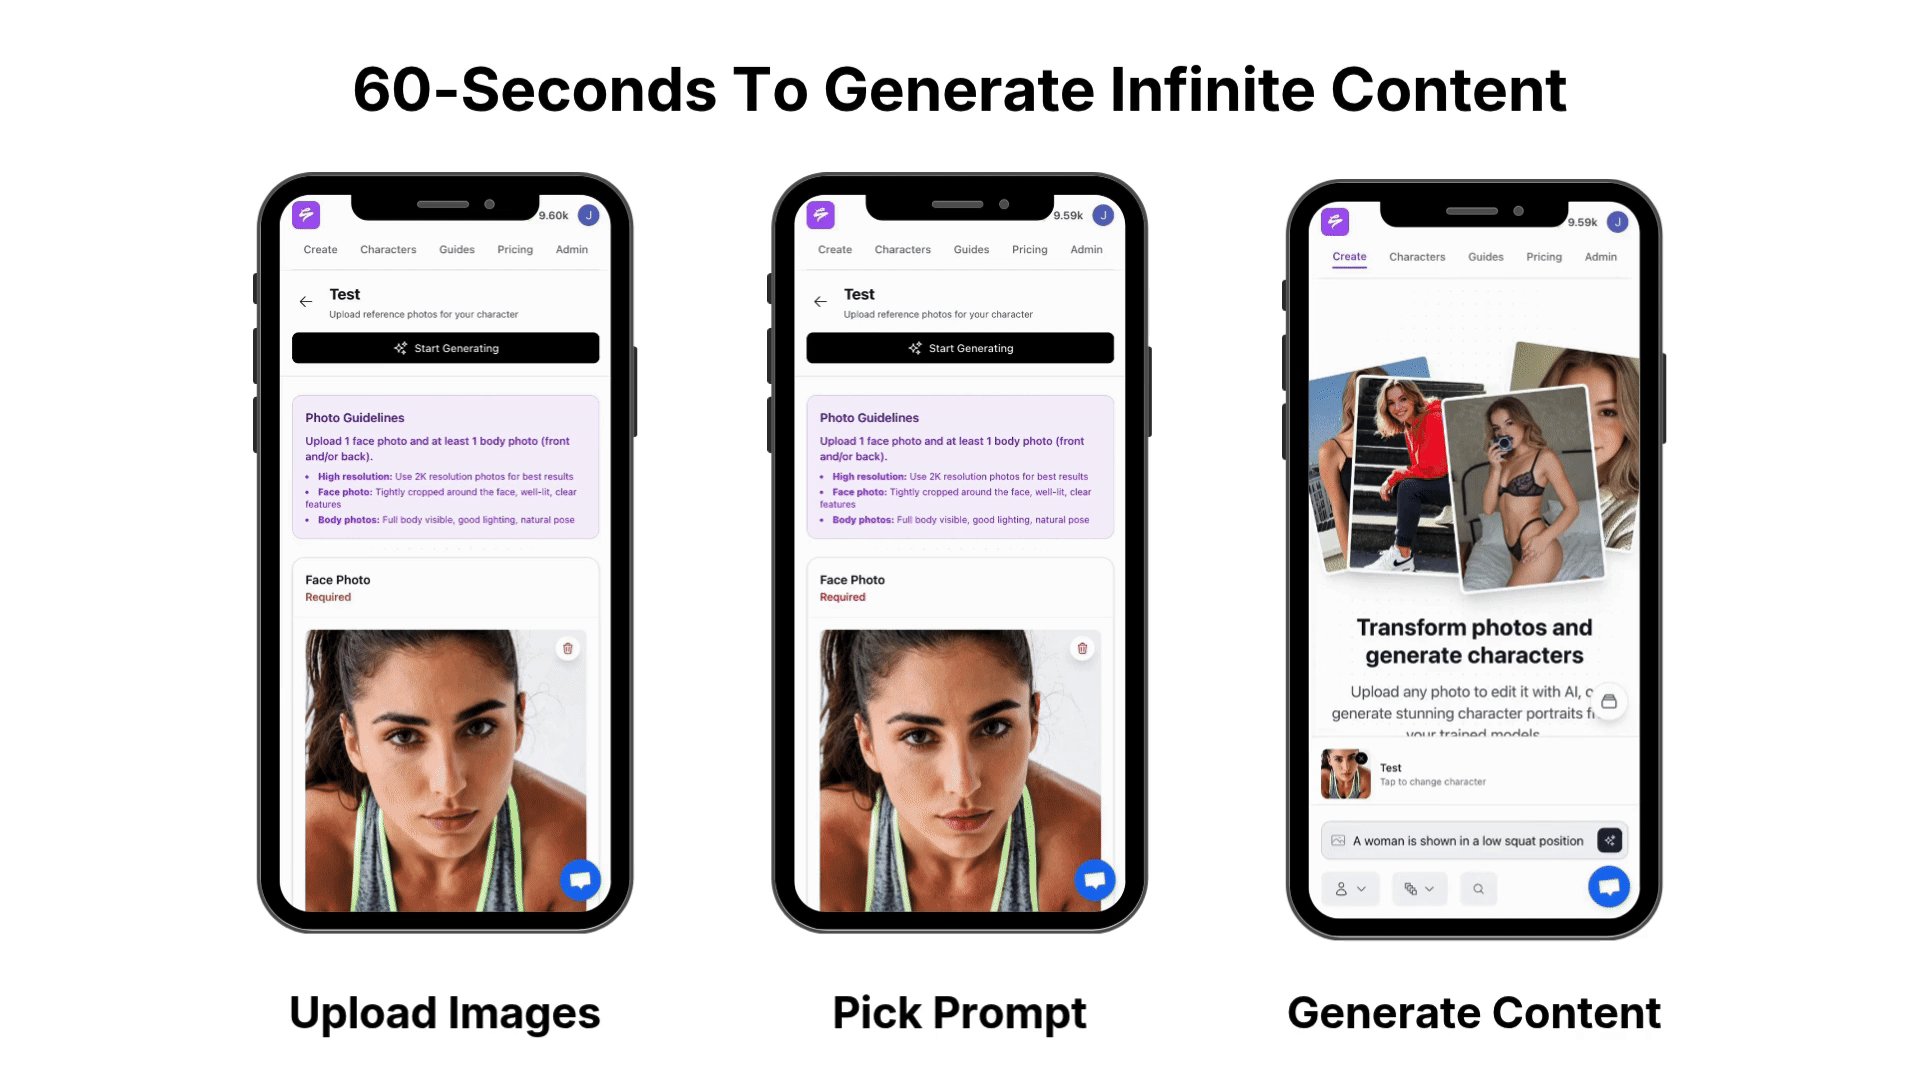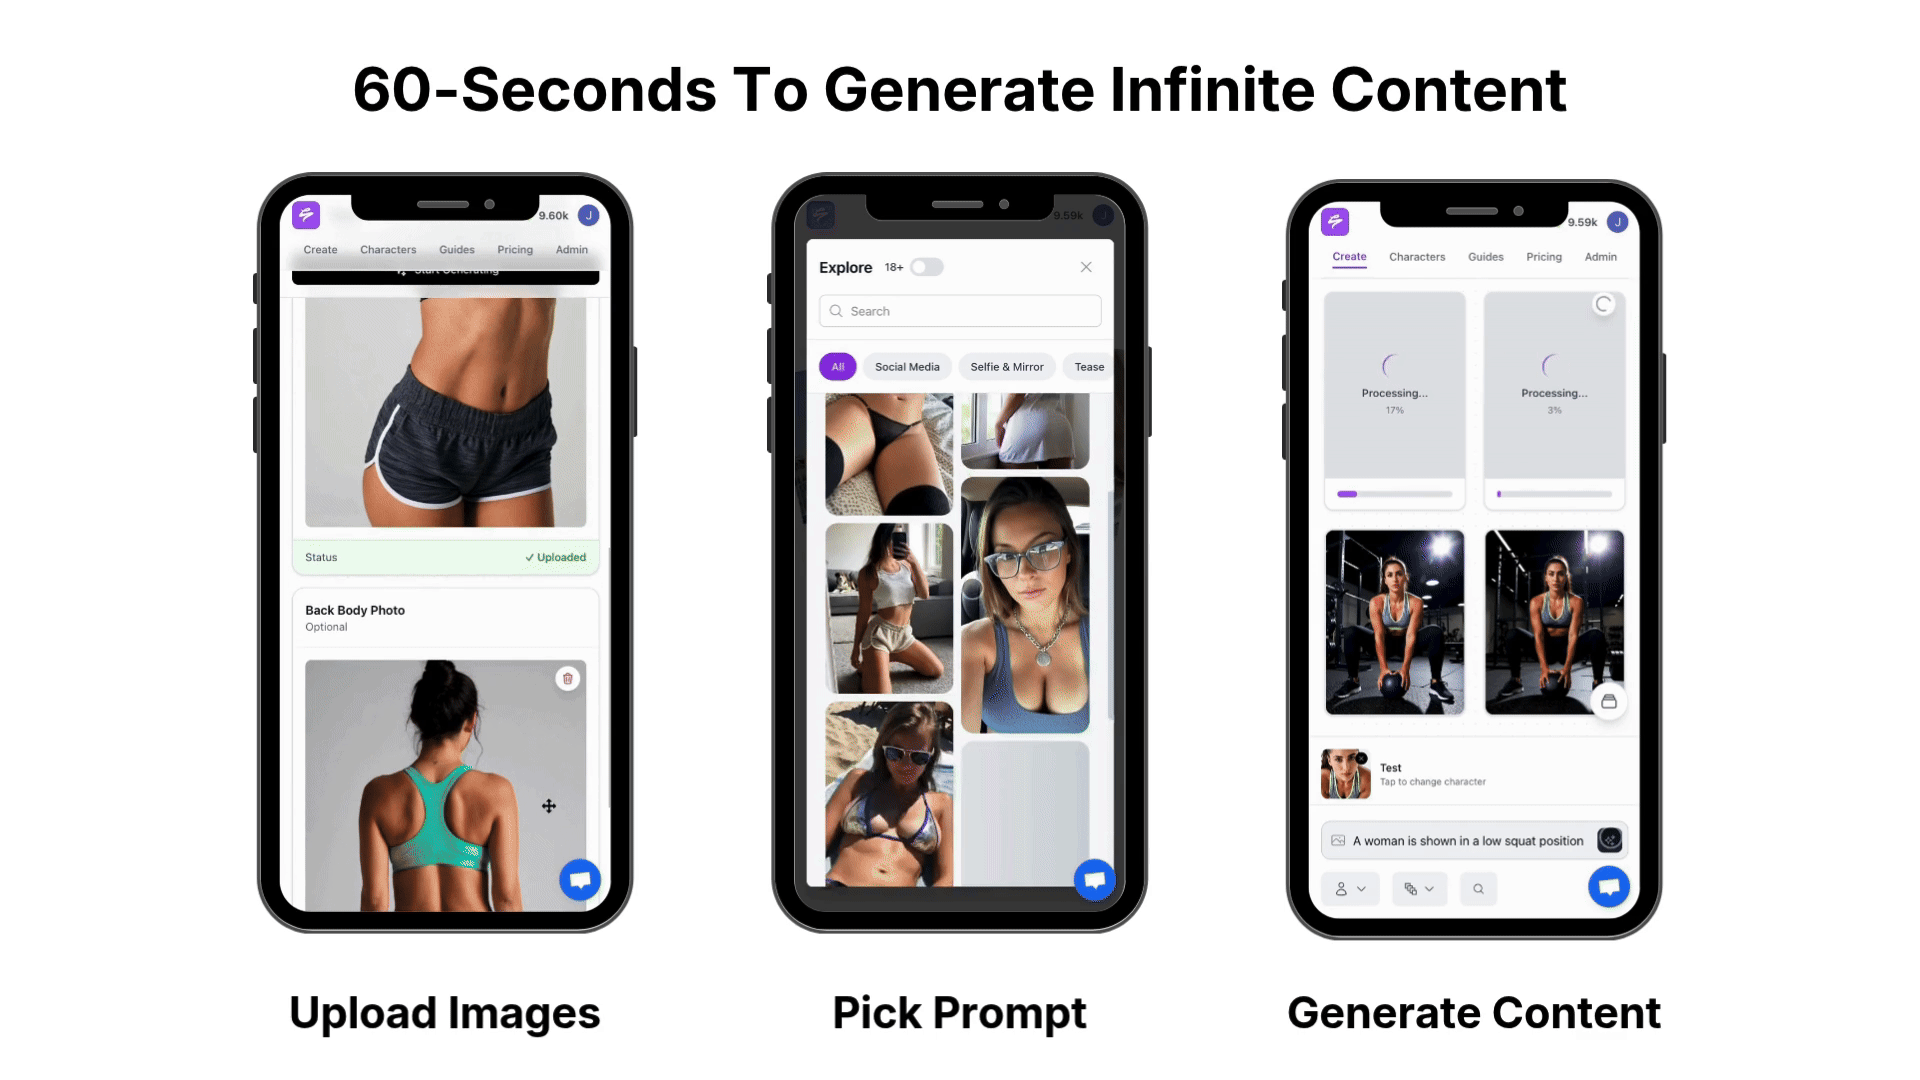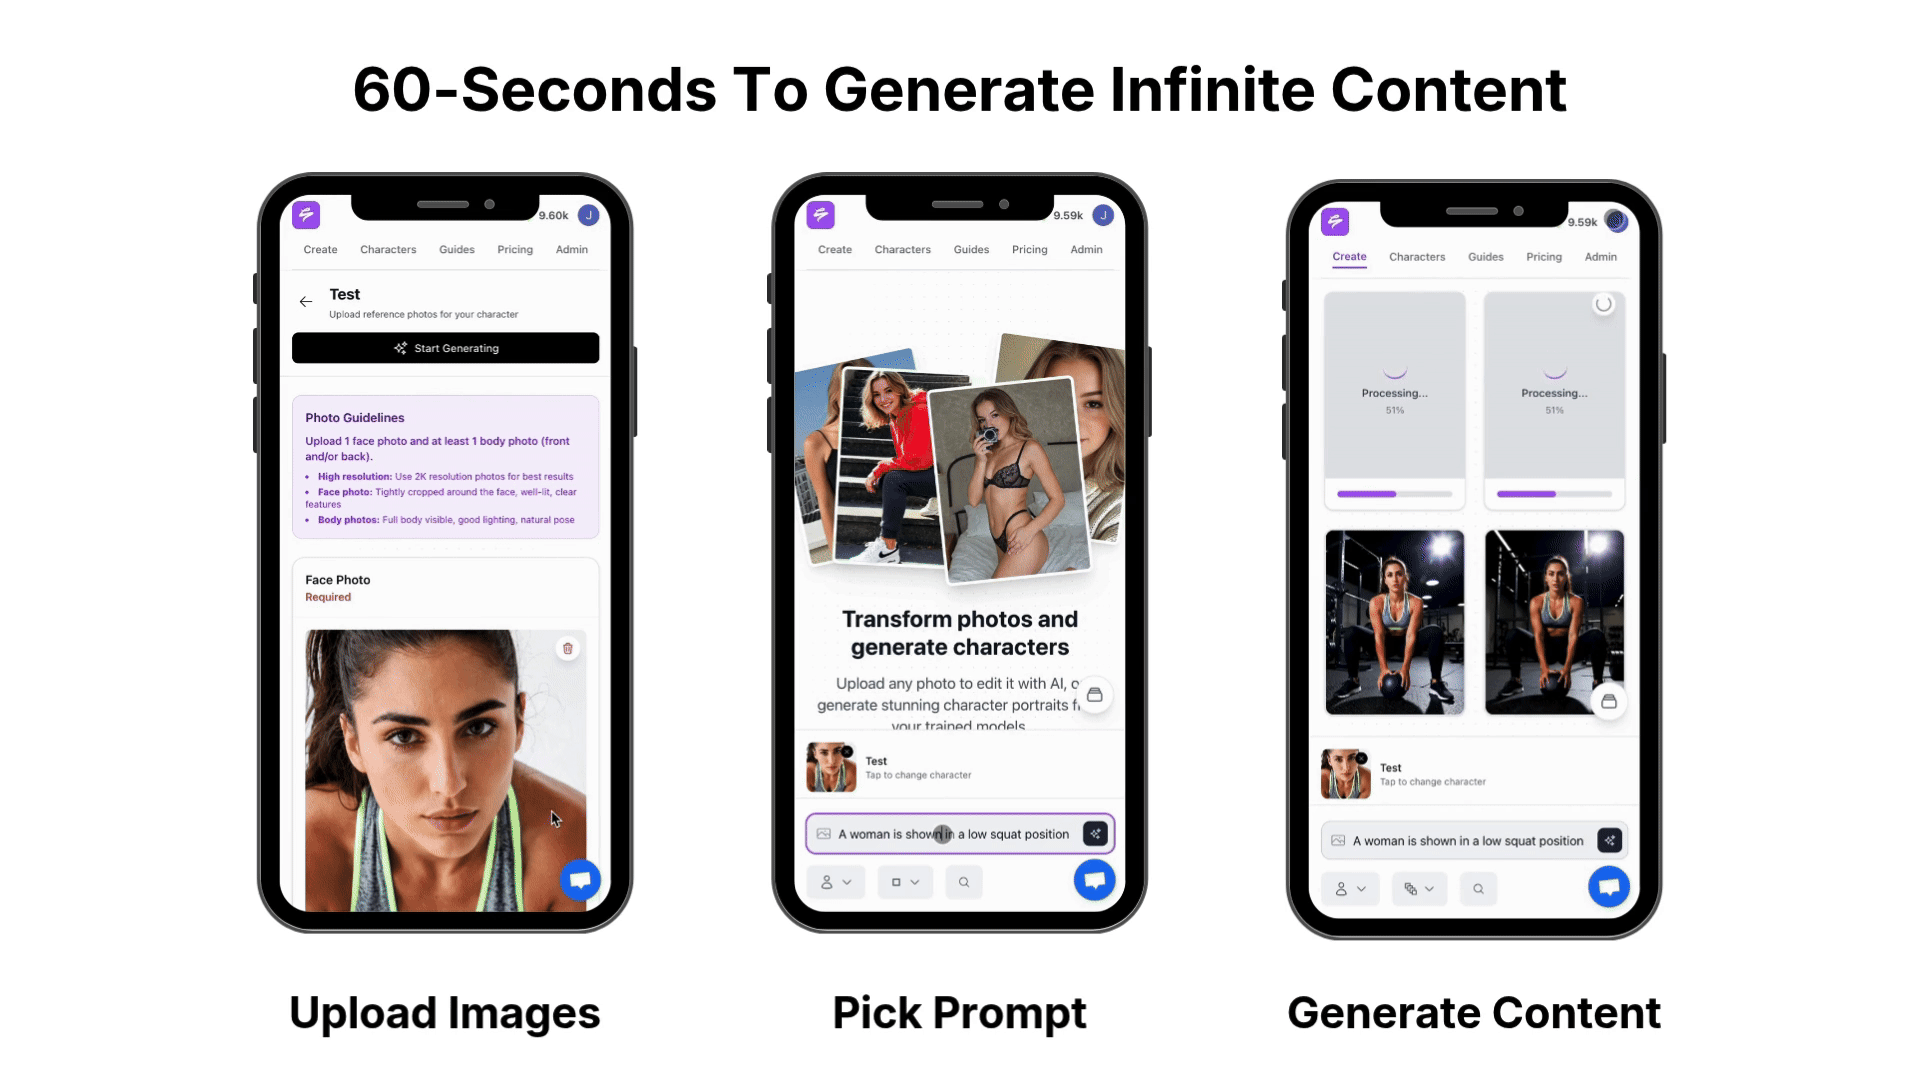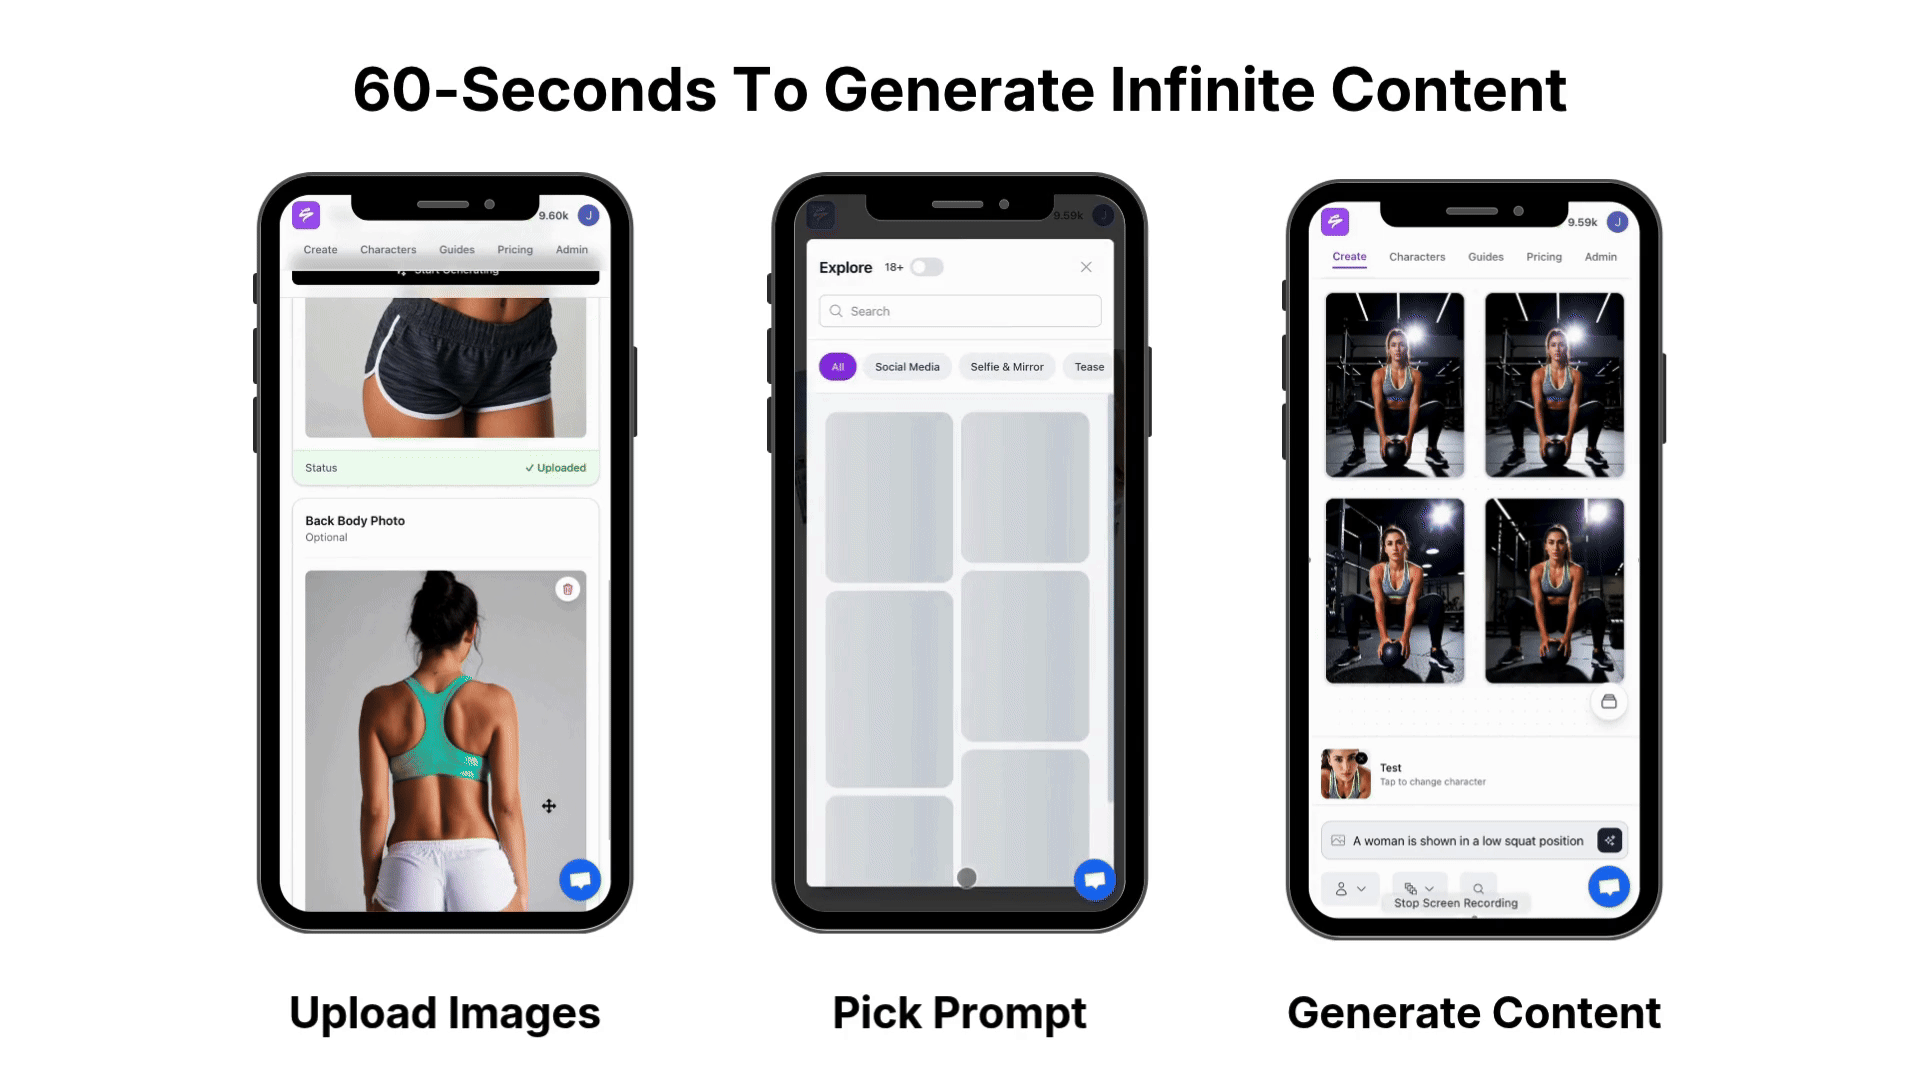
- Locked-Likeness Character System. Creators upload as few as three photos to reconstruct their likeness with hyper-realistic accuracy or generate an entirely original character. Because that likeness stays locked across every frame, set, and week, the content’s origin is established at inception, which makes provenance and policy enforcement tractable at scale.
- Reusable Environments. Settings, outfits, and objects become assets creators own and re-attach at will. A location built once can be reused for a year. This approach reduces the volume of new content requiring verification and creates a consistent provenance record for each asset.
- Scheduling And Analytics. The Scheduler connects Instagram, TikTok, X, Facebook, Reddit, and Fanvue per character instead of per account. Analytics separate what Sozee posted from what the creator posted, providing audit-ready records of content origin that support regulatory disclosure requirements.
- SFW-To-NSFW Workflows With Creator-Set Ceilings. Sozee supports a full SFW-to-NSFW arc where the creator sets the pacing and the ceiling. This design aligns with age-gating and tiered distribution models and allows platforms to enforce policy without blanket bans.
Sozee’s architecture treats verification as a feature of the creation workflow. For platform product leads and trust and safety engineers, this means provenance data is captured at inception, when the content is created, instead of reconstructed after distribution.
Capture Provenance At Inception
Frequently Asked Questions
How Does AI Content Verification Work In A Multi-Layer Pipeline?
The pipeline has six stages, described in full above. The short version: ingestion captures what the platform knows, safety and provenance detection answer separate questions, risk scoring combines them, and human review plus audit logging handle the cases automation cannot.
What Are The Known Failure Modes Of AI Content Moderation Classifiers?
Failure modes cluster by category and language. Hate speech detection runs 85–92% accuracy in high-resource languages but drops to 60–75% for low-resource languages or niche dialects. Self-harm and misinformation carry the higher false positive rates noted earlier. Context-dependent harm, coded language, sarcasm, cultural nuance, and code-switching consistently defeat classifiers trained on formal text. Deepfake detection false negative rates range from 5% in controlled lab tests to more than 30% in the wild when adversarial edits or low video quality are present. Platforms should measure false positive and false negative rates per content category and language and retrain models quarterly using newly labeled edge cases and emerging abuse patterns.
How Do C2PA Content Credentials And Google SynthID Complement Each Other?
C2PA Content Credentials and Google SynthID address different aspects of provenance. C2PA attaches a cryptographically signed manifest to a media file recording its origin and edit history, which screenshots, re-encoding, or unsupported software can strip. SynthID embeds an imperceptible watermark directly into pixels, audio waveforms, or text token patterns at generation time. The signal is distributed across the whole file and survives cropping, compression, and common transformations that destroy C2PA credentials. The EU Code of Practice, finalized July 20, 2026, effectively requires at least two marking layers for audio, images, and video. OpenAI’s dual-layer approach—SynthID for a durable embedded signal plus C2PA for verifiable metadata—follows this layered architecture. Both tools answer whether content was AI-generated by a participating system, while harm and policy remain separate questions.
What Does NIST AI 600-1 Require For Creator Platform Content Moderation?
NIST AI 600-1, the Generative AI Profile published July 26, 2024, extends the NIST AI RMF 1.0 with twelve generative-AI-specific risk categories relevant to creator platforms, including information integrity, obscene or abusive content, data provenance, harmful bias and homogenization, and human-AI configuration. For content moderation, it calls for pre-deployment TEVV across all risk categories, records of training data lineage plus provenance verification where feasible, detailed logging to support incident analysis and disclosure, and continuous updating of content filtering systems. It also recommends structured adversarial red-team exercises before and after deployment, conducted by personnel independent of the development team. The profile remains voluntary for private-sector organizations but increasingly shapes procurement and regulatory expectations.
How Should Platforms Handle The NSFW Monetization Vs. Safety Enforcement Tension?
Platforms that monetize legal adult content while enforcing safety rules benefit from a tiered enforcement architecture. The tiered enforcement architecture described above—age-gating, geofencing, and tiered distribution—provides the practical toolkit. The harder question concerns where to draw the line between legal adult content and prohibited categories such as CSAM or non-consensual intimate imagery. That line requires separate enforcement tracks instead of a single content score. Verified creator status establishes identity, while content compliance depends on ongoing enforcement. Platforms that fail to maintain this distinction either over-remove legitimate content or under-enforce prohibitions, which invites payment-processor and regulatory scrutiny. NIST AI 600-1 recommends that acceptable-use policies explicitly address CSAM and non-consensual intimate imagery as distinct prohibited categories.
Conclusion: Building Verification Into The Creator Workflow
AI content safety verification systems for creator platforms function as layered pipelines of evidence, policy, and reviewability rather than single models that declare content safe. The architecture described in this guide—six-stage pipeline, pre-upload and post-upload enforcement, C2PA and SynthID provenance, a decision model that separates confidence from policy, human review and appeals, and NIST AI 600-1 governance—offers a defensible framework for platform product leads and trust and safety engineers evaluating build-versus-buy decisions.
Platforms that build verification into the creation workflow, capturing provenance at inception instead of reconstructing it after distribution, operate with a structural advantage in both compliance and creator retention.
Sozee builds compliance and verification into creator onboarding and content workflows, making provenance and policy enforcement tractable at scale. For platforms and agencies that need to operationalize verification without slowing creators down, Sozee provides the infrastructure.
Deploy A Creator-Ready Verification Stack