
Last updated: September 10, 2026
Key Takeaways
- Hardware requirements depend on workload. Image LoRAs lean on VRAM, resolution, and batch size. LLM LoRAs depend on sequence length. Video LoRAs stress storage and multi-GPU throughput.
- VRAM tiers range from 8 GB for SD 1.5 LoRAs to 50–70 GB for Flux.2 Dev. QLoRA shrinks language-model footprints to roughly 8–16 GB for 7B–13B models.
- Architecture compatibility is strict. SDXL LoRAs and Flux LoRAs do not mix, so checking tensor-key patterns and metadata before training prevents silent failures.
- Software stack compatibility (Python 3.10+, PyTorch 2.4+, PEFT 0.18+, bitsandbytes) and system RAM at least 2× VRAM reduce OOM errors and version conflicts.
- If your hardware falls short, a no-training platform can generate consistent characters from three photos without a GPU or local setup.
How Much VRAM Is Required To Train A LoRA?
The table below maps workload to VRAM tier. Every figure comes from primary sources cited inline. Standard LoRA columns assume FP16 or BF16 base weights. QLoRA columns assume 4-bit NF4 quantization via bitsandbytes.
| Workload | Standard LoRA VRAM | QLoRA VRAM | Example GPU |
|---|---|---|---|
| SD 1.5 LoRA | 8 GB minimum, 12 GB recommended | 8 GB practical minimum (with memory optimizations) | RTX 3060 12 GB |
| SDXL / Pony / Illustrious LoRA | 16 GB recommended, 24 GB comfortable | 10 GB minimum (fused backward pass with Adafactor in bf16) | RTX 4070 Ti Super 16 GB |
| Flux.1 Dev / Schnell LoRA | Just over 30 GB for unquantized training, 32 GB recommended | ~9 GB with QLoRA | RTX 3090 / 4090 24 GB |
| Flux.2 Dev LoRA | Roughly 50–70 GB in 8-bit, ~60 GB recommended | 24 GB minimum | RTX 5090 32 GB |
| 7B LLM LoRA | ~20 GB at rank 16, ~22 GB at rank 64 (FP16 base) | 8–10 GB (NF4 base) | RTX 4070 Ti Super 16 GB |
| 13B LLM LoRA | 26–40 GB (FP16 base) | 12–16 GB (NF4 base) | RTX 3090 / 4090 24 GB |
| Video LoRA (Wan 2.2 / HunyuanVideo) | ~24 GB practical minimum | Not standard | A100 / H100 80 GB |
A 30-image SDXL LoRA takes approximately 30–60 minutes on an RTX 4090, and Flux LoRAs take roughly 2× longer on the same hardware. Training time is the second half of the hardware equation. That gap widens on smaller cards, so a 12 GB card finishes the same SDXL LoRA at much longer wall-clock times than a 24 GB-class card.
How Workload Type Sets Your Hardware Bottleneck
The VRAM table gives a starting tier, but the real bottleneck depends on the kind of LoRA you train.
Image LoRA training is bottlenecked by VRAM plus resolution and batch size. Moving from 512×512 to 1024×1024 multiplies pixel count by four and sharply increases memory pressure, and batch size scales memory use directly, so generating four images at once needs far more VRAM than generating one. Resolution and batch size are the two levers to pull when an image run hits OOM.
LLM LoRA and QLoRA training are bottlenecked by VRAM plus sequence length and batch size. In standard attention layers, doubling sequence length from 2048 to 4096 tokens roughly quadruples attention activation memory (the T² term in M_act ≈ L·B·T·(34d + 5hT)), while other activations only double. A configuration that fits at 2048 tokens often OOMs at 4096 on the same card.
Video LoRA training is bottlenecked by storage and multi-GPU throughput. Musubi-tuner’s documentation reports 24 GB or more VRAM, roughly double its 12 GB image guidance, and runs take hours rather than minutes. Sequence length and batch size stretch across temporal dimensions, and the Wan 2.2 frame-count formula (4n+1 frames) must be correct to avoid silent shape mismatches.
On an RTX 3060 12 GB, SDXL LoRA training is feasible with optimizations, while Flux training requires quantization. On the same card, a 7B QLoRA fits, while a 13B LoRA does not.
Image LoRA Hardware For SDXL, Flux, Pony, And Illustrious
The base-model family sets the VRAM ceiling before resolution or batch size enter the picture.
- SDXL (Including Juggernaut, Pony, And Illustrious)
- SDXL LoRA training with current Kohya-ss scripts using bf16 mixed precision, xFormers, and fused backward pass can run in 8 GB VRAM (10 GB recommended), with 16 GB comfortable and 24 GB allowing default settings, when memory-saving options such as training U-Net only, gradient checkpointing, –cache_text_encoder_outputs, and 8-bit optimizers or Adafactor are enabled. A 12 GB card finishes SDXL LoRAs reliably but more slowly than a 24 GB-class card.
- Flux.1 Dev And Flux.1 Schnell
- For FLUX.1 Dev and Schnell LoRA training, 24 GB VRAM supports batch size 2 at basic settings, while 16 GB can work with batch size 1 and optimizations such as –blocks_to_swap=8 or Kohya’s fused backward pass; 32 GB is comfortable and 48 GB+ is recommended for high-rank training or large datasets. A 12 GB card cannot train Flux.1 Dev without quantization.
- Flux.2 Dev
- FLUX.2 Dev (32B) LoRA training requires roughly 50–70 GB of VRAM, with ~60 GB as the practical requirement. On an RTX 5090, rank 32 / batch 1 uses ~24 GB and rank 64 / batch 2 uses ~28 GB, leaving little headroom, and full-precision FP16 Flux.2 Dev does not fit on 32 GB at all.
- Pony And Illustrious
- Pony and Illustrious are SDXL-derived ecosystems whose LoRAs often expose SDXL-shaped weights and may load in a generic SDXL loader, but their concepts can remain tied to a specific checkpoint lineage, caption style, or tag vocabulary, so successful loading does not guarantee useful output.
LLM LoRA And QLoRA Hardware Requirements
The weight-memory math sets the floor. A 7B model at FP16 is approximately 14 GB of weights (7B × 2 bytes). At 4-bit NF4, the nominal footprint drops to about 3.5 GB (0.5 bytes per parameter). In practice, quantized files use 4.8–5.5 effective bits per weight because of per-block scaling and mixed precision, so they land around 4.2–4.8 GB. A 70B model at FP16 is 140 GB, dropping to roughly 35 GB at QLoRA for static quantized weights. Dynamic allocations during training push real VRAM needs higher than these file sizes.
QLoRA fine-tuning of a 7B model typically fits in roughly 8–10 GB VRAM, though Qwen’s documentation reports 11.5 GB at sequence lengths of 256–512 for Qwen-7B. A 13B model needs about 16–18 GB, which fits an RTX 3090 or A10G.
The QLoRA software stack centers on PEFT and bitsandbytes. PEFT 0.19.1 requires Python 3.10 or higher, with Python 3.11+ recommended, and bitsandbytes provides QLoRA 4-bit quantization for PyTorch, enabling 4-bit model training with LoRA adapters. Bitsandbytes requires Python 3.10+ and PyTorch 2.4+, and it expects NVIDIA GPUs with compute capability SM60+ (SM75+ recommended) on Linux and Windows x86-64, with SM75+ on aarch64; within these, LLM.int8() needs CC 7.5+, and 8-bit optimizers plus NF4/FP4 quantization need CC 6.0+.
nvidia-smi often reports a low VRAM figure until the first backward pass, because activations and optimizer state can add roughly 1.5–2× the inference footprint and spike several GB mid-step. A short smoke test before a full schedule confirms that the configuration survives the first backward pass.
LoRA Base Model Compatibility Across SDXL, Flux, And SD 1.5
LoRA adapters are architecture-specific: an SD 1.5 LoRA will not work with SDXL, and a FLUX LoRA will not work with SD 1.5 or SDXL, because model dimensions, tensor keys, and conditioning components differ. Architecture sets the hard boundary.
Tensor-key patterns distinguish broad architectures when metadata is missing. Flux LoRAs contain keys with “transformer_blocks,” “double_blocks,” or “single_blocks” (or “single_transformer_blocks”) depending on trainer format, such as AI-Toolkit’s transformer.transformer_blocks.N.* and transformer.single_transformer_blocks.N.*, which normalize to diffusion_model.double_blocks.N.* and diffusion_model.single_blocks.N.*. SDXL LoRAs contain UNet block keys in either “input_blocks” / “output_blocks” / “middle_block” or “down_blocks” / “up_blocks” / “mid_block” spellings. SD 1.5 LoRAs use keys such as lora_unet_down_blocks_X_attentions_Y that map to model.diffusion_model.input_blocks.* and model.diffusion_model.output_blocks.* when converted.
Software Stack Compatibility For CUDA, PyTorch, PEFT, And Bitsandbytes
The version chain matters as much as the hardware, because a single mismatch between Python, PyTorch, PEFT, and bitsandbytes can turn a working run into an OOM or import error. The stack below reflects current production guidance.
- Python
- AI Workflow Lab’s 2026 guide tests a production LoRA/QLoRA stack on Python 3.11+, PyTorch 2.5+, CUDA 12.x, TRL 0.29, and PEFT 0.14+, with examples validated on that combination.
- PEFT
- PEFT 0.19.1, released on April 16, 2026, follows several rapid releases (0.19.0, 0.18.1, 0.18.0), and Transformers v5 is incompatible with PEFT versions below 0.18.0. This cadence increases the risk of subtle version drift.
- Bitsandbytes
- Bitsandbytes requires Python 3.10+ and PyTorch 2.4+, and it expects NVIDIA GPUs with compute capability SM60+ (SM75+ recommended) on Linux and Windows x86-64, with SM75+ on aarch64; LLM.int8() needs CC 7.5+, and 8-bit optimizers plus NF4/FP4 quantization need CC 6.0+.
- TRL
- TRL v1.0 supports both LoRA and QLoRA through PEFT integration, covering SFT, DPO, GRPO, and reward-modeling trainers.
RTX 5090 and other Blackwell cards report CUDA capability sm_120, which standard PyTorch stable wheels (up to sm_90) do not support. Installing a PyTorch build compiled with CUDA 12.8 (cu128), such as nightly or PyTorch 2.7+, resolves this without rebuilding bitsandbytes or xformers.
A clean virtual environment keeps this version chain stable. Rapid PEFT and Transformers releases make mixed-site installs fragile, so isolating each project avoids breakage from global upgrades.
NVIDIA NeMo Customizer GPU Memory Guidelines outline 40–80 GB single and multi-GPU configurations for 7–8B, 13B, and 70B models, which helps plan multi-GPU LoRA or full fine-tunes.
System RAM, Storage, And Supporting Hardware
Once the software stack is stable, the rest of the machine must keep the GPU fed.
For LoRA training, system memory should be at least 2× total GPU VRAM for efficient data staging. A dual RTX PRO 6000 Blackwell system with 192 GB VRAM should have at least 256 GB of system memory. A single 96 GB GPU should pair with 128 GB DDR5 ECC RDIMM at minimum, with 256 GB more comfortable.
NVMe Gen 4 minimum (Gen 5 ideal) with two drives, one for OS/apps and one for datasets/models, is recommended. Stable Diffusion checkpoints range from 2–7 GB each. Flux.1 model files span about 4 GB for heavily quantized GGUF to roughly 24 GB for full FP16, with common FP8 and NF4 versions around 12–17 GB, and larger Flux.2 variants can exceed this. Active ComfyUI setups often accumulate 100–200 GB of models, LoRAs, and ControlNets, so 200 GB is a baseline for multiple base models plus LoRAs and 300 GB+ suits a larger zoo.
A weak CPU can starve the GPU during DataLoader operations, dropping GPU utilization to 10–60% when it should sit above 90%. Monitoring utilization during test runs reveals this bottleneck quickly.
The RTX 5090 has a 575 W TGP with transient spikes up to 901 W for under 1 ms, and NVIDIA’s required system power is 1000 W. Builders often choose a 1200 W PSU for headroom.
Local LoRA Training Costs Compared To Cloud GPUs
Cost decisions hinge on hourly cloud rates, run length, and how often you train.
On-demand cloud GPU rental for A100 and H100 on RunPod and Lambda Labs generally ranges from about $1.19/hr up to roughly $4.29/hr. At $1–$3 per hour, a typical SDXL LoRA training run takes 1–2 hours and costs $5–$10 per LoRA, while training on cheaper consumer GPUs like an RTX 4090 can cost well under $1. For a 100-run QLoRA project on a used RTX 4090 versus RunPod Community Cloud, the break-even lands around 4,789 hours of training, or about 26 hours per week over three years.
A Flux.2 LoRA run costs roughly $1–$3 on a rented RTX 4090 and finishes in 2–4 hours.
LoRA training remains heavily NVIDIA-centric because CUDA, bitsandbytes, and Flash Attention are tuned for NVIDIA GPUs and have less mature AMD ROCm or Apple Silicon support, even though ROCm and MLX/MPS alternatives are functional. For LoRA fine-tuning, NVIDIA hardware trains roughly 2–4× faster than Apple Silicon when the model fits in VRAM.
For commercial pipelines that handle confidential client data, cloud training often fails compliance requirements because assets cannot leave the premises. In those cases, a local workstation becomes the only viable path.
Creators focused on finished content rather than model ownership can also skip hardware entirely by using a no-training platform that locks a likeness from three photos and returns consistent output.
Will My Current Machine Train A Custom LoRA? A Compatibility Checklist
- Confirm your GPU’s VRAM tier against the workload table. A 12 GB card covers QLoRA training of a 7B model and SDXL LoRA training at 768 px with gradient checkpointing. A 24 GB card comfortably covers 13B QLoRA fine-tuning and can run Flux.1 at FP16 for inference using roughly 18–20 GB, though that remains tight. A 32 GB GPU such as the RTX 5090 can handle QLoRA (4-bit NF4, r=64) fine-tuning of a 32B model (~28 GB) and a MoE 30B A3B model (~21 GB), while standard LoRA for these models needs 76 GB and 69 GB respectively.
- Confirm your base model family matches the LoRA you intend to train, such as SDXL, Flux, Pony, Illustrious, or a specific LLM architecture. Architecture is the hard boundary, so an SDXL LoRA will not load on Flux and a Flux LoRA will not load on SDXL.
- Confirm your software stack. Use Python 3.10+, PyTorch 2.4+, PEFT 0.18.0+, and bitsandbytes with GPU support, inside a clean virtual environment without leftover packages from prior installs.
- Confirm your system RAM is at least 2× your VRAM and that your dataset and checkpoints live on NVMe storage.
- Run a short smoke test before a full schedule to confirm the model loads, captions resolve, cache creation completes, samples generate, and checkpoints open in the inference UI.
Skip The Hardware Question Entirely With Sozee
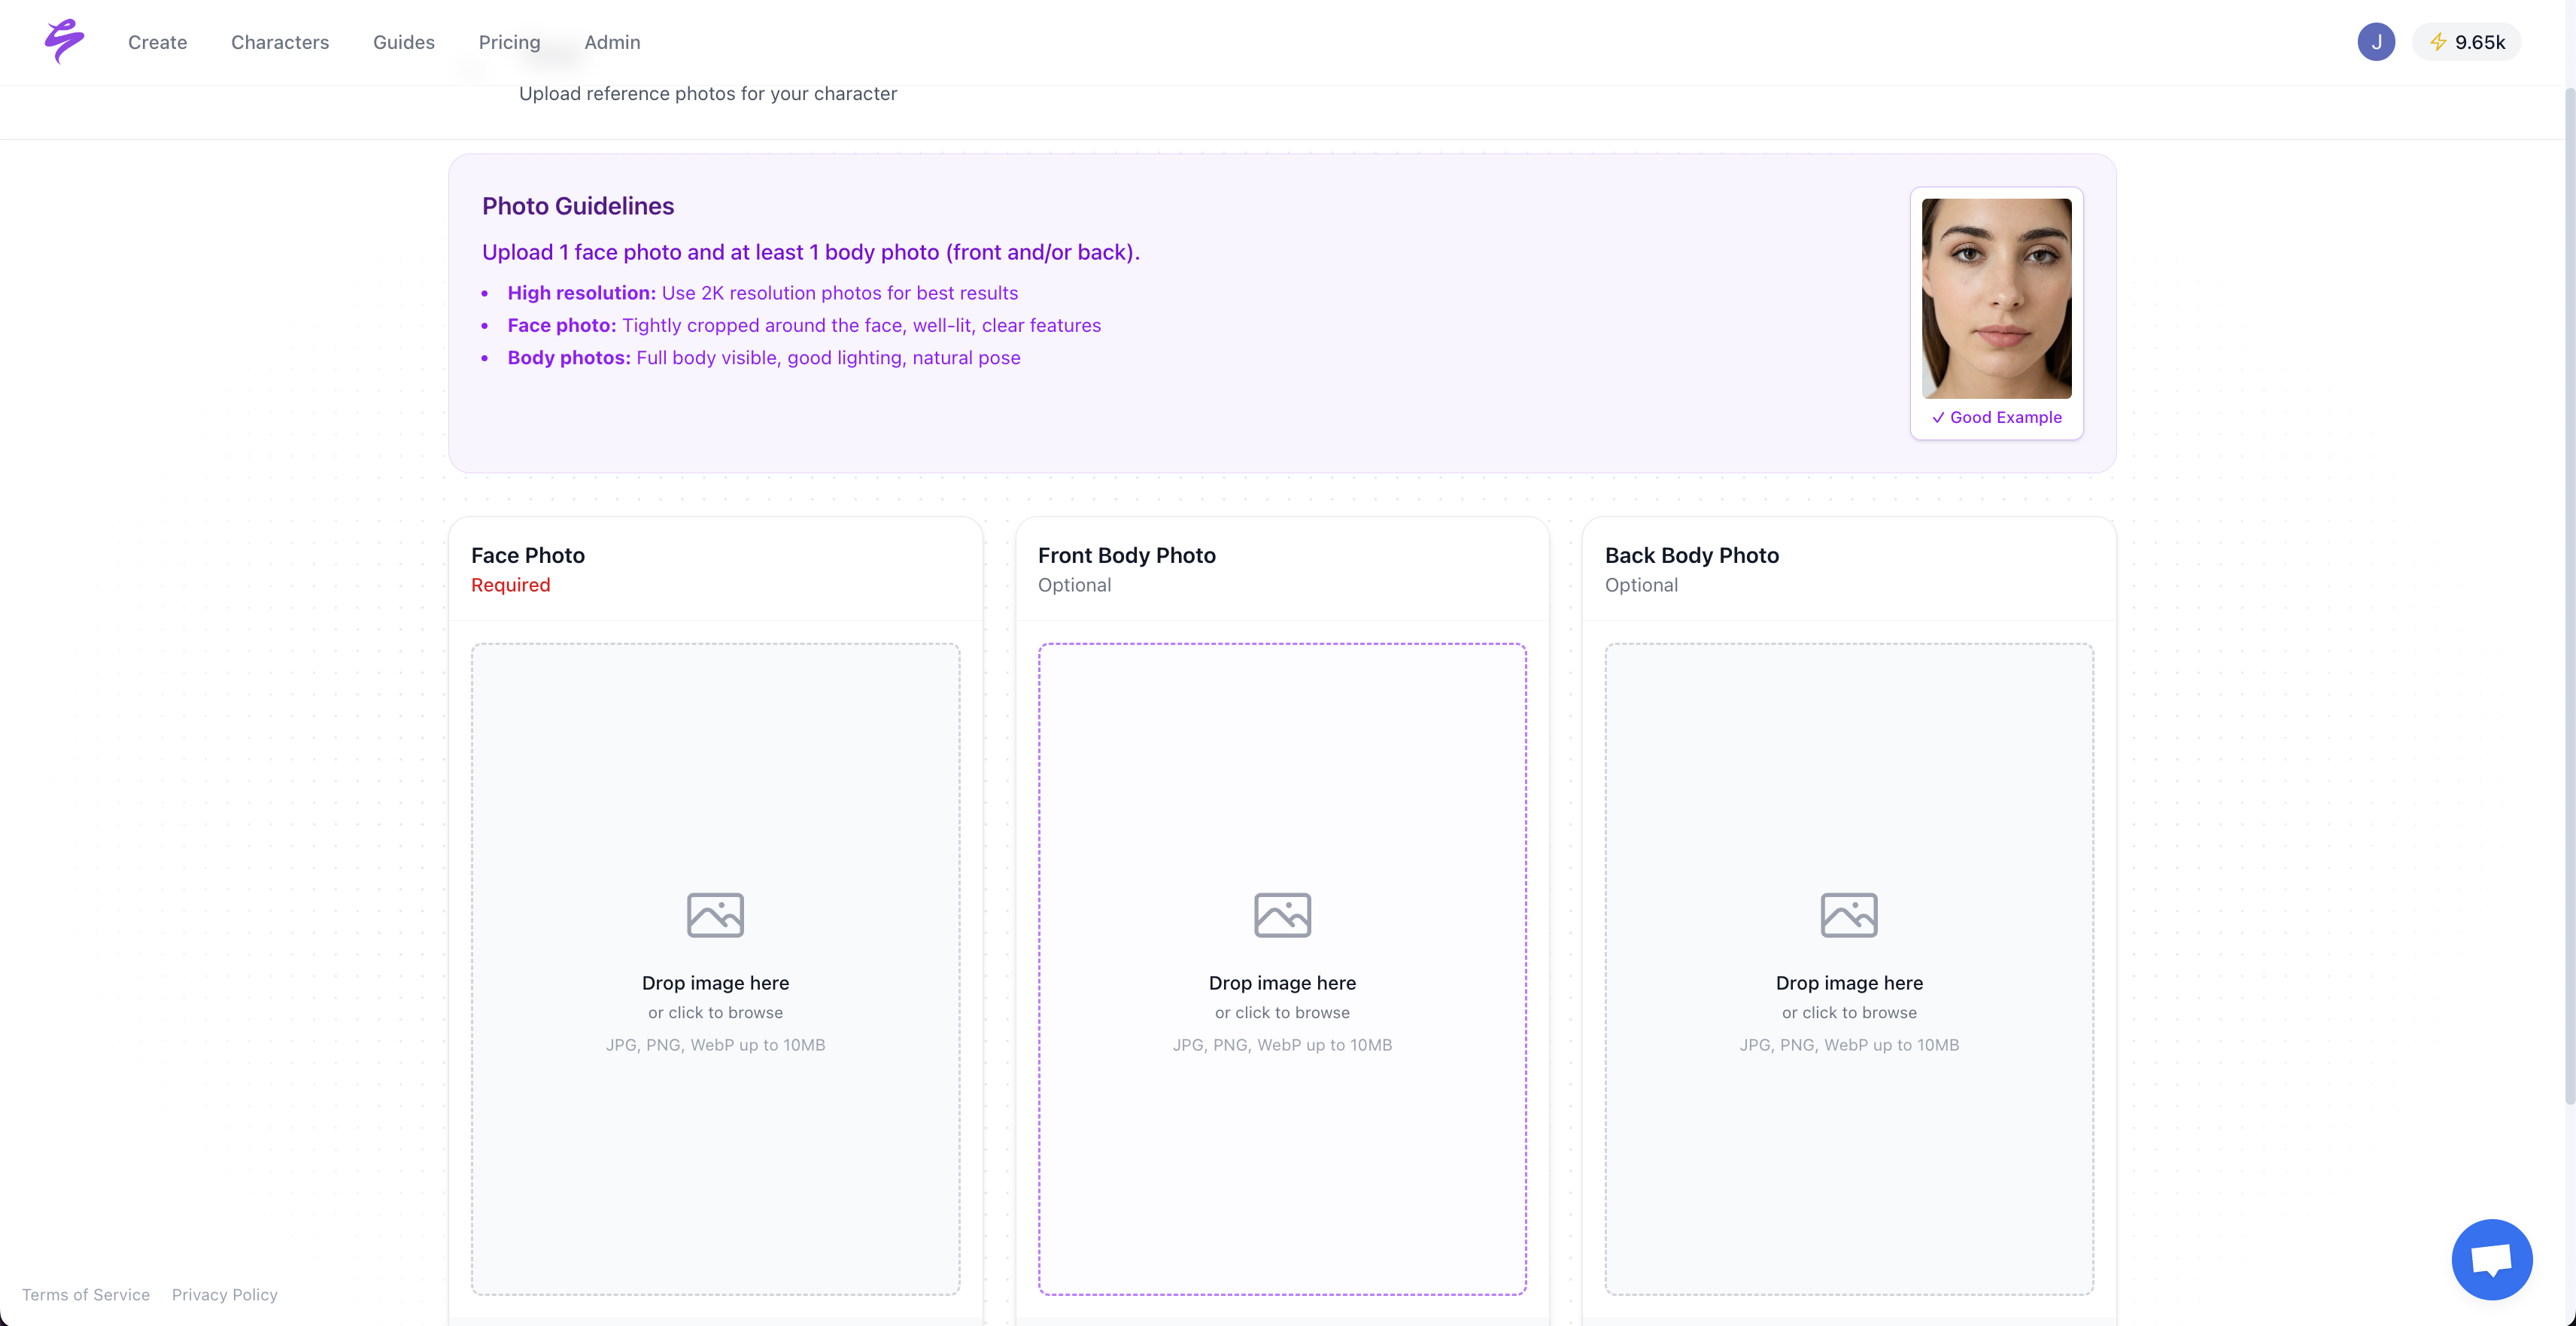
Some readers will decide their hardware will not clear the bar or that they prefer directing content over managing training rigs. Sozee serves that group by removing training from the workflow. You upload photos and get a locked character without running a training job.
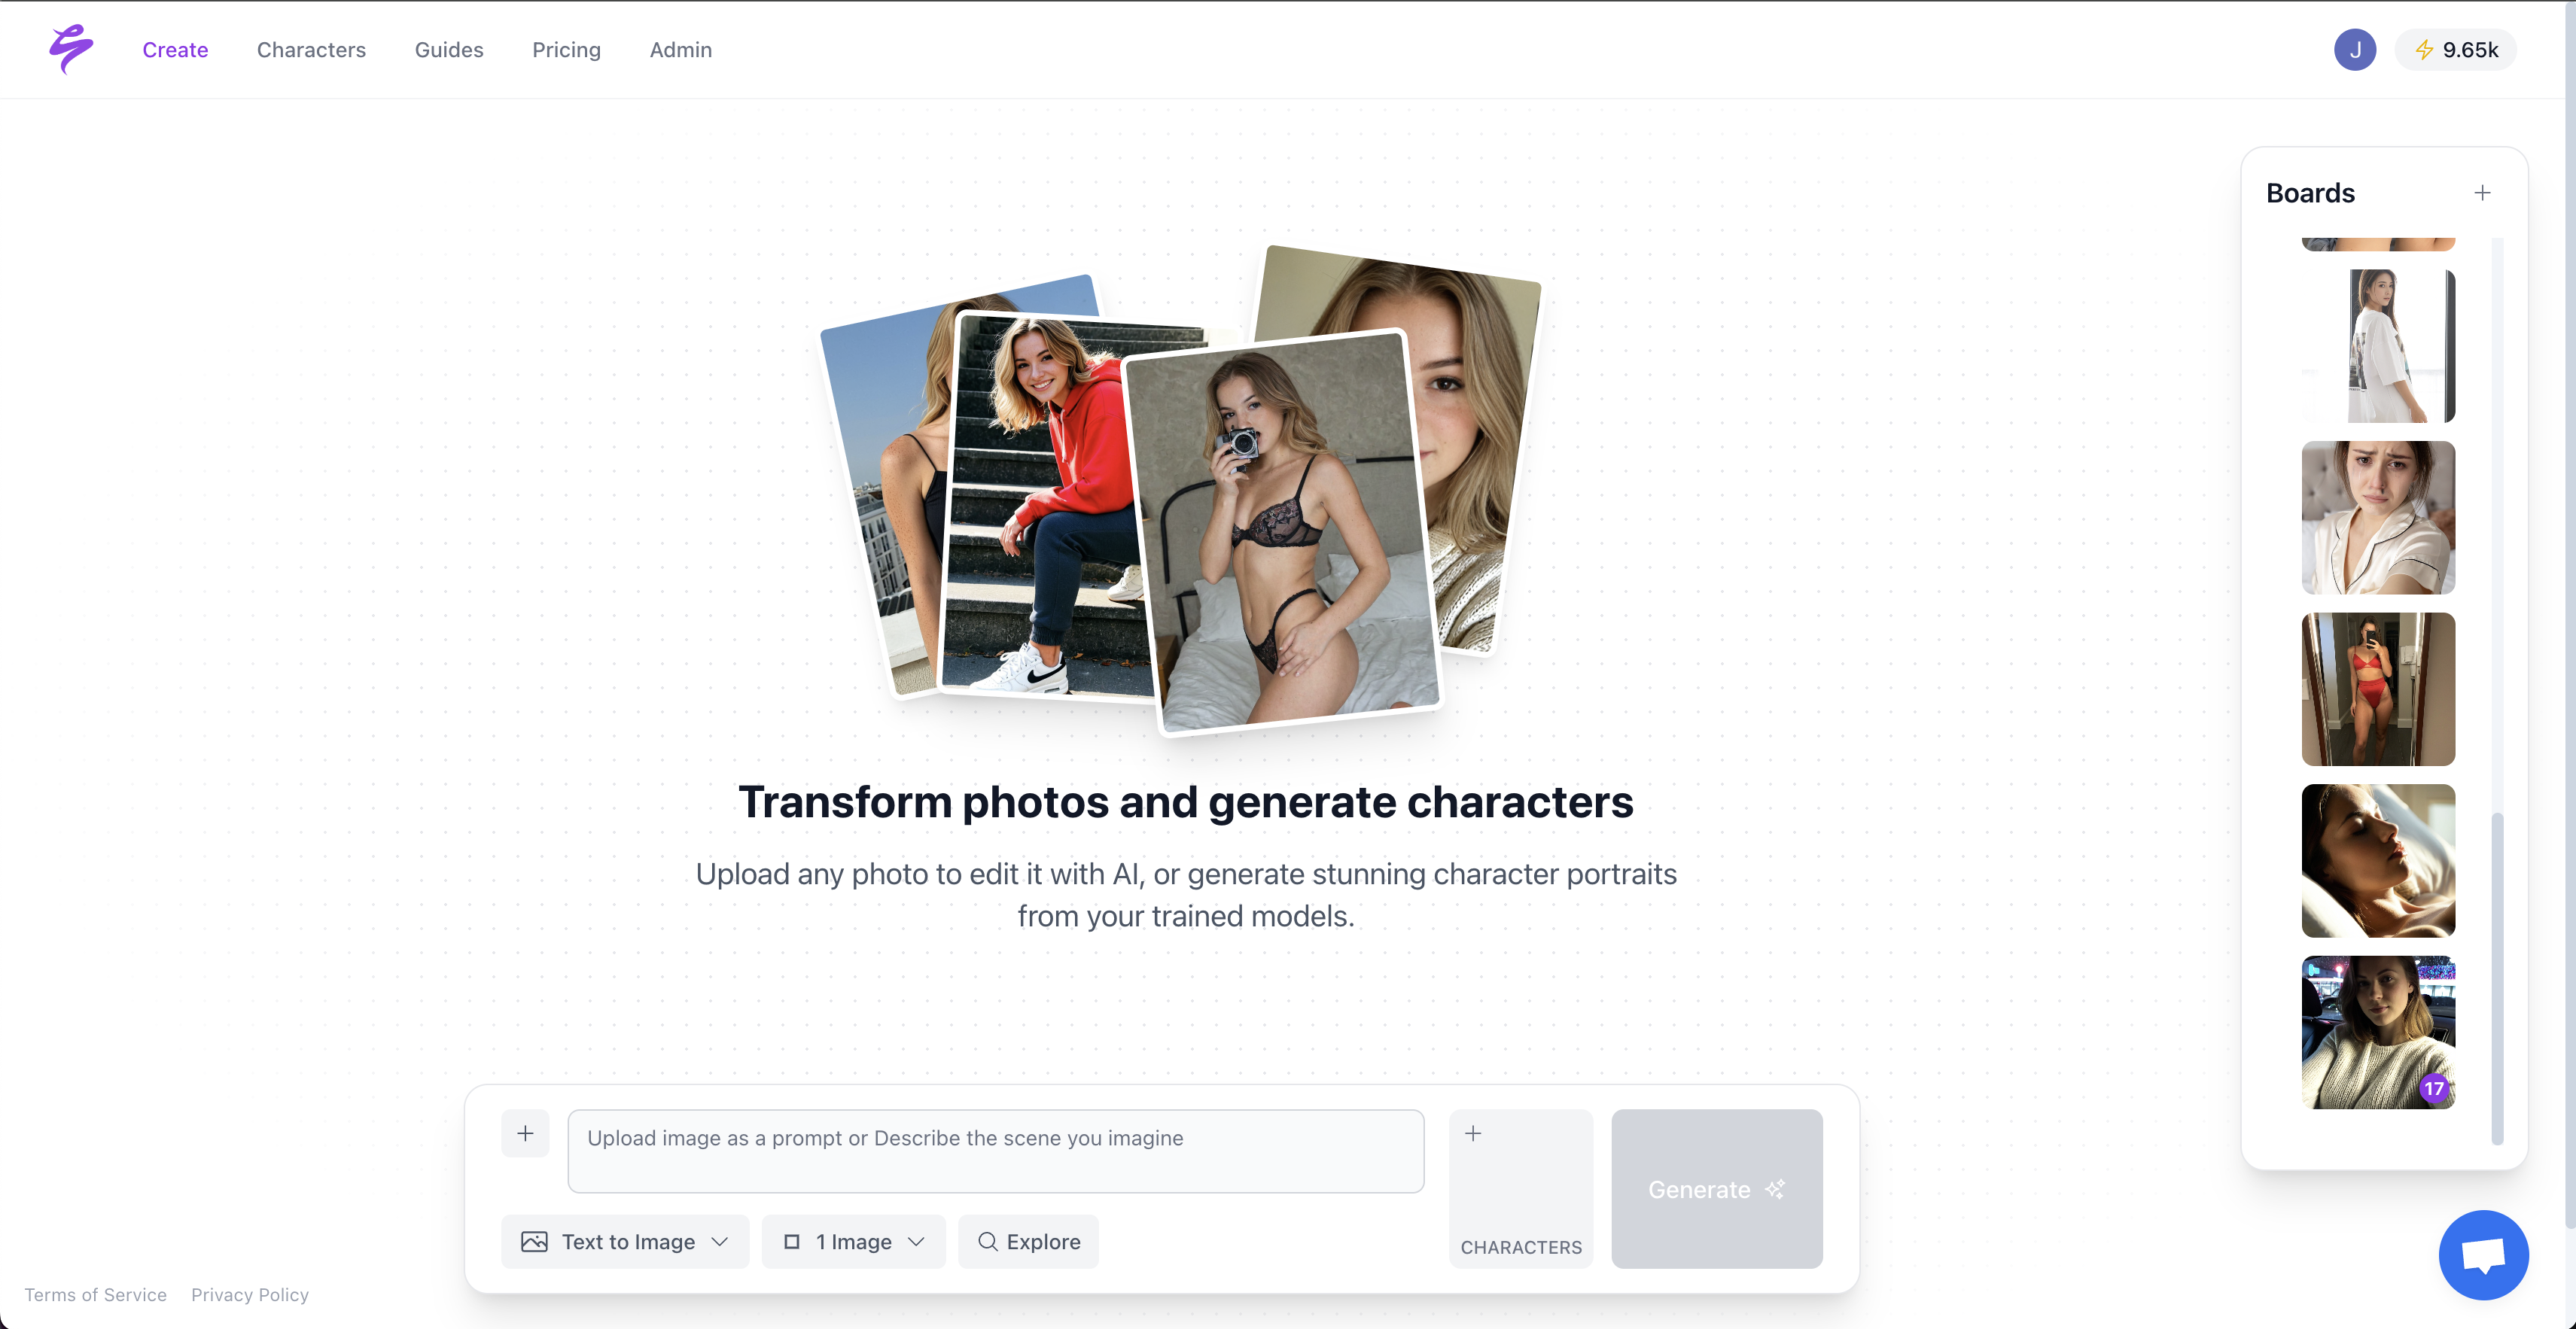
Upload as few as three photos and Sozee reconstructs likeness with hyper-realistic accuracy, or you can generate an entirely original character from scratch.
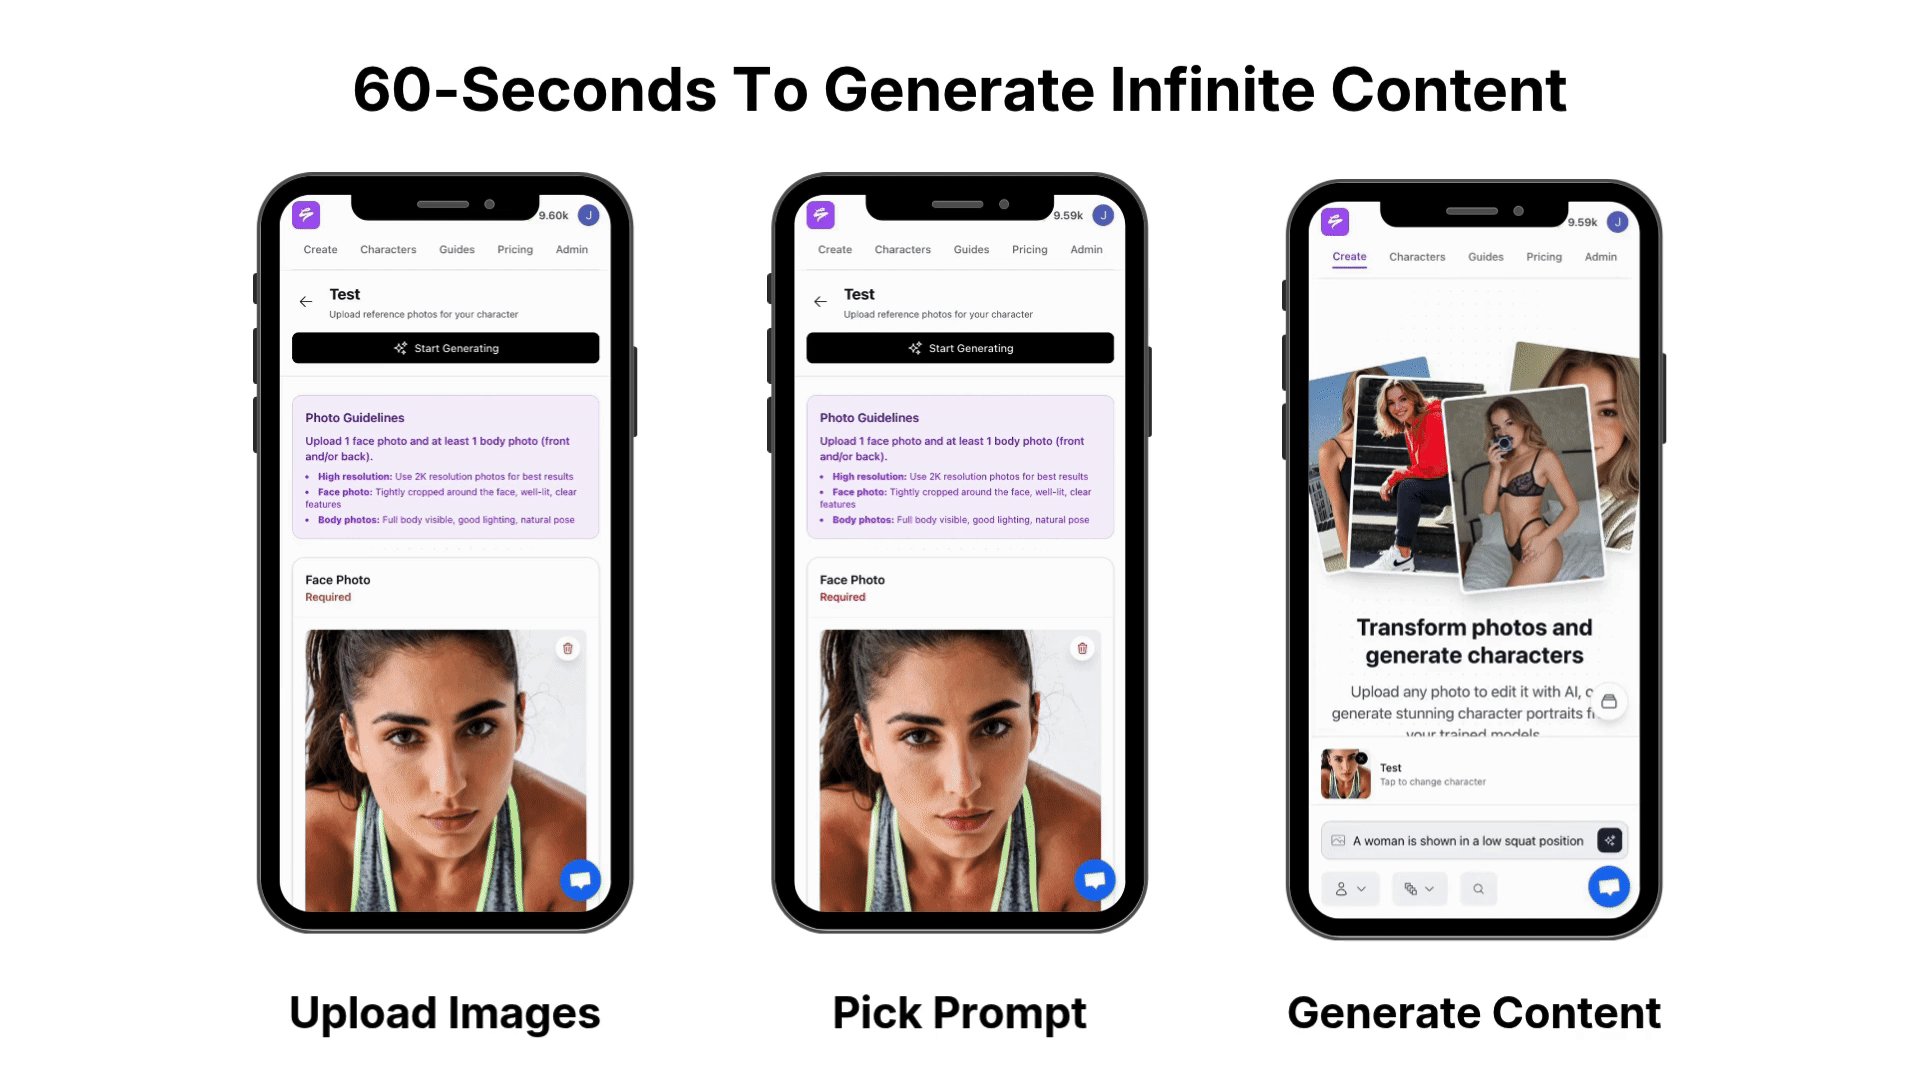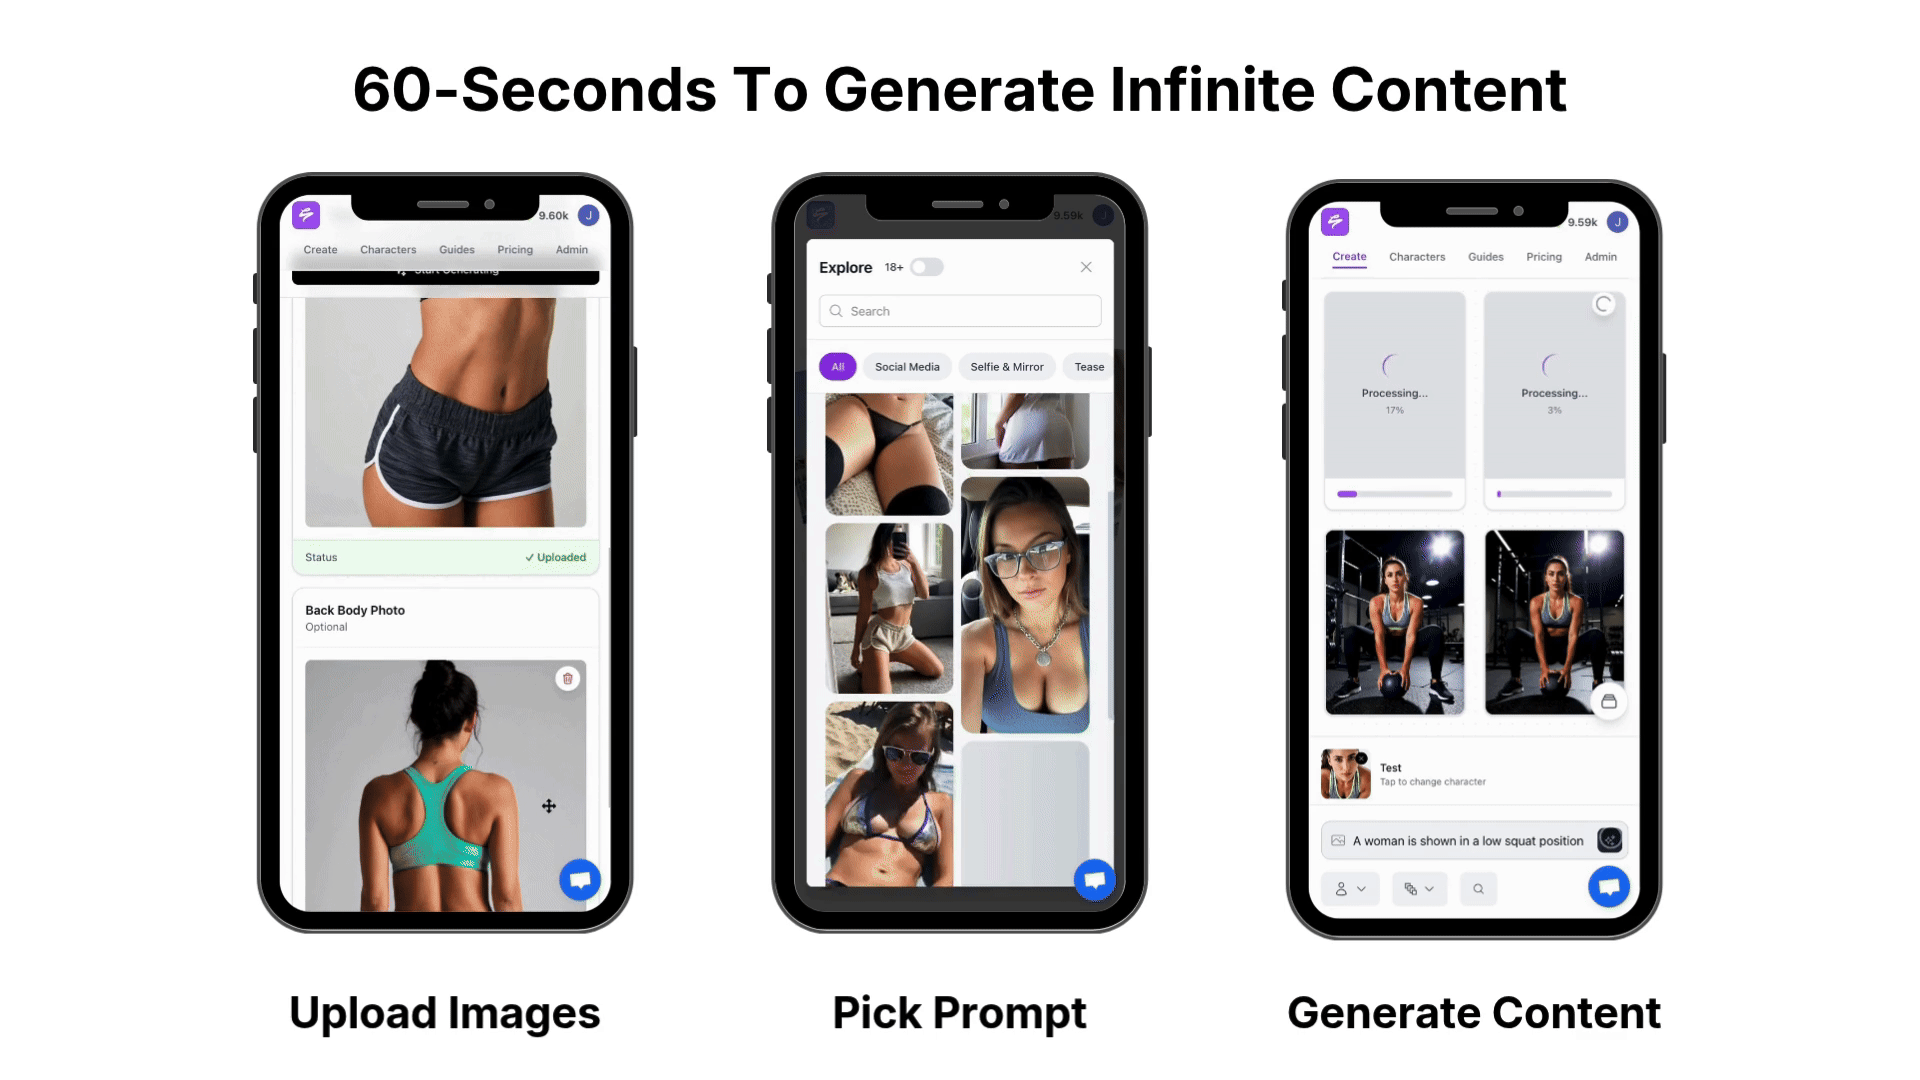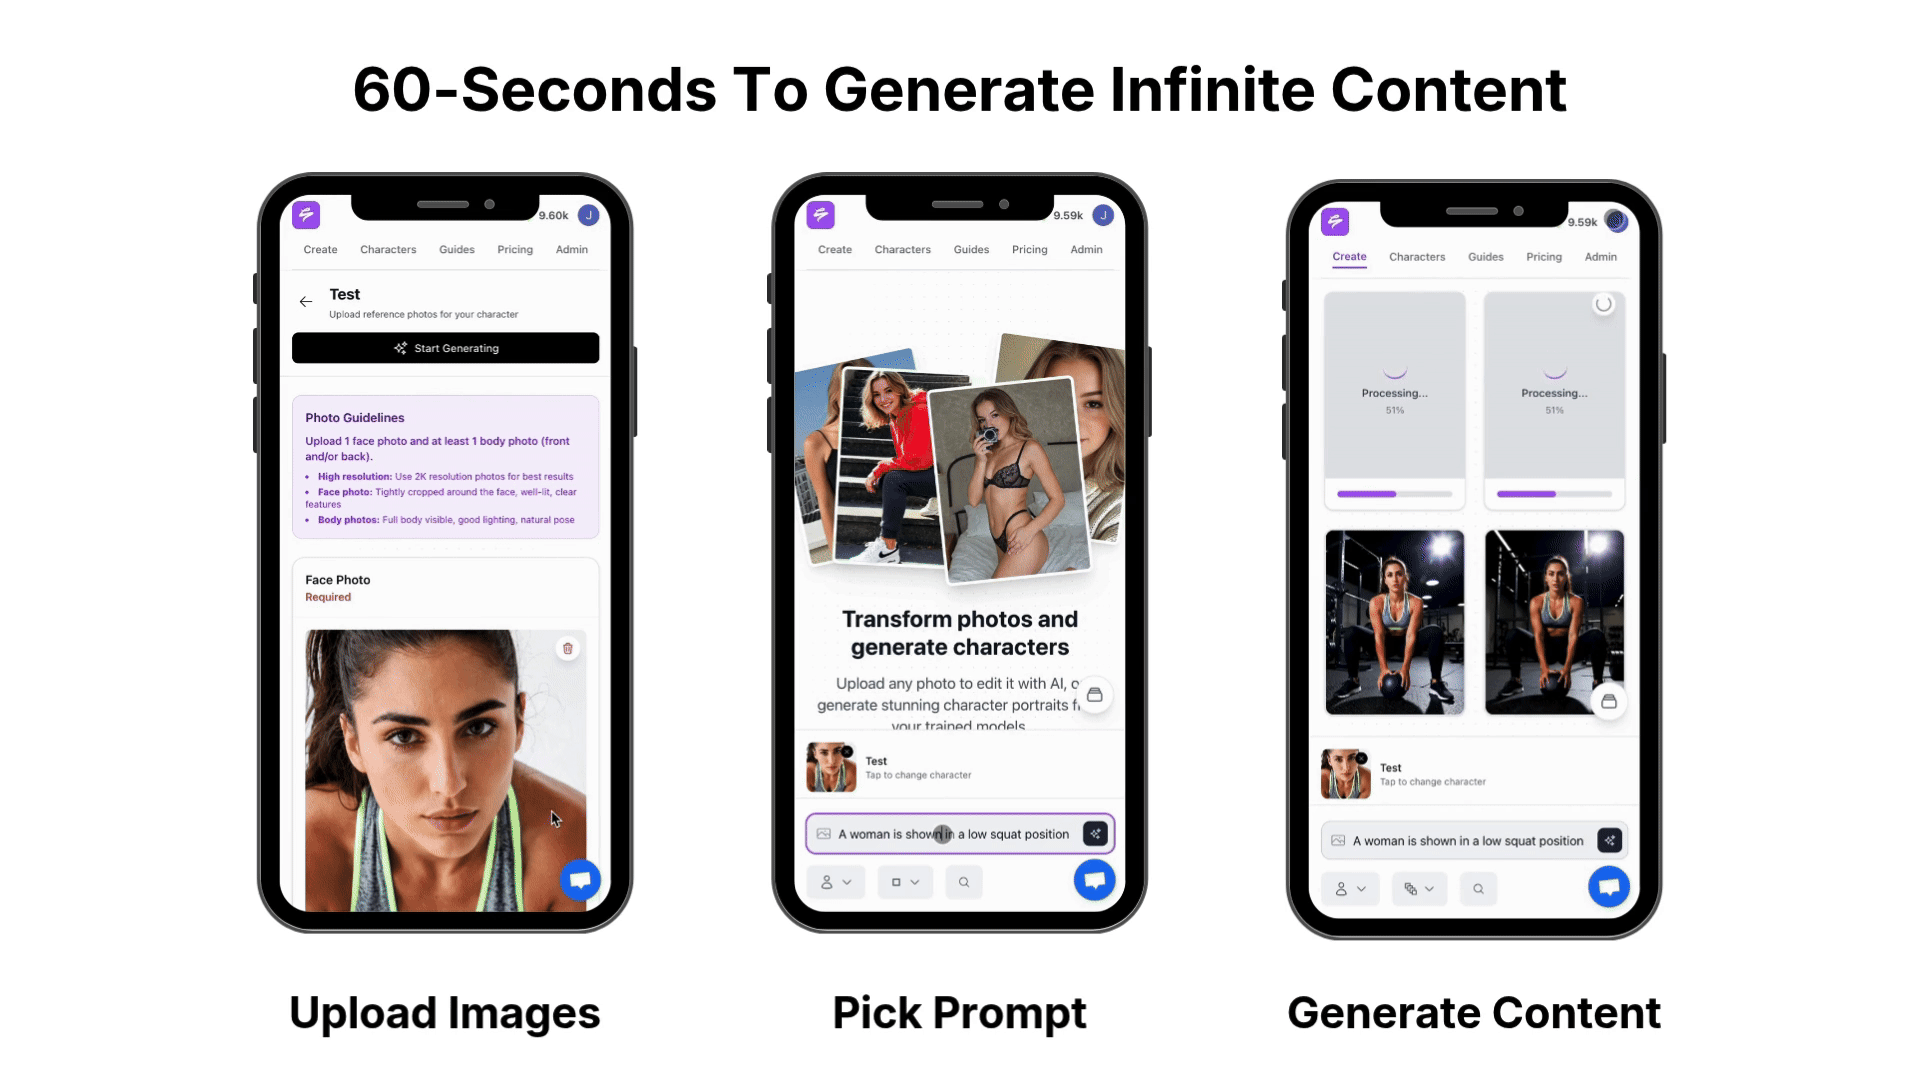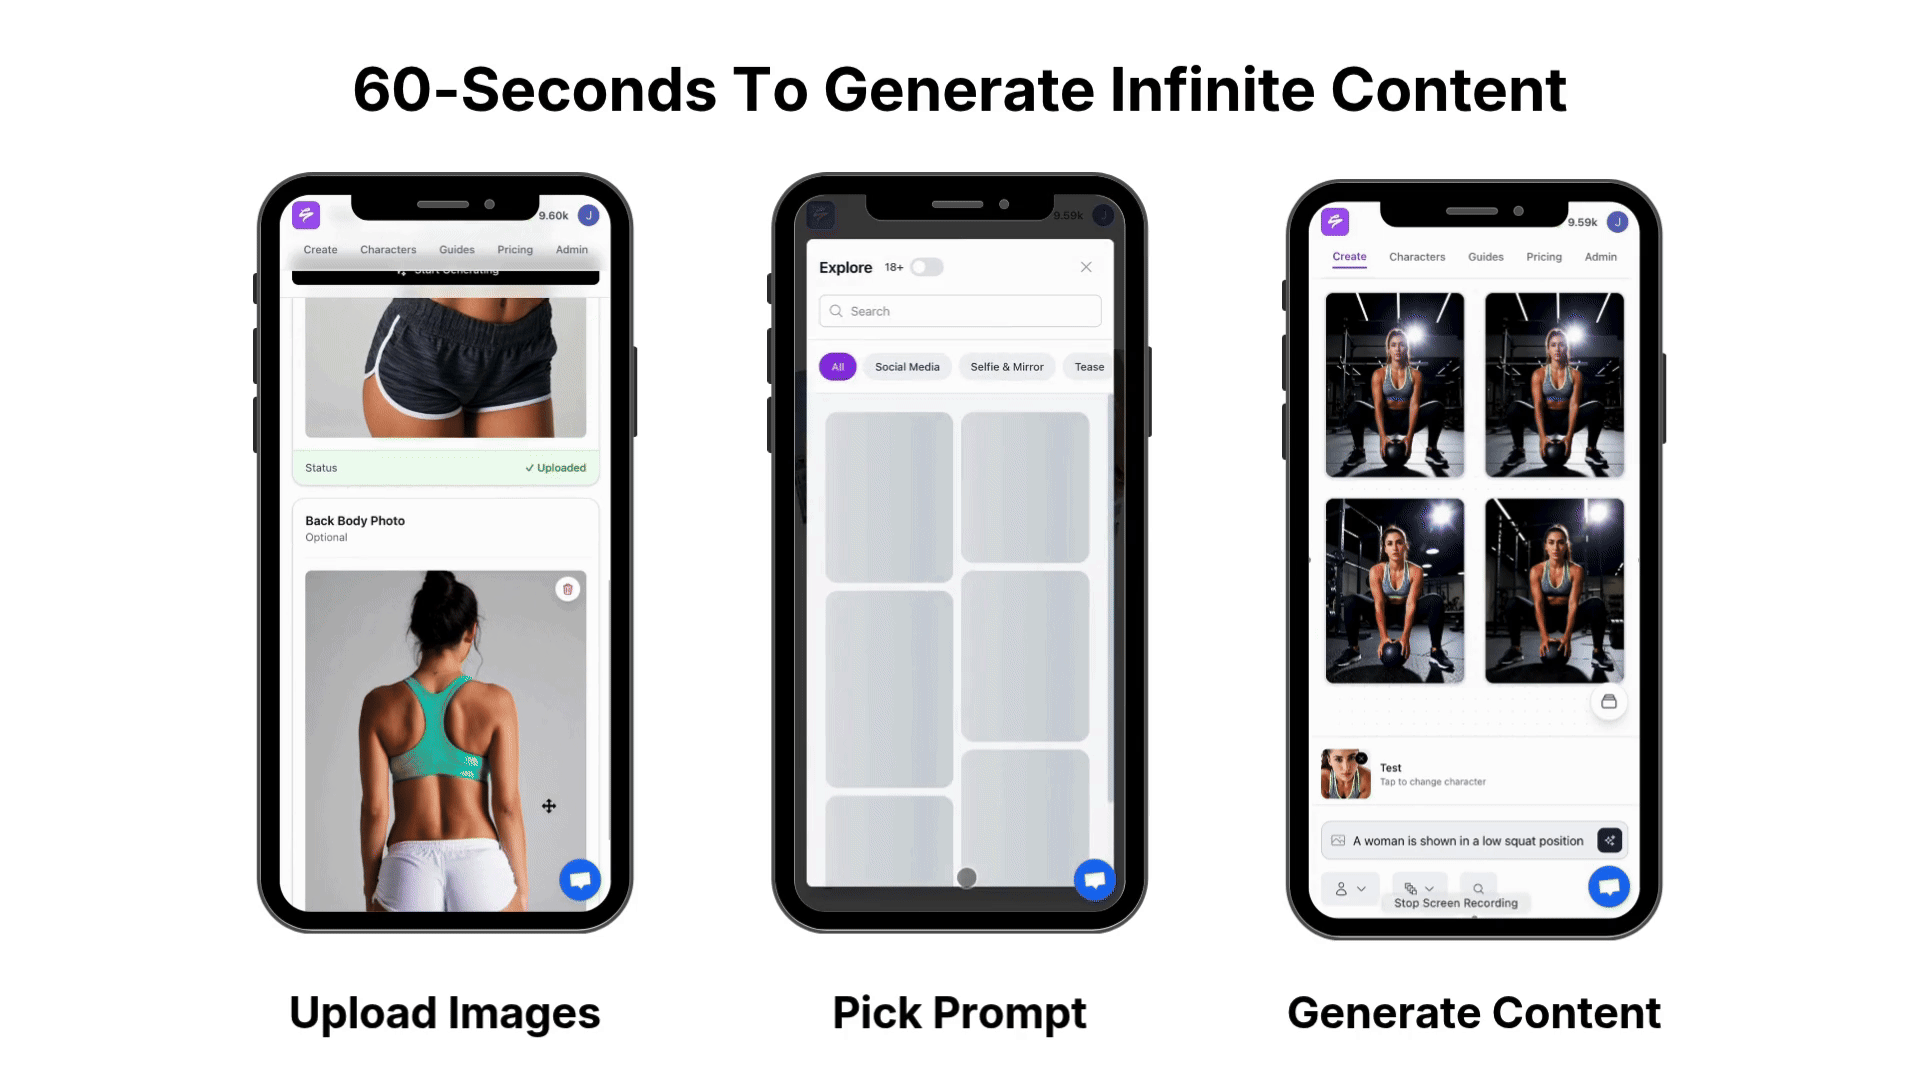
- Locked likeness across every frame, every set, and every week, so the same face and body appear without re-rolling prompts.
- Photo Control with five directable dimensions: Setting, Outfit, Shot Style, Expression, and Object.
- Photo Shoot mode where one image becomes a coherent locked set of up to ten, including a full SFW-to-NSFW arc with pacing and ceiling under your control.
- Reusable environments built from up to four reference shots, outfits assembled from one piece per category, and an object library of up to four props per set.
- Live Mode for real-time character transformation on your webcam or phone, so you act and your character performs.
- The Agent, a conversational layer that interviews you into a finished shoot setup and writes directly into the prompt bar and Photo Control panel.
- Native scheduling across Instagram, TikTok, X, Facebook, Reddit, and Fanvue, plus analytics that separate Sozee posts from your own uploads.
Every setting, outfit, and object you build is saved and reusable, so each shoot makes the next one faster. This approach offers a practical alternative to custom LoRA hardware for creators who monetize content. Go viral today and get started with Sozee.
Frequently Asked Questions
How Many Images Do You Need To Train A LoRA?
There is no reliable universal image count. Common starting dataset sizes are roughly 15–30 images for a character LoRA, 30–100 images for a style LoRA, and 10–25 images for a concept LoRA, but quality matters more than quantity. Character LoRAs can be trained on as few as 10 images, though 15–30 images is the recommended range for good coverage. Coverage, consistency, caption quality, subject complexity, and desired flexibility matter more than hitting a specific number. A smaller, varied, high-quality dataset usually beats a larger set filled with duplicates or poor images. For creators who want consistent character output without building a dataset, Sozee only needs three photos to lock a likeness.
How Long Does It Take To Train A LoRA?
As noted earlier, a 30-image SDXL LoRA runs in roughly 30–60 minutes on an RTX 4090, and Flux LoRAs take about twice as long on the same card. Most LoRA training runs take roughly 1–6 GPU hours, with typical runs on 7B–13B models completing in about 1–3 hours, while larger projects can stretch into days. Training a Wan 2.2 video LoRA (I2V) on an NVIDIA A6000 with 96 GB VRAM takes almost 24 hours, and video LoRA training on Wan 2.2 can take 2–3 days (48–72 hours) on a lower-VRAM consumer card such as an RTX 4090 using block-swap and FP8. These figures assume a well-configured environment; version mismatches or CPU bottlenecks can extend training times significantly.
Which LoRA Trainer Works Best For Different Use Cases?
Kohya_ss is an open-source Gradio-based GUI and CLI for Kohya’s Stable Diffusion training scripts that supports LoRA training for Stable Diffusion 1.5/2.x, SDXL, SD3, and Flux.1 base models, as well as Lumina Image 2.0, Anima, and HunyuanImage-2.1, under the Apache 2.0 license. FluxGym focuses on Flux-specific training as a web UI for FLUX.1 LoRA runs, supports low-VRAM configurations (12 GB, 16 GB, 20 GB), and wraps Kohya sd-scripts. Anima-Standalone-Trainer is a dedicated GUI for Anima LoRA training, built on kohya-ss/sd-scripts with Windows and Linux support.
For LLMs, Unsloth currently leads on speed. Hugging Face benchmarks (Transformers 4.36, QLoRA rank 16, gradient checkpointing on, across 59 runs on Tesla T4 and A100 Colab instances) show Unsloth using optimized Triton kernels to train up to 2.7× faster and use up to 74% less memory than standard Hugging Face PEFT, which suits single-GPU consumer workflows. Axolotl suits advanced users who need configuration flexibility, including per-module LoRA rank and alpha overrides via lora_rank_pattern and lora_alpha_pattern in YAML. Hugging Face TRL with PEFT remains the most widely used general-purpose stack.
How Much Does It Cost To Train A LoRA?
Renting an A100 or H100 on RunPod or Lambda Labs at $1–$3 per hour typically yields SDXL LoRA runs that take 1–2 hours and cost $5–$10 per LoRA, while training on cheaper consumer GPUs like an RTX 4090 can cost well under $1. A Flux.2 LoRA run costs roughly $1–$3 on a rented RTX 4090 and finishes in 2–4 hours. A Wan 2.2 video LoRA on an H100 or A100 80 GB costs roughly $25–$50 for a single well-tuned LoRA, driven mainly by wall-clock hours. Local training is nearly free in incremental electricity cost if you already own a capable GPU, though power draw under sustained load can add up over long runs. Measured power draw on an RTX 5090 gives a realistic baseline for estimating that cost.
Can You Train A LoRA Without A High-End GPU?
Yes, within clear limits. A 12 GB card can train an SDXL LoRA with modern memory optimizations such as fused backward pass, bf16 mixed precision, and gradient checkpointing, although training times will be longer than on a 24 GB-class card. QLoRA fine-tuning of a 7B LLM fits in 8–10 GB VRAM, which makes it accessible on an RTX 3060 12 GB or RTX 4070 12 GB. Below 12 GB, you are restricted to models smaller than 7B or to extremely slow runs with heavy gradient accumulation, and Flux.1 Dev training remains impractical without quantization. For creators focused on content output, Sozee removes hardware from the equation entirely and works without a GPU at any tier.
Start creating now with Sozee, no local hardware required.
Conclusion: Choosing Between Upgrading, Renting, Or Skipping Hardware
The decision framework follows directly from the workload analysis in this guide. Choose local hardware if you train more than 40 runs per month or your data cannot leave the premises, such as confidential client assets, unreleased products, and talent likenesses. Choose cloud GPU rental if you train 1–10 LoRAs per month, your GPU has less than 12 GB VRAM, or you need a 48 GB+ card for a one-off Flux.2 or 70B LLM run. Choose a no-training platform like Sozee if your goal is content output rather than model ownership, and you prefer to avoid hardware decisions entirely.
The core message of this guide is that workload defines hardware needs. Match the workload first, then the machine. A reader who starts with the VRAM tier table and works outward to base-model compatibility, software stack, and system RAM will avoid many of the most common and expensive mistakes in custom LoRA training.
For creators who reach the end of this checklist and decide the hardware bar is too high, or who simply want to direct content instead of building a training rig, Sozee offers a practical alternative. Upload three photos, lock your likeness, and produce a month of content in an afternoon without touching CUDA or PyTorch. Get started today and grow your audience without new hardware.