
Last updated: September 14, 2026
Key Takeaways
- Off-the-shelf AI keeps fixed costs low and variable costs high. Custom AI flips that tradeoff, and the math changes by tier: prompting or RAG, fine-tuning, or training from scratch.
- The three custom tiers have different economics. Prompting and RAG add almost no fixed cost. Fine-tuning typically runs $10K–$80K total. Training from scratch starts around $500K–$2M+ in compute alone.
- Most teams miss 30–50% of the real custom AI bill because they ignore lifecycle costs like data prep, ML salaries, maintenance, and compliance.
- Custom AI only makes financial sense at very high, predictable volumes, such as 100M+ tokens per month for fine-tuning or 1–10M queries per day for training from scratch, paired with narrow repetitive tasks and proprietary data.
- Creators and agencies can skip the entire build-vs-buy ladder by using Sozee for locked, consistent character output without custom AI development or ML hiring.
Off-The-Shelf Pricing Structures Explained
Off-the-shelf AI pricing falls into four dominant structures, and each one scales differently as usage grows.
Seat-Based Pricing charges a fixed amount per user regardless of actual consumption. Enterprise seat-based AI SaaS as of September 2026 includes GitHub Copilot Business at $19/user/month, Microsoft 365 Copilot at $30/user/month, and Cursor Enterprise at $40/user/month. The risk appears when adoption stays low. A team that provisions 400 seats at $30/user/month but sees only 80 active weekly users pays an effective $150/month per active user.
Consumption And Token-Based Pricing meters raw usage. As of June 2026, AI API pricing ranges from $0.01 to $30 per million input tokens and $0.02 to $180 per million output tokens depending on the model. Output tokens cost two to eight times more than input tokens, so output volume usually drives the API bill.
On-Demand Vs. Provisioned Inference is the key architectural split. Azure OpenAI offers Standard pay-as-you-go billed per token and Provisioned Throughput Units (PTUs), which reserve model processing capacity and charge an hourly rate whether or not the capacity is used. Provisioned cloud throughput typically runs $3,000–$25,000+/month for reserved allocations, while pay-as-you-go carries no upfront commitment.
Credit-Based And Hybrid Models bundle a usage allowance into a subscription with overage billed per unit. Credit-based and hybrid models fit AI products well because they turn variable, hard-to-predict costs into something customers can plan around.
Common headline ranges such as off-the-shelf SaaS tools at $50–$500+ per seat per month and custom builds from about $15,000–$150,000 for scoped or fractional work to $50,000–$200,000+ via traditional agencies work as order-of-magnitude inputs. The real driver is how your usage grows against the vendor’s pricing axis.
The Real Cost Categories Beyond Sticker Price
Those sticker prices only tell part of the story. Published AI development cost breakdowns typically understate total investment by 30% to 50% because they omit hidden lifecycle costs that appear only after launch. The full cost stack for a custom build includes:
- Data Preparation And Labeling. Data preparation often consumes 30–40% of a custom AI project’s budget, far above the 5% many teams initially assume. Organizations relying on legacy systems or unstructured data should expect to add approximately $30,000–$100,000+ in data engineering costs.
- ML Engineering And Data-Scientist Time. US AI/ML engineer salaries in 2026 range from $134,000 to $193,250, with the true all-in annual cost of a single mid-level US AI engineer reaching $180,000–$250,000. A three-person in-house AI team costs $310,000–$700,000 annually before any code is written.
- Hosting And Inference. Custom LLM (fine-tuned) builds carry $2,000–$15,000 monthly inference and ops costs; custom LLMs trained from scratch run $10,000–$100,000+ monthly.
- Ongoing Maintenance And Retraining. Budget 15%–25% of initial AI development cost annually for model maintenance and retraining, with retraining cycles typically costing $2,000–$15,000 per quarter.
- Security And Compliance. Compliance and security requirements for healthcare, finance, and government projects add $50,000–$300,000+ to Year 1 custom AI costs. Retrofitting compliance costs two to three times more than building it in from the start.
- Time-To-Market. Using pre-trained models via API reduces initial cost by 60%–80% and cuts time to market from months to weeks compared with custom builds.
The Break-Even Framework: Custom AI Vs Off-The-Shelf Cost
The break-even calculation compares total fixed cost against the variable cost savings per unit of usage. The formula is straightforward. Divide total fixed cost by per-unit savings. Total fixed cost includes training, engineering, and infrastructure setup. Per-unit savings equals API cost minus self-hosted cost per token or query. The result is the volume at which custom pays for itself.
That number only matters when four conditions align at the same time: high predictable volume, a narrow repetitive task, a proprietary data advantage, and a hard latency or privacy requirement. Remove any one of these and the math usually favors staying on the API. The table below compares the three build tiers across the dimensions that drive that decision.
| Dimension | Off-The-Shelf API | Fine-Tuned Model | Train From Scratch |
|---|---|---|---|
| Fixed Cost | Near Zero | $10K–$80K realistic total (people, data, iterations) | $500K–$2M+ compute alone for a 7B model |
| Variable Cost | $0.01–$30/M input tokens depending on model | Served inference at 1.5x base model rate on most proprietary providers | Near zero per token once deployed, dominated by infrastructure |
| Skills Required | Developer, API key | ML engineer, labeled dataset of 500–10,000 examples | Dedicated ML research team, GPU cluster, 6–18 months minimum |
| Time-To-Market | Days to weeks | Several weeks to several months | Several months to over a year |
| Typical Break-Even Volume | Cheaper below roughly 10M tokens/day | Compelling above roughly 100M tokens/month for narrow tasks | Viable only around 1–10M queries/day |
At What Point Do AI Subscriptions Become More Expensive Than Running Your Own?
API billing works best up to roughly 30 million tokens per day; beyond that threshold, rate limits and unpredictable monthly bills drive teams toward provisioned or self-hosted options. Below roughly 10 million tokens per day, managed APIs are usually cheaper than any self-hosted configuration. Running local only makes financial sense when GPU utilization is high enough to amortize the fixed serving floor, and that floor includes hardware plus a $1,500–$2,500/month operations cost that exists at any volume.
What Is The Break-Even Point For Custom AI?
A commonly cited break-even model is: break-even volume (tokens per month) = (hourly price of the machine × 730) ÷ (price per token you would otherwise pay). Custom infrastructure typically only becomes viable at very high query volumes such as 1–10 million queries per day, a scale very few products reach in their first two years. For fine-tuning specifically, the break-even calculation should model total first-year investment versus total first-year API spend at projected volume, and fine-tuning becomes compelling only when monthly token consumption exceeds 100M tokens and at least 70% of that volume falls into a clearly defined, repetitive task category.
How Expensive Is It To Create An AI Model?
The tiers below are ordered by magnitude, from near-zero setup to frontier-scale training, so you can place your project on the ladder before running the break-even math.
- Prompting And RAG Setup: A few tens to hundreds of euros per month, with days to weeks to implement.
- Fine-Tuning Compute (Raw): $50–$500 for a 7B model and $500–$5,000 for a 13B–70B model.
- Fine-Tuning Total Project Cost (Realistic): see the $10K–$80K range in the comparison table above, which includes people, data, iterations, and evaluation over several months.
- Data Preparation And Labeling: Often 30–40% of total project budget and $30,000–$100,000+ for organizations with legacy or unstructured data.
- ML Engineering Team (Annual): the $310K–$700K three-person team cost noted above.
- Training A Small Specialized Model From Scratch (1B–7B Parameters): $50,000–$500,000 in compute over days to weeks.
- Training A Mid-Scale Model (13B–30B Parameters): $5M–$25M in infrastructure.
- Training A Frontier Model (Tens Of Billions Of Parameters): GPT-4 cost over $100M and Gemini Ultra approximately $200M.
- Ongoing Maintenance And Retraining (Annual): Typically 15%–25% of initial build cost per year.
- Compliance And Security (Regulated Sectors): $50,000–$300,000+ in Year 1.
When Custom Is The Wrong Call
Custom AI fails most predictably under five conditions:
- Underestimated Maintenance. AI tools lose accuracy every few months without proper maintenance and retraining. Most models need retraining every 3–6 months at $5,000–$50,000 per cycle.
- Data That Is Not Actually Proprietary Or Sufficient. The number one reason custom model projects fail is data quality and volume problems such as too little data, noisy data, or inconsistent labels.
- Low Or Unpredictable Volume. Frontier API access has no upfront cost, minimal setup, and excellent performance, and the math only changes as usage scales into millions of tokens per month.
- Lack Of In-House ML Talent. Between 70% and 85% of enterprise AI projects fail to reach production, most commonly because the surrounding infrastructure, ownership, and integration work was never scoped.
- Time-To-Market Pressure. The average custom AI project requires 6–12 months for MVP delivery. API-first solutions typically show ROI within 4–8 months, fine-tuned models break even in 8–16 months, and in-house systems require 12–24 months.
The Worked Decision Path: Buy, Fine-Tune, Or Build
Use this ladder in sequence to decide whether to buy, fine-tune, or build.
- Does A General-Purpose Model With A Well-Engineered Prompt Already Solve The Problem? If yes, stop. A good prompt solves approximately 70% of AI use cases.
- Does Adding RAG Close The Remaining Gap? If yes, stop. RAG solves the next 25% at a fraction of the cost of fine-tuning.
- Is The Task Narrow, Repetitive, And High-Volume Enough To Amortize Fine-Tuning Costs? At 100,000 requests/month, a fine-tuned GPT-4o mini costs $36/month versus $300/month for prompting with GPT-4o, a saving that breaks even in one day. If volume stays below this threshold, the savings rarely justify the operations overhead.
- Does Fine-Tuning Still Leave An Unacceptable Accuracy Gap? Training from scratch is justified only when general models consistently perform below 75–80% accuracy even with RAG and fine-tuning, when data sovereignty requirements block external APIs, or when 100,000+ high-quality labeled examples and a business case for $250,000+ upfront investment exist.
- Are You A Creator, Agency, Or Content Team? A fourth path skips every tier of this ladder entirely.
The Fourth Path: Locked, Consistent Output Without A Custom Build
The ladder above assumes you need a model that can do many things. For creators, agencies, micro-influencers, anonymous and niche creators, and virtual influencer builders, the build-vs-buy question has a different answer: neither. The core problem for these teams is consistency, brand identity, and production volume rather than raw model performance. A fine-tuned model still ships a prompt box. Training from scratch still produces a general-purpose tool. Neither approach gives a creator their face back on demand.
Sozee is the AI Content Studio for the Creator Economy. Upload as few as three photos and Sozee reconstructs your likeness with hyper-realistic accuracy. You can also generate an entirely original character from scratch, a face that has never existed and stays consistent from the first frame onward. There is no training step, no waiting period, and no ML engineering salary or infrastructure to maintain.
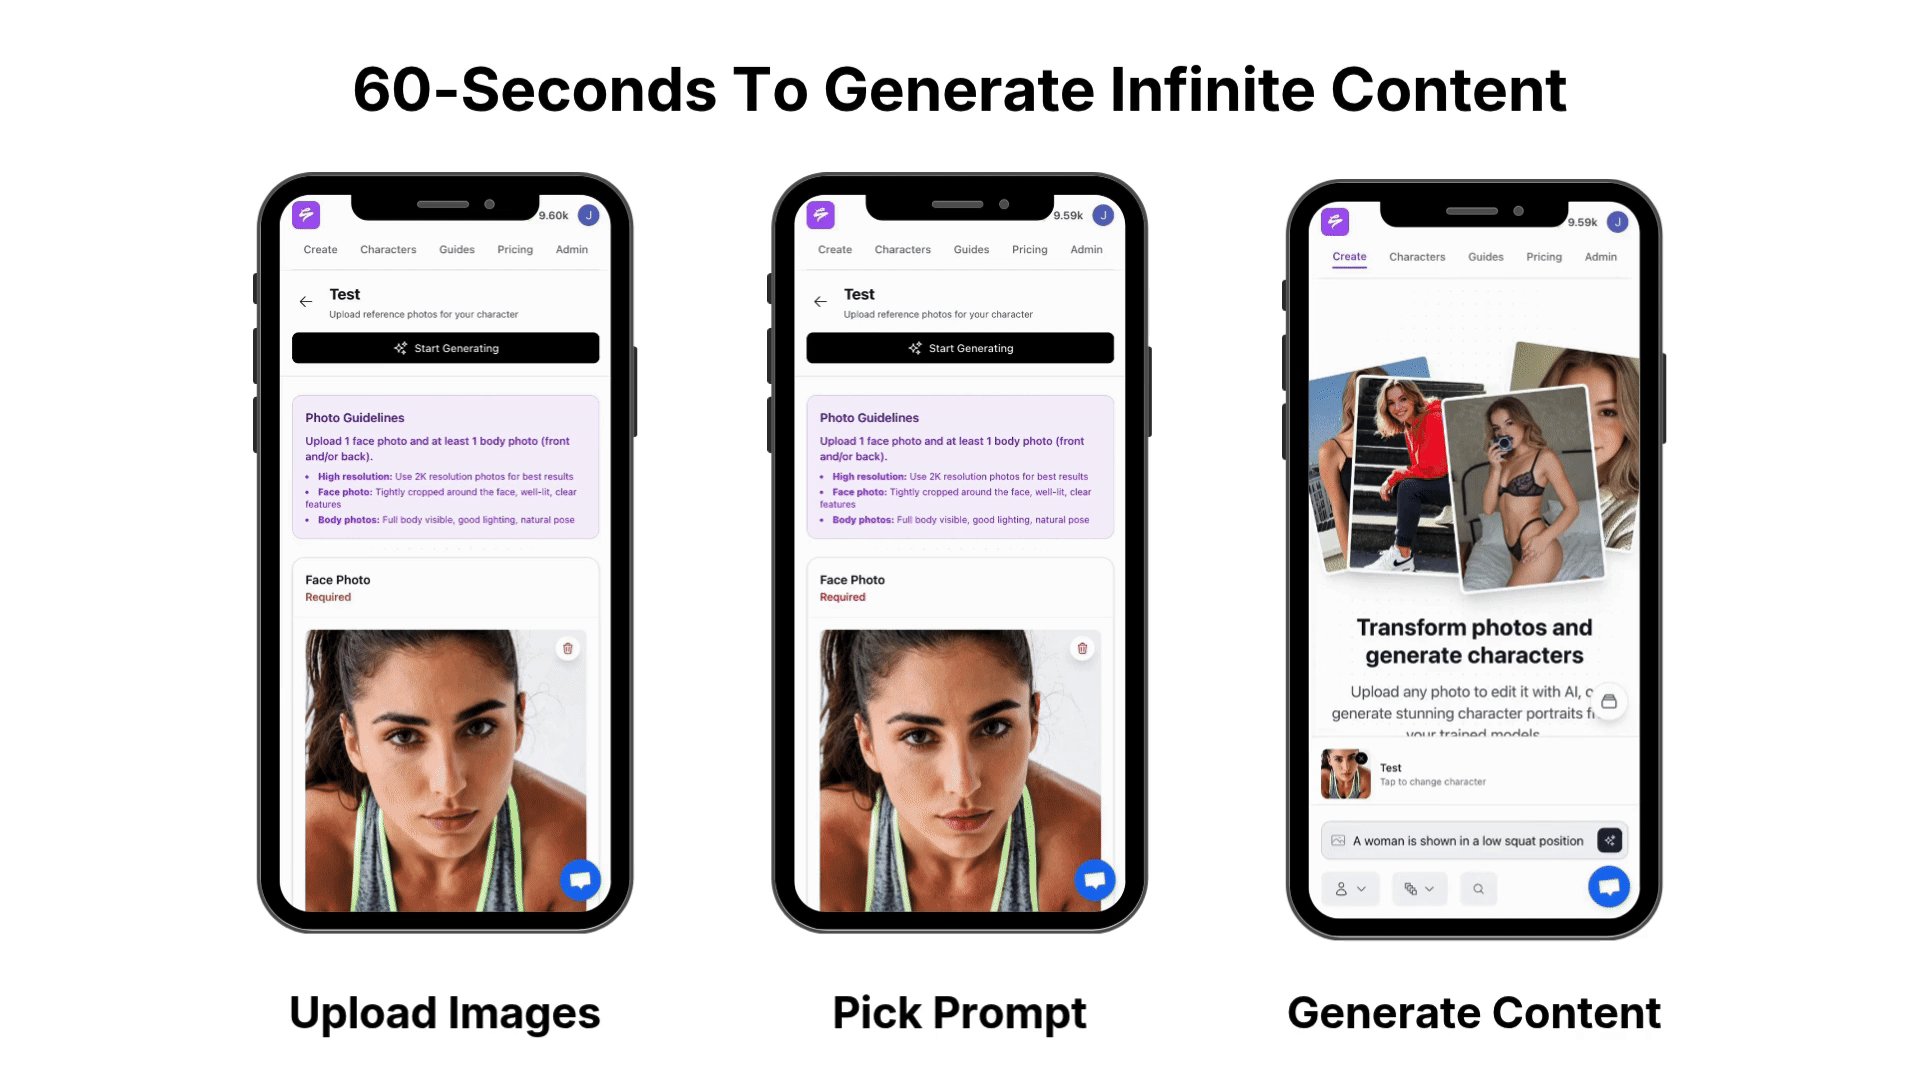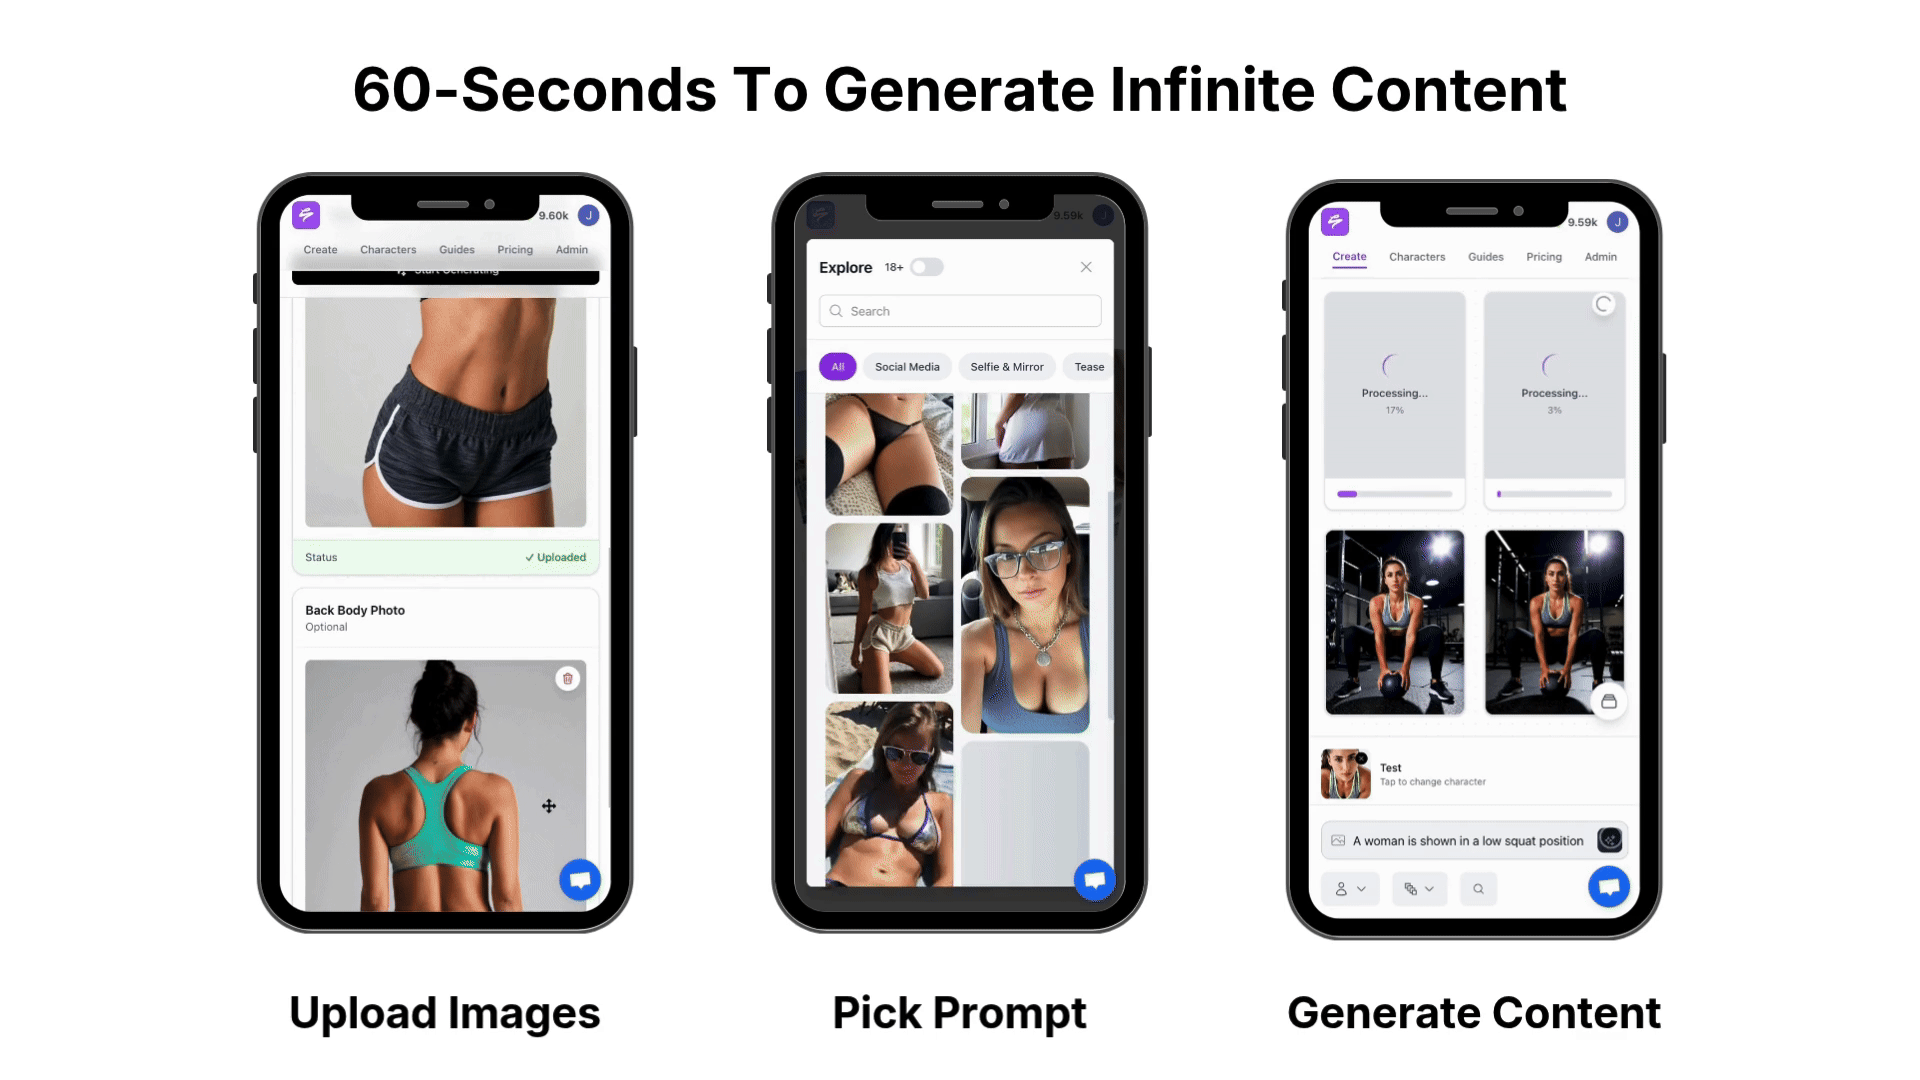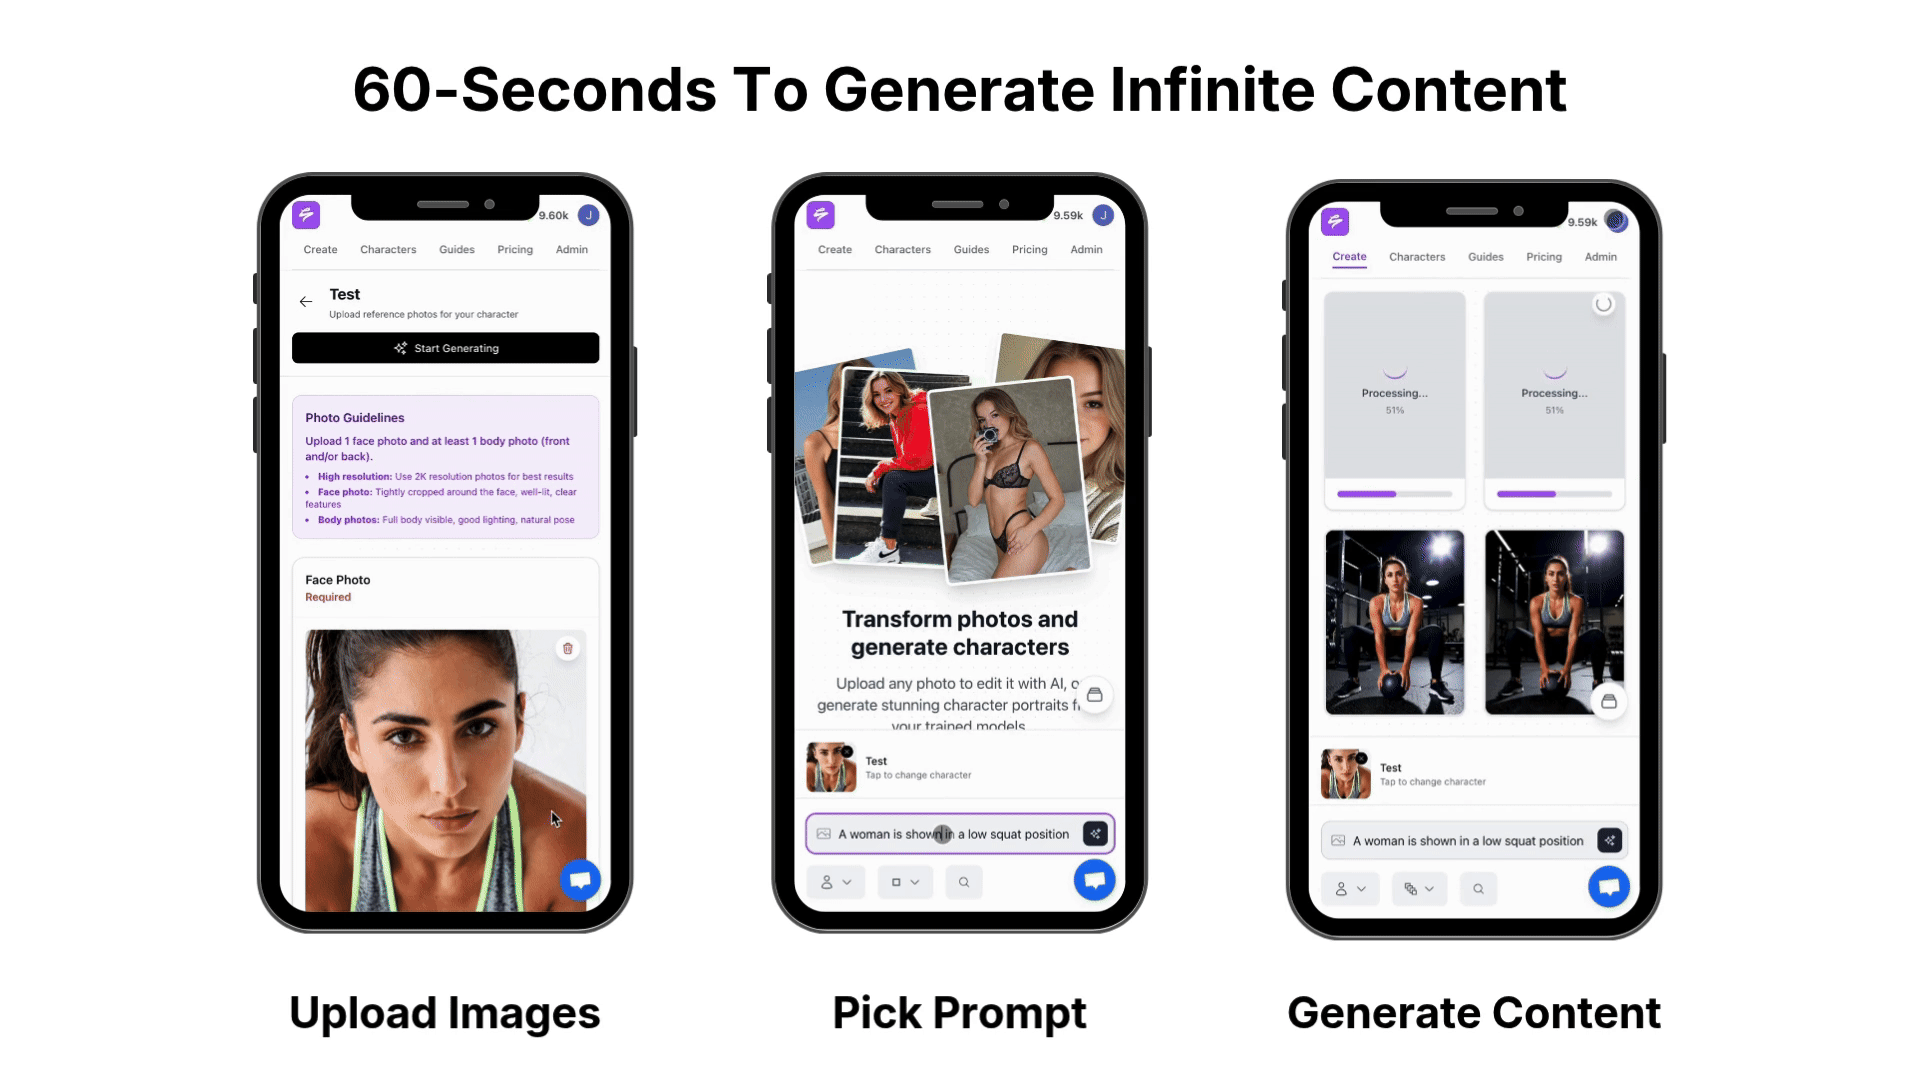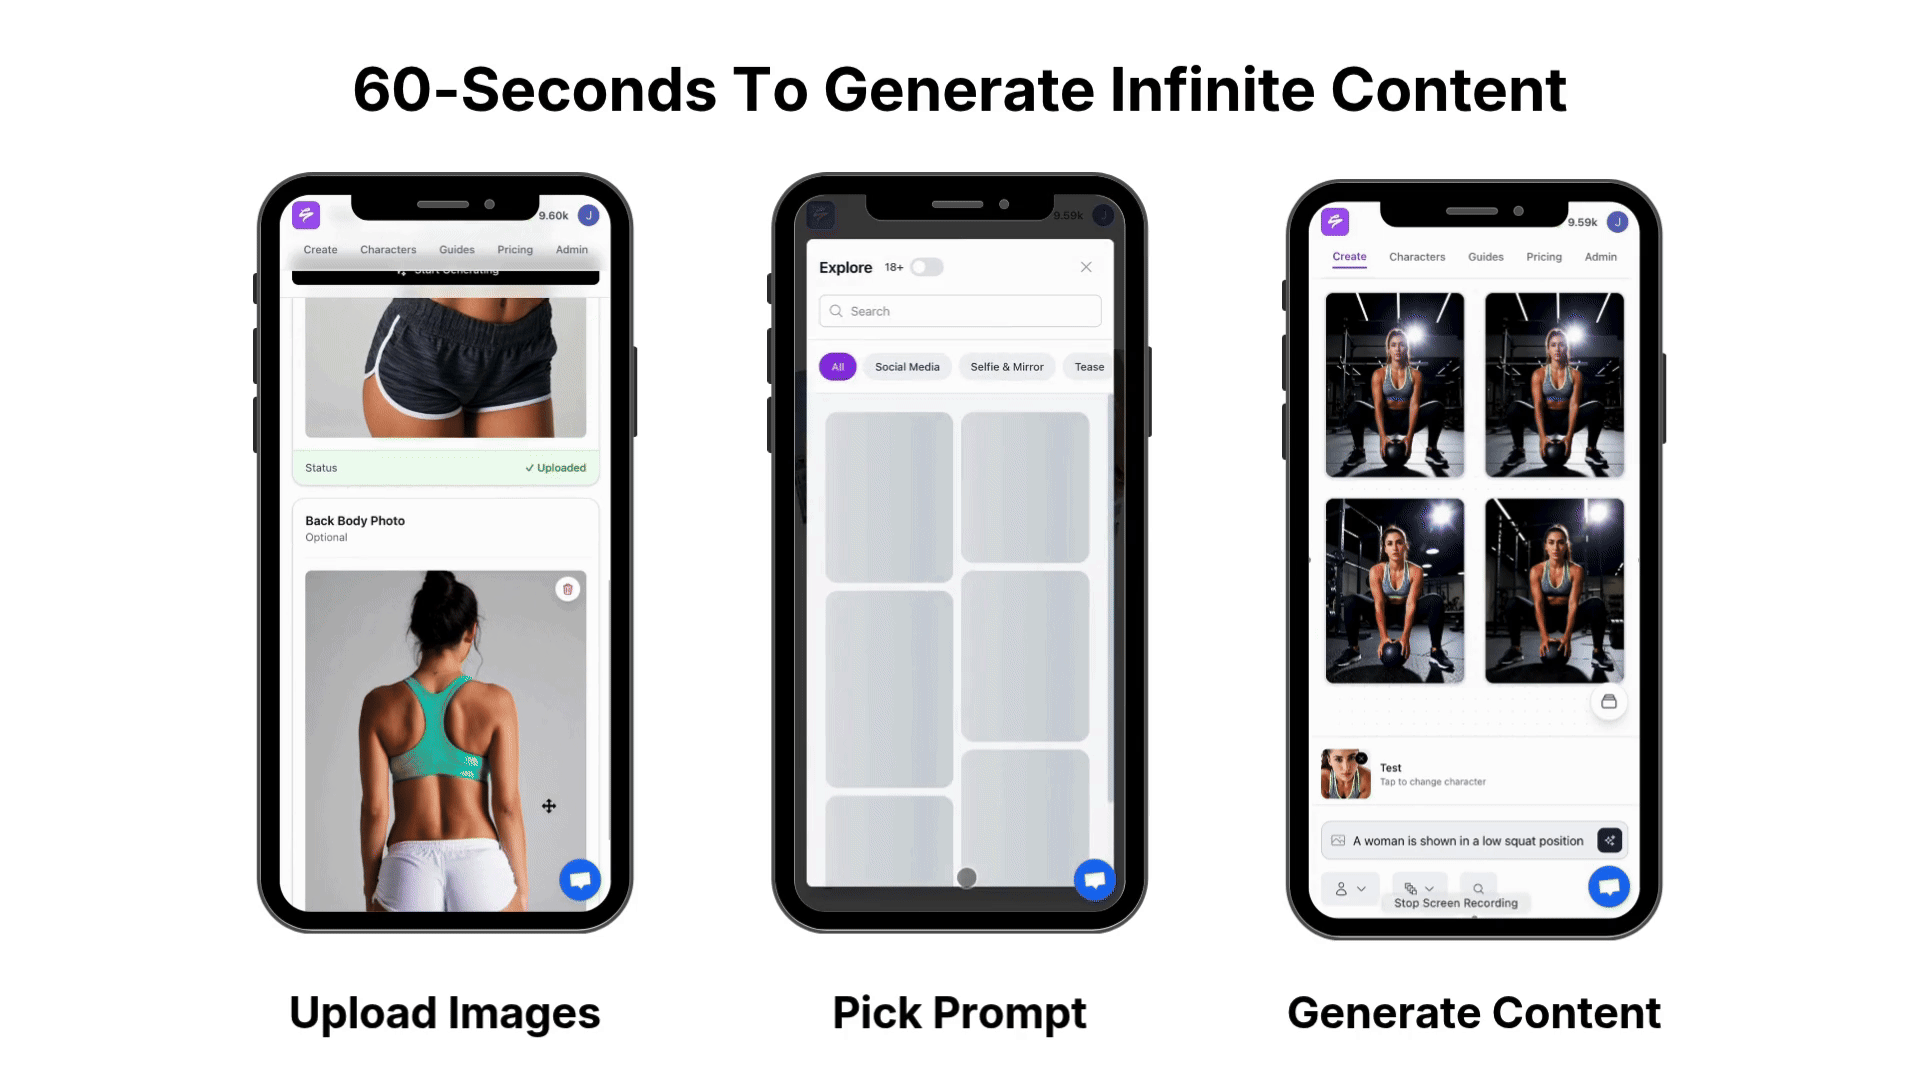
The controls below replace the prompt-and-pray slot machine with directable, repeatable output.
- Photo Control gives you five directable dimensions, including Setting, Outfit, Shot style, Expression, and Object, so every frame becomes a decision rather than a gamble.
- Locked Likeness keeps the same face and body across every frame, every set, and every week, which turns one-off images into a coherent brand.
- Reusable Environments come from up to four reference shots. You build a room once and shoot in it for a year.
- Outfit Library, Object Library, And @-References attach elements inline without breaking your train of thought.
- Photo Shoot turns one image into a locked, coherent set of up to ten, including a full SFW-to-NSFW arc with the ramp and ceiling set by you.
- Live Mode applies real-time character transformation on your camera feed so you act and your character performs.
- The Agent interviews a half-formed idea into a finished setup, writes straight into the prompt bar and Photo Control panel, and leaves the shoot one tap from Generate.
- The Vault, The Scheduler across Instagram, TikTok, X, Facebook, Reddit, and Fanvue, plus Analytics that separate what Sozee posted from what you posted.
General-purpose tools ship a prompt box. Sozee ships a studio. The value comes from avoiding the custom-build cost trap entirely while still getting the consistency that turns content into a brand. Privacy stays baked into the architecture, with models kept private, isolated, and never reused to train anything else.
Skip The Build And Start Creating
Real-World Scenarios
To see how that fourth path plays out in practice, here are four profiles that map directly to the build-vs-buy decision:
- Solo Creators Managing Their Own Content. The API bill for a general-purpose AI tool grows with usage and delivers inconsistent output. Fine-tuning requires ML skills they do not have. Sozee delivers locked likeness and a month of content in an afternoon with no build required.
- Agencies Handling Multiple Creators Across A Roster. A custom build per creator makes no economic sense. Off-the-shelf tools do not maintain brand consistency across a roster. Sozee’s teams and workspaces give one login and every client, fully isolated, each with its own characters, vault, connected accounts, and credits.
- Micro-Influencers Delivering Sponsor Quotas. A sponsorship is a quota: the product in three settings, four outfits, six angles, a reel, a carousel, and a story. A deal that pays a few hundred dollars can consume an entire shoot day. Sozee removes that ceiling. Drop the sponsor’s product into the Object slot, shoot it across as many settings and expressions as the brief requires, then schedule the whole campaign from the Vault.
- Virtual Influencer Builders Who Need Daily Posting And Locked Likeness. General-purpose AI tools cannot maintain character consistency at daily posting frequency. Training a custom model takes months and costs hundreds of thousands. Sozee generates an original character, locks her likeness, builds her world once, puts her in motion, and schedules her to post daily in one place.
Total Value Of Ownership
The custom-build cost trap extends well beyond the upfront number. It compounds through engineering salaries, infrastructure, retraining cycles, compliance overhead, and the opportunity cost of months spent building instead of publishing. Acropolium’s rule of thumb for real three-year AI cost: take build cost, add 20% for year-one post-launch costs, then budget 15%–25% of build cost as an annual recurring line item from year two onward.
Sozee’s value proposition inverts this structure. Scalability comes built in, because the same platform serves a solo creator and an agency roster without a different infrastructure decision for each. Operational efficiency compounds as every setting, outfit, object, and look built once is saved and makes the next shoot faster. Long-term consistency becomes the product, with locked likeness frame to frame, set to set, and month to month. Privacy functions as a structural guarantee, and risk drops at the source because there is no model to maintain, no retraining cycle to fund, and no ML engineer to retain.
For creators, the relevant comparison is custom AI versus the real cost of producing consistent, brand-grade content at scale without Sozee. The answer is burnout for solo creators, stalled growth for agencies, and turned-down brand deals for anyone whose output cannot keep pace.
Frequently Asked Questions
What Is The Cheapest Way To Get A Custom AI Model?
The lowest-cost path uses prompting and RAG on a general-purpose model, which usually costs tens to hundreds of dollars per month. As you move into fine-tuning or training from scratch, costs rise into the tens of thousands or millions. As noted earlier, the sticker price of compute understates total cost by 30%–50% once lifecycle expenses are included.
At What Point Do AI Subscriptions Become More Expensive Than Running Your Own?
The crossover depends on volume, task predictability, and utilization. Self-hosting a 70B-class model only undercuts managed APIs at roughly 60 million tokens per day of steady traffic. Below 10 million tokens per day, managed APIs are almost always cheaper once the fixed operations floor of $1,500–$2,500 per month is included. For most teams, the build-vs-buy analysis becomes worthwhile once the monthly API bill exceeds $10,000, per Abstract Algorithms’ decision framework.
What Is The Break-Even Point For Custom AI?
Break-even volume equals total fixed cost divided by per-unit savings. As the break-even section explains, fine-tuning typically requires 100M+ tokens per month with at least 70% in a repetitive task. For training from scratch, the crossover against managed APIs usually appears around 1–10 million queries per day. The break-even also shifts whenever API prices fall, and prices dropped by roughly 60%–80% between early 2025 and mid-2026.
Is Fine-Tuning Cheaper Than Training From Scratch?
Fine-tuning is cheaper by one to four orders of magnitude on raw compute. Fine-tuning a 7B model costs $50–$500 in infrastructure, while training the same-sized model from scratch costs $500,000–$2,000,000 in compute alone. The gap widens further when engineering time is included, because a fine-tuning iteration can finish in hours while a scratch training run locks up a GPU cluster for weeks or months. Fine-tuning also inherits the base model’s general capabilities, so it only needs to learn the delta rather than rediscover language from zero.
Do I Need ML Engineers To Go Custom?
For fine-tuning, you need at least one ML engineer and several weeks of their time, plus ongoing maintenance. For training from scratch, you need a dedicated research team, a GPU cluster, and a six-to-eighteen-month minimum timeline. The all-in annual cost of a single mid-level US AI engineer is $180,000–$250,000. A three-person in-house AI team costs $310,000–$700,000 annually before any code is written. These are not one-time costs; they recur annually and compound with every retraining cycle, which is why the break-even math rarely favors custom builds for teams without existing ML capacity.