
Last updated: September 16, 2026
Key Takeaways
- FLUX.1-dev LoRA training attaches low-rank adapters to a 12B rectified-flow transformer to learn specific subjects, styles, or characters without altering base weights.
- The workflow demands 15–50 high-quality images, descriptive natural-language captions, careful VRAM management (12–80 GB), and systematic checkpoint validation to avoid overfitting.
- Training is governed by the FLUX.1 [dev] Non-Commercial License, so any LoRA created is a Derivative that cannot be used commercially without a separate license from Black Forest Labs.
- Practical training requires choosing between Kohya sd-scripts, AI Toolkit, FluxGym, or Replicate, each with distinct hardware, UI, and configuration trade-offs.
- Sozee reconstructs your likeness from three photos with no training required, so you can skip the full experiment.
How To Train a FLUX.1-dev LoRA: Step-By-Step Workflow
- Confirm licensing and hardware: verify your use case is non-commercial and that your GPU meets the VRAM floor for your chosen trainer.
- Assemble and caption the dataset: collect 15–50 varied images and write descriptive natural-language captions with a consistent trigger token.
- Install Kohya sd-scripts or choose an alternative trainer such as AI Toolkit, FluxGym, or Replicate.
- Configure
flux_train_network.pyflags: set rank, alpha, learning rate, optimizer, mixed precision, and FLUX-specific flow-matching arguments. - Run training with checkpoint saves every 500 steps so you have multiple candidates to evaluate.
- Generate a fixed validation set at each checkpoint using identical prompts, seeds, and sampler settings.
- Select the best checkpoint and export the
.safetensorsfile. The best checkpoint is almost never the last one.
If you would rather skip the experiment entirely, Sozee reconstructs your likeness from three photos with no training required.
What You Are Actually Training: LoRA Adapters On a 12B Rectified-Flow Transformer
A FLUX.1-dev LoRA trains low-rank adapter weights inserted into the transformer blocks of a 12-billion-parameter rectified-flow transformer, not a convolutional U-Net. That distinction shapes every configuration decision you make.
SDXL’s base UNet contains approximately 2.6 billion parameters, as reported in Table 1 of the SDXL paper, and uses a single latent space with 4 channels (in_channels: 4, out_channels: 4). FLUX.1-dev’s full pipeline totals roughly 16.87 billion parameters. It has four components: an 11.9B denoiser, a ~4.76B T5-XXL text encoder, a ~123M CLIP-L text encoder, and a ~84M 16-channel VAE. The architecture is an MM-DiT (Multimodal Diffusion Transformer) consisting of 57 transformer blocks. Nineteen dual-stream blocks process text and image tokens through separate attention pathways, and 38 single-stream blocks concatenate them into a unified sequence.
FLUX.1-dev is roughly 4.6× larger than SDXL and uses a fundamentally different MM-DiT attention architecture. SimpleTuner warns that on the 12B FLUX model, LoRA at 1e-3 might totally roast the thing, while LoRA at 1e-5 does nearly nothing, so the effective learning rate window is narrow. Kohya sd-scripts exposes layer-type-specific rank controls including img_attn_dim, txt_attn_dim, img_mlp_dim, and single_dim. These controls allow different ranks per attention, MLP, and modulation layer. By default, training targets the DiT transformer blocks. Text encoder training is optional and controlled separately via train_t5xxl in network args.
FLUX uses dual text encoders, CLIP-L and T5-XXL. T5 handles semantic understanding of long sentences and complex syntax up to 512 tokens, while CLIP handles visual concept alignment. This design makes FLUX respond to descriptive natural-language prompts rather than tag strings, and your captions must follow the same pattern.
That architecture also shapes how much data you need. Because FLUX learns from natural-language captions rather than tags, a small, well-captioned set can outperform a large, noisy one.
How Many Images You Need For a FLUX.1-dev LoRA
One dataset guide lists 15 images as the FLUX.1 minimum, with 20–30 described as the comfort zone, though other guides state there is no universal image count. The right count depends heavily on what you are training, because a face needs far fewer images than a style. Here are the practical ranges by subject type:
- Person or character: 15–20 images is the beginner minimum, while 25–40 images is the ideal sweet spot for production face quality.
- Product or object: 20–50 images.
- Style: 50–200+ images are commonly recommended because style datasets scale differently and use a separate step-count formula, though some official guidance (e.g., FLUX.2 [klein]) recommends a smaller optimal dataset of 20–40 images.
Twenty-five varied images beat 60 near-duplicates every time. Near-duplicates silently reweight one composition: four similar frames in a twenty-image dataset make that view one fifth of the total evidence. Artifacts are the other silent failure mode. FLUX will absorb the artifacts in your images first, and then learn the concept or subject, so watermarks, compression artifacts, and motion blur corrupt a FLUX LoRA faster than they would on smaller SD models. That is why any image that fails a quality floor of no blur, no heavy compression, and a readable face or clearly defined subject should be rejected before it enters the dataset.
Balance framing across close, medium, and wider views. Vary location, lighting, outfit, pose, expression, and camera angle while keeping the subject constant. Whatever repeats across images gets baked into the LoRA, so a repeated background wall becomes part of the identity.
How To Caption Images For FLUX.1-dev LoRA Training
The trigger token strategy for FLUX.1-dev LoRA training is one consistently spelled trigger phrase, unique enough not to carry a strong preexisting meaning. Patterns such as sksriver person for identity, skslume lamp for objects, and sksgrain poster style for styles work because they are unlikely to collide with concepts the base model already knows.
The core captioning principle is that the model learns to attribute whatever the caption does not explain to the trigger word. Every caption must describe clothing, pose, expression, framing, lighting, and background so the model attributes only the unexplained stable pattern, the subject’s identity, to the trigger. A caption like “A medium portrait of sksriver person wearing a green rain jacket, looking left on a wet city street at night, soft storefront light, shallow depth of field” leaves nothing ambiguous except the face.
FLUX prompts should be written as complete descriptive sentences rather than comma-separated tag strings, because the T5-XXL encoder is trained for natural language understanding and is sensitive to syntactic structure. SD-era quality incantations like “masterpiece, best quality, 8k” affect FLUX output about as much as random noise. That sensitivity to natural language also means caption errors matter more. Automated captioners regularly invent colors, genders, objects, and relationships, so review every caption beside its image before training.
FLUX.1-dev LoRA Training VRAM Requirements: 12GB To 80GB
Rank-16 full-component FLUX.1-dev LoRA training can exceed 40GB of VRAM without quantization or block swapping. The practical VRAM ladder using --fp8_base in Kohya sd-scripts, as documented in the Kohya sd-scripts flux_train_network configuration, is:
- 24GB (RTX 3090/4090): Batch size 2, no block swapping, the practical sweet spot for a weekend training run.
- 16GB: Batch size 1 plus
--blocks_to_swap. - 12GB:
--blocks_to_swap 16plus AdamW8bit optimizer. - 10GB:
--blocks_to_swap 22plus FP8 T5-XXL checkpoint. - 8GB:
--blocks_to_swap 28plus FP8 T5-XXL checkpoint, functional but slow.
SimpleTuner’s measured VRAM footprints for a rank-16 FLUX.1 LoRA show approximately 30GB unquantized, 18GB with int8, 13GB with int4, and 9GB with NF4. These are configuration-specific measurements, not universal tiers. A run that looks safe after ten steps can still fail when validation begins, because validation reloads components and creates larger latents. When a 24GB card is the ceiling and a rank-16 run at 1024px is the goal, cloud training on a 48GB A40 or L40S eliminates block-swapping overhead and is often the practical choice for a weekend deadline.
Which Trainer To Use: Kohya sd-scripts vs AI Toolkit vs FluxGym vs Replicate
The four main trainers differ most in interface, VRAM floor, and who they suit best. The table below compares them at a glance before you dig into the trade-offs.
| Trainer | Interface | VRAM Floor (FLUX.1-dev, fp8_base) | Best-Fit User |
|---|---|---|---|
Kohya sd-scripts (flux_train_network.py) |
CLI / config file | 8GB with –blocks_to_swap 28 + fp8 T5-XXL | Practitioners who want full parameter control and layer-specific rank tuning |
| AI Toolkit (ostris) | Web UI + CLI (YAML config) | 24GB (quantized, batch 1, gradient checkpointing) | Users who want a web dashboard, checkpoint previews every 250 steps, and cloud escape hatches (RunPod/Modal) |
| FluxGym | Gradio web form | 12GB with –blocks_to_swap 16 + fp8_base | Users on constrained hardware who prefer a GUI over terminal configuration |
| Replicate | Browser / API | No local VRAM required | Users who want zero local setup and are comfortable with per-run cloud costs |
Kohya sd-scripts’ flux_train_network.py is the most configurable option. It exposes block-level rank controls, selective block training via index ranges, split QKV mode for Diffusers interoperability, and native FP8 precision. Its FLUX LoRA implementation supports three text encoder configurations: DiT only, FLUX + CLIP-L, and FLUX + CLIP-L + T5-XXL. These modes give precise control over which components receive gradients. The tradeoff is a steeper configuration surface, because flags evolve across releases and the wrong combination silently degrades results.
AI Toolkit is the cleaner starting point for most practitioners. Its reference config for FLUX.1-dev targets 24GB with rank 16, alpha 16, learning rate 1e-4, AdamW8bit, batch size 1, 2,000 steps, and resolution buckets of 512/768/1024, and it renders sample images every 250 steps so checkpoint selection is visual rather than guesswork. FluxGym wraps Kohya sd-scripts under the hood and adds CPU-GPU block swapping in the UI, which makes it the practical choice when the GPU is below 20GB and a terminal is unwelcome. Replicate removes all local hardware requirements at the cost of per-run pricing and less configuration depth.
What Learning Rate and Rank To Use For FLUX LoRA Training
These starting points for FLUX.1-dev LoRA training come from Kohya sd-scripts and SimpleTuner documentation:
- Network rank (–network_dim): 16
- Network alpha (–network_alpha): 16 (or 8, approximately half of rank)
- Transformer learning rate (–learning_rate): 1e-4
- Text encoder learning rate (–text_encoder_lr): 1e-5 for CLIP-L when training text encoders
- Optimizer: AdamW8bit
- Mixed precision: bf16
- Batch size: 1
- Gradient checkpointing: enabled
- Steps: 500–2,000 is a common range, and a 25-image dataset at ~120 steps per image targets approximately 3,000 steps
- Checkpoint saves: controlled by
--save_every_n_steps, which Runpod recommends setting to the number of steps per epoch or a multiple of that (e.g., 500 steps if that matches the epoch length)
FLUX.1-dev requires three flow-matching flags that override defaults designed for DDPM models. Kohya sd-scripts documentation recommends --timestep_sampling flux_shift, --model_prediction_type raw, and --guidance_scale 1.0 for dev training. Leaving guidance at the inference default of 3.5 is a documented cause of low-quality outputs. A minimal Kohya command block looks like this:
accelerate launch flux_train_network.py \ --pretrained_model_name_or_path="path/to/flux1-dev.safetensors" \ --network_module=networks.lora \ --network_dim=16 \ --network_alpha=16 \ --learning_rate=1e-4 \ --text_encoder_lr=1e-5 \ --optimizer_type="AdamW8bit" \ --mixed_precision="bf16" \ --gradient_checkpointing \ --sdpa \ --timestep_sampling=flux_shift \ --model_prediction_type=raw \ --guidance_scale=1.0 \ --discrete_flow_shift=3.1582 \ --save_every_n_steps=500 \ --save_model_as=safetensors \ --max_train_steps=2000Flags evolve across releases. Always check the Kohya sd-scripts flux_train_network.md documentation for the current supported argument list before running. Arguments valid in one release, such as --clip_skip, are listed as incompatible or deprecated for FLUX in later versions.
Once the run is configured correctly, the next decision is which checkpoint to keep, and that is where many practitioners leave quality on the table.
How To Pick the Best Checkpoint Using a Validation Set
Checkpoint selection is where most practitioners leave quality on the table. The professional workflow treats training as an experiment with a fixed control. Before the run starts, define a validation prompt set that tests identity fidelity, prompt flexibility, and image quality independently.
A useful validation set for a character LoRA includes:
- An unseen outfit and background not present in the training data.
- Close, medium, and full-body framing prompts.
- An unfamiliar expression or pose.
- Different lighting conditions.
- A prompt without the trigger token, to test whether the LoRA has overfit to the trigger.
Generate the full validation set at 500, 1,000, 1,500, and 2,000 steps using identical seeds, sampler settings, and guidance values. Later checkpoints know the face better but obey prompts worse, so the earliest checkpoint that nails the identity before overfit signs appear is usually the one to keep. Overfit signs include waxy skin, frozen expression, and dataset outfits bleeding into unrelated prompts. Loss alone cannot tell whether prompt control survives. Only the validation grid can.
Is FLUX.1-dev LoRA Training Free or Commercial?
FLUX.1-dev is released under the FLUX.1 [dev] Non-Commercial License v1.1.2 issued by Black Forest Labs. The license defines a Derivative as any modified version of the model, including any customized or fine-tuned version. A trained LoRA falls under that definition. LoRA weights trained on FLUX.1-dev inherit the same non-commercial restriction unless a separate commercial license is obtained from Black Forest Labs.
The license draws a clear line between the model and its outputs. Generated outputs are not considered Derivatives, and Black Forest Labs claims no ownership rights in outputs, so users may use generated images for personal, scientific, and commercial purposes. Selling images generated with a FLUX.1-dev LoRA is therefore permitted under the output clause, provided the generation itself did not occur in a commercial production environment. Using the LoRA in a customer-facing product, a revenue-generating API, or any production deployment requires a separate commercial license from Black Forest Labs, available directly from Black Forest Labs.
Black Forest Labs introduced Self-Hosted Commercial License Terms in June 2025, with Builder, Platform, Professional, and Enterprise tiers that include LoRA creation rights at different usage scopes. If your workflow is commercial, read the current license text directly rather than relying on community interpretations, because the distinction between output use and model use is precise and the consequences of misreading it are material.
That licensing complexity is one reason some creators look for a different path entirely.
When Training a FLUX.1-dev LoRA Is Not the Right Answer
FLUX.1-dev LoRA training is a real ML experiment. It requires a curated dataset, a configured trainer, VRAM headroom, a validation protocol, and checkpoint selection judgment. It also produces a Derivative that inherits a non-commercial license. For practitioners who need a locked, commercial-safe likeness without managing any of that, a different path fits better.
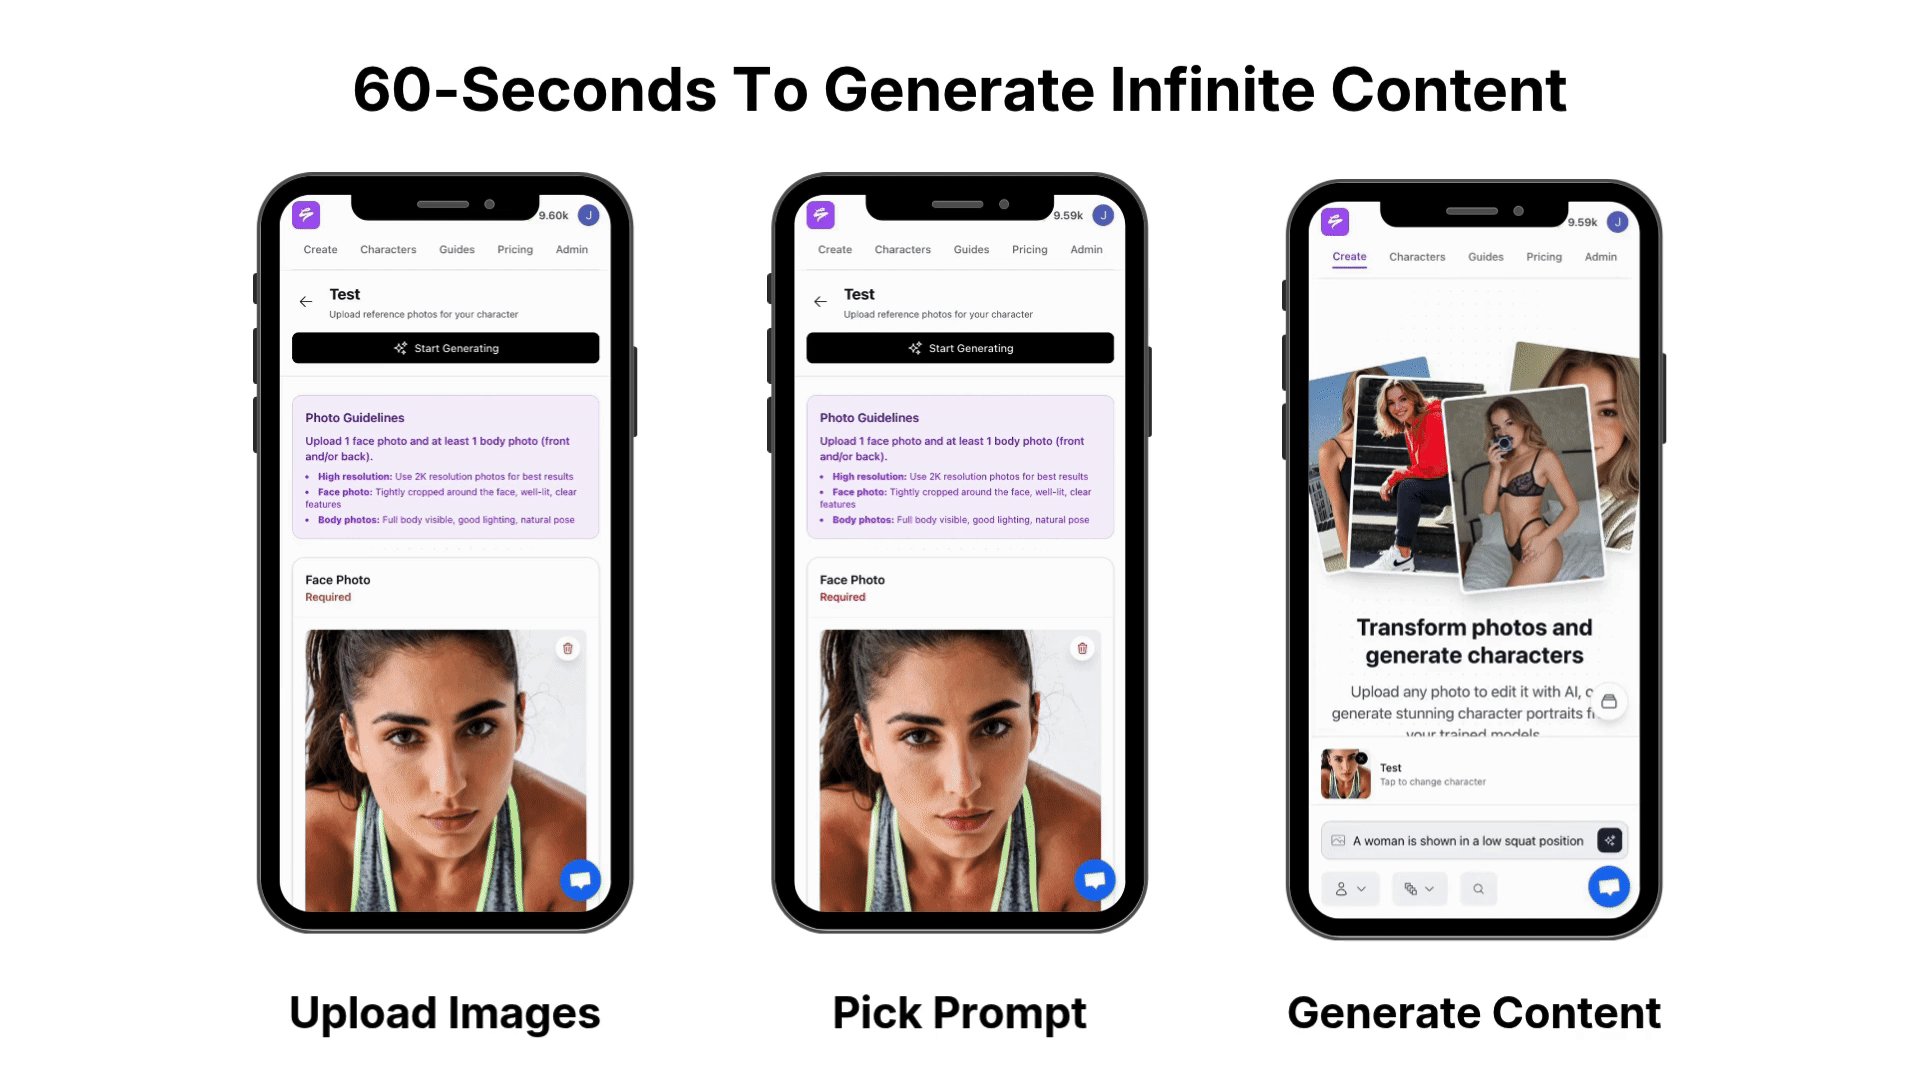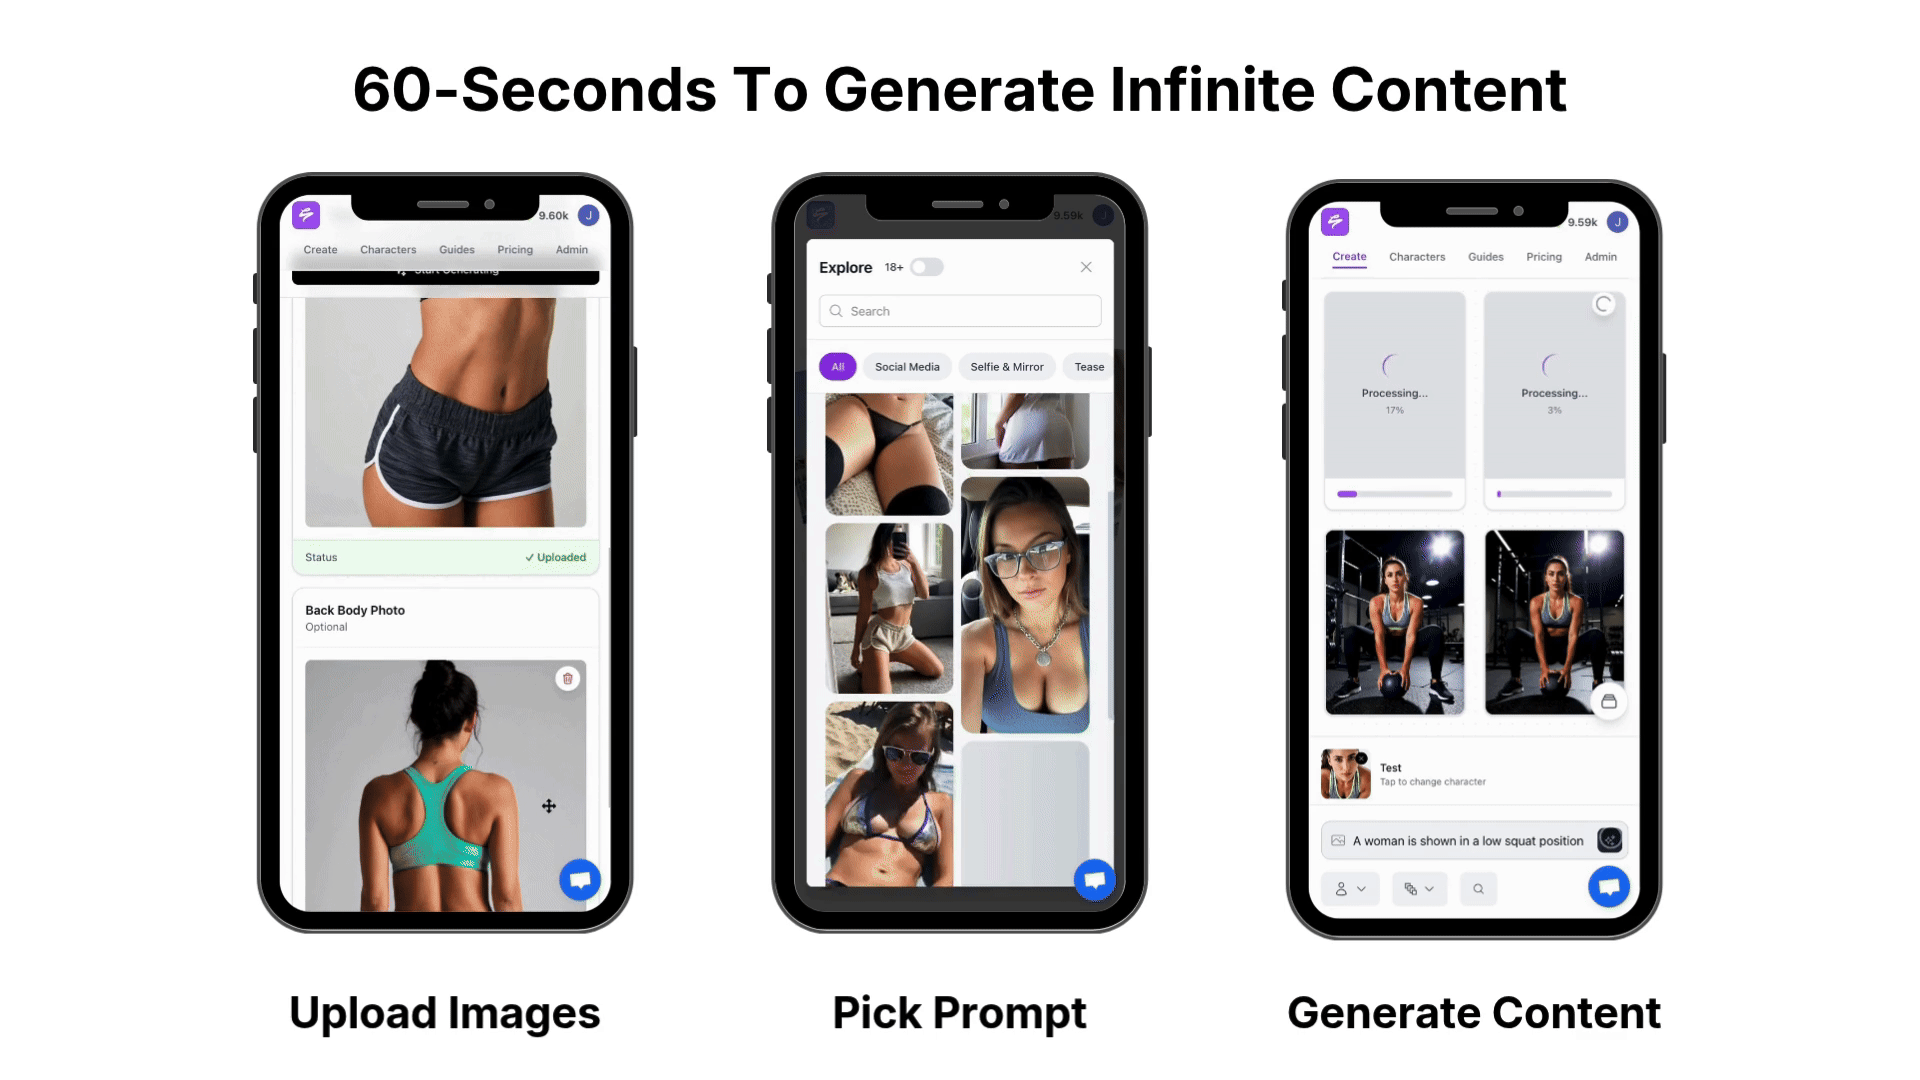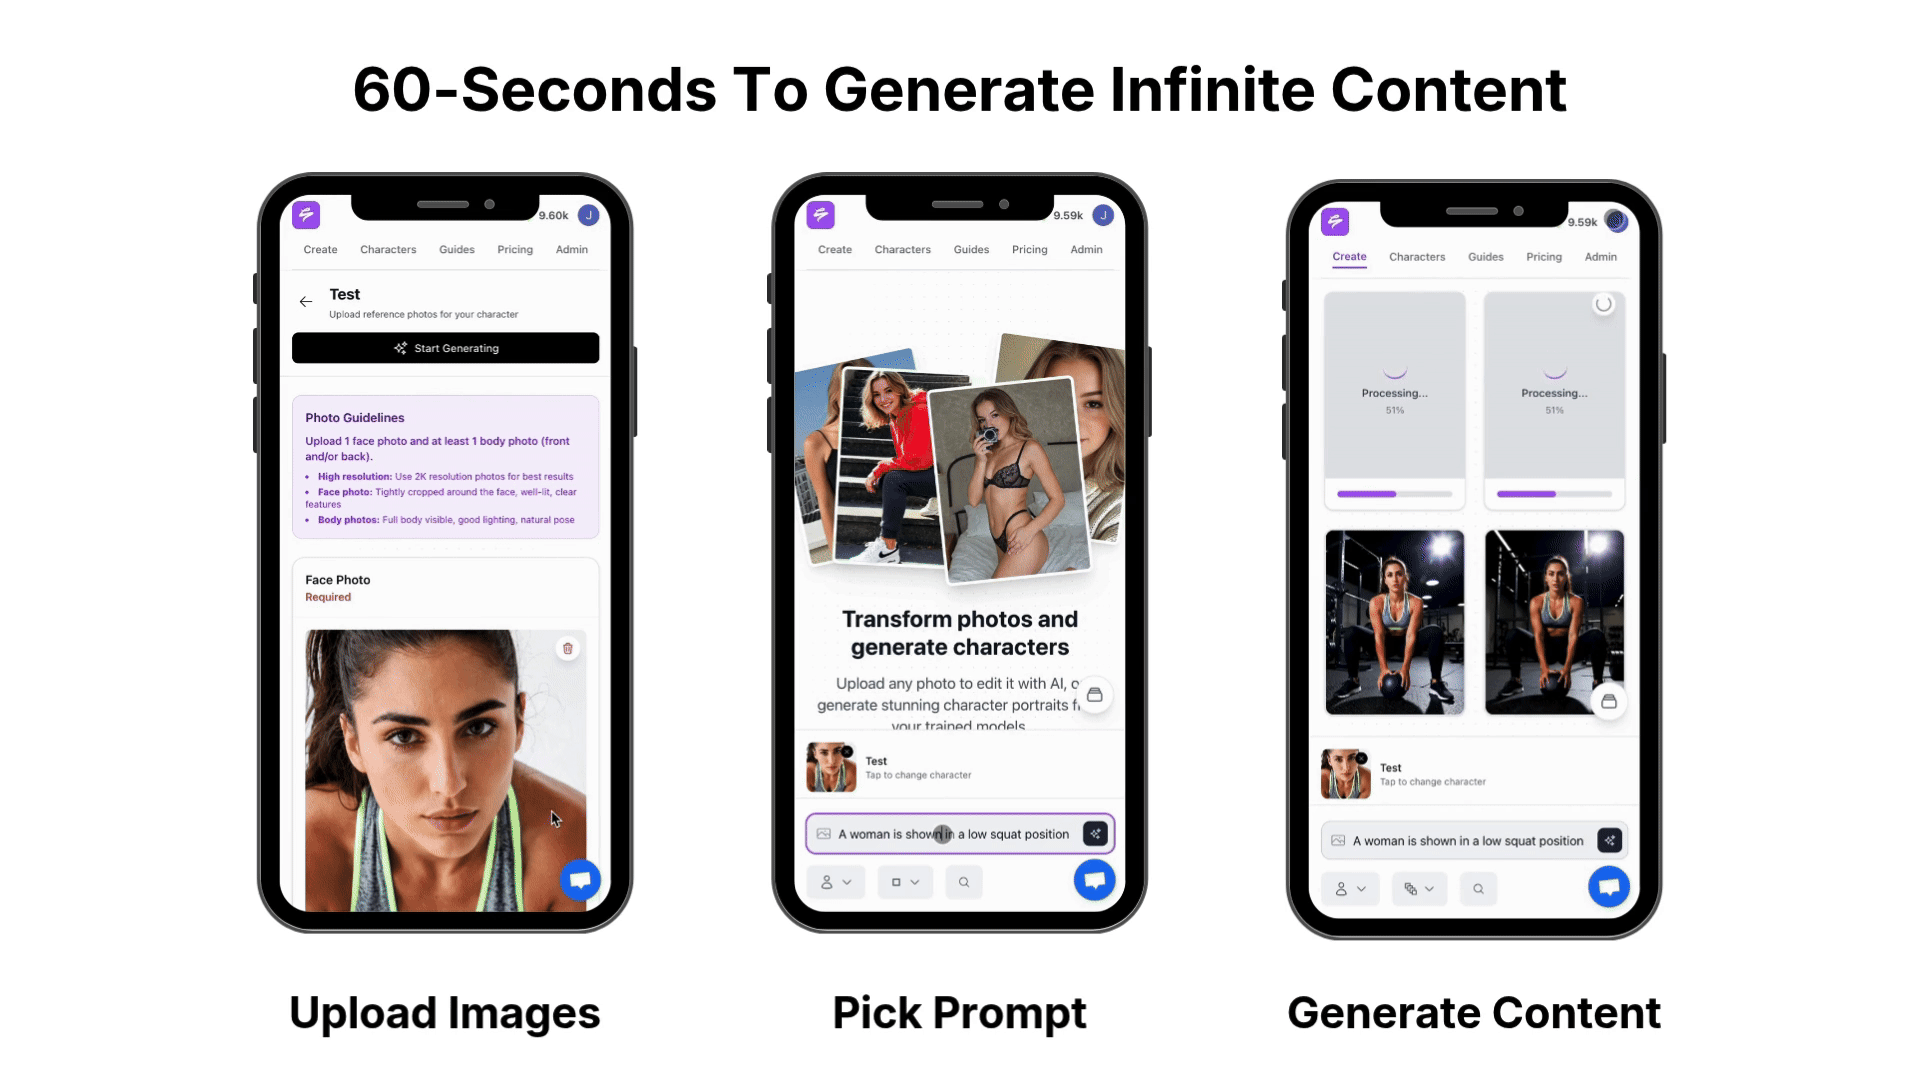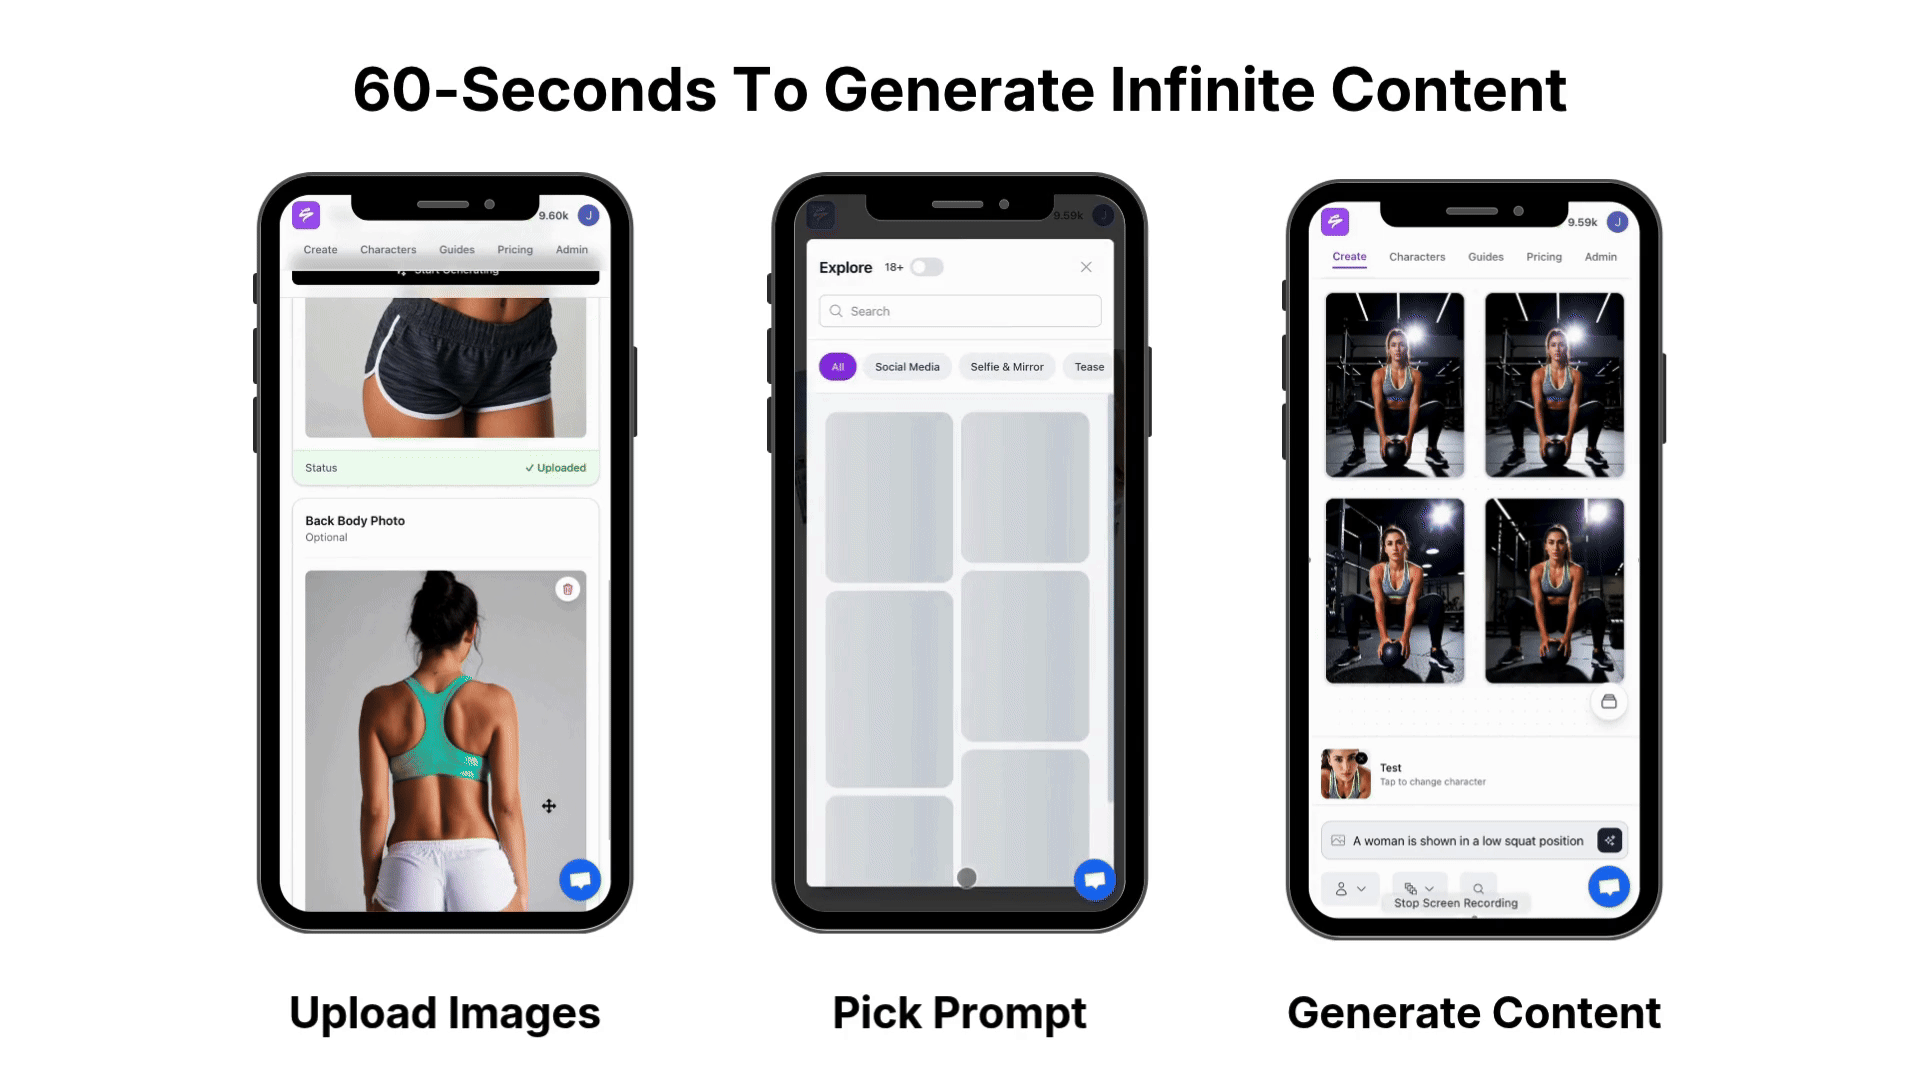
Sozee requires no training. Upload as few as three photos and Sozee reconstructs your likeness instantly, with the same face and body across every frame, set, and week. Likeness stays locked across Photo Control’s five dimensions: Setting, Outfit, Shot style, Expression, and Object. Environments and outfits are saved as reusable assets. The Agent sets up shoots conversationally, writing directly into the prompt bar and Photo Control panel so the shoot is one tap from Generate.
You skip dataset curation, VRAM management, checkpoint selection, and license navigation entirely. The output is a consistent character or persona ready for commercial content workflows.
Which Path Fits You? Three Creator Profiles
Three creator types show where FLUX training and Sozee each shine. A technical artist with a 24GB GPU and time for experiments benefits from FLUX.1-dev LoRA training, because they gain portable weights and fine-grained control. A small agency that needs repeatable campaign visuals but lacks ML expertise fits Sozee better, because it trades configuration work for a guided interface. A solo creator who wants a stable on-camera persona across platforms usually gets the fastest results by locking their likeness in Sozee and skipping training entirely.
Frequently Asked Questions
How Long Does It Take To Train a FLUX.1-dev LoRA?
Training time depends on GPU, step count, resolution, and whether block swapping is active. On a 24GB RTX 4090, a rank-16 LoRA trained on 20–30 captioned images at 1024px takes roughly 1–3 hours. On a 16GB card with block swapping enabled, the same run takes longer due to CPU-GPU transfer overhead. On a 48GB cloud GPU such as an A40, a typical FLUX LoRA training run completes in 10–20 minutes, and a 2,000-step run on a serverless cloud platform takes about 20–25 minutes of GPU time. Style LoRAs trained on larger datasets at higher step counts can run overnight on any tier.
How Much Does It Cost To Train a FLUX.1-dev LoRA?
Local training on owned hardware has no per-run cost beyond electricity, but requires a GPU with sufficient VRAM. A 24GB RTX 3090 or 4090 is the practical minimum for a comfortable rank-16 run at 1024px. Cloud GPU rental costs vary by provider and GPU tier. An A40 at approximately $0.44/hr and an A100 PCIe at approximately $1.39/hr are common reference points. A 2–3 hour run on an A40 costs roughly $0.88–$1.32. Failed setup attempts, checkpoint downloads, and storage fees add to the total, so compare full experiment cost, not just hourly rate, when choosing between local and cloud hardware.
Can I Sell Images Made With a FLUX.1-dev LoRA?
Yes. As covered in the licensing section, outputs are not Derivatives, so you can sell generated images. The restriction applies to using the LoRA itself in a commercial production environment, which requires a separate license from Black Forest Labs.
What Is the Easiest Alternative If I Do Not Want To Train?
Sozee is the no-training path described above. Upload three photos and you get a locked likeness without any dataset, VRAM, or licensing work. Upload three photos and lock your likeness.
Conclusion: Train It or Direct It
Training a FLUX.1-dev LoRA is a real ML experiment that involves dataset curation, trainer configuration, VRAM management, validation-set checkpoint selection, and a non-commercial license that applies to every Derivative you produce. Done correctly, it produces a portable .safetensors file that steers a 12-billion-parameter rectified-flow transformer toward a specific subject or style. Done incorrectly, with the wrong learning rate, a near-duplicate dataset, no validation set, or the wrong guidance scale, it produces an overfit file that copies your training images and ignores your prompts.
Practitioners who want to own the weights and have the hardware and time to run the experiment properly can follow the workflow above as an honest pipeline. Creators, agencies, and virtual influencer builders who need a locked, commercial-ready likeness without managing any of that infrastructure can choose Sozee and skip the experiment entirely.
Build a month of consistent content without training a model.