
Last updated: September 1, 2026
Key Takeaways for Consistent Avatar Video
- Most AI video tools struggle to keep a character’s identity stable across scenes, which blocks long-term brand building.
- Consistency works as a system-level feature. Platforms that anchor generations to saved visual references deliver the most reliable results.
- Talking-head tools like HeyGen and Synthesia excel at scripted delivery but give limited control over setting, outfit, and shot style.
- Cinematic tools like Runway and Kling offer rich visuals but demand complex manual workflows to keep a character consistent across videos.
- Sozee is the only all-in-one platform that locks likeness from just three photos and adds creative controls, scheduling, and analytics. Start creating your first consistent avatar.
Why Consistency Matters for Brand-Building Avatars
Brand recognition, audience trust, and monetization all depend on a character that looks the same every time. When a creator’s AI avatar changes face between posts, followers cannot form an attachment to the character. Sponsors cannot build campaigns around an identity that shifts. Revenue stalls.
Reddit threads on consistent character AI are filled with this frustration, with creators describing their tools as generating “a different person every time.” Character consistency in AI video is a system-level property, not a model feature. Even advanced AI video systems fail to maintain persistent identity across generations without a deliberate workflow built around locked references. The tools that come closest to solving this problem fall into two categories: talking-head platforms and cinematic tools. Each category covers part of the need.
Talking-Head Tools for Scripted Consistent Avatars
Talking-head platforms specialize in presenter-style video where a character speaks directly to camera, lip-synced to a script. They deliver strong consistency within a single video and focus on reliability over creative flexibility.
Synthesia launched its Express-2 avatar model with Synthesia 3.0 in October 2025, using a diffusion transformer architecture that combines facial expressions, lip sync, and natural hand and body gestures. This upgrade helped the platform serve over 60,000 companies and maintain SOC 2 Type II certification and ISO 27001 compliance, which keeps it a dominant choice for enterprise training and compliance video. Its 2026 avatars achieve 43% more emotional nuance than 2024 models. Many viewers still experience an uncanny valley effect, with eye contact and micro-expressions that feel stylized rather than fully photorealistic for marketing.
HeyGen released Avatar V in April 2026, achieving a face similarity score of 0.840, substantially outperforming Veo 3.1’s 0.714, from a 15-second selfie clip. Avatar V separates performance from appearance, so users record once and then choose different outfits or settings while keeping real movements and expressions. HeyGen’s streaming inference framework keeps the avatar’s likeness and voice locked for up to 30 minutes of continuous video. Avatar V remains a talking-head system, so it shines for scripted presenter delivery and feels less natural for cinematic storytelling with varied action.
Colossyan targets workplace learning with its NEO 2 avatar model, supporting interactive in-video quizzes, branching multi-avatar conversation scenes, and SCORM export for LMS platforms. Higher-fidelity output is capped at roughly 10 minutes per month on Business plans. This cap restricts volume for active content creators.
invideo AI uses a text-to-video pipeline with AI actors and a persistent context engine that holds a narrative character consistent across scenes, sessions, and episodes. It works well for quick educational or promotional clips. Likeness control is less granular than on dedicated avatar platforms.
| Tool | Best For | Consistency Features | Pricing Model |
|---|---|---|---|
| Synthesia | Enterprise training, compliance video | Express-2 DiT avatars, 140+ languages | Starter $29/mo, Creator $89/mo |
| HeyGen | Marketing, social, outreach video | Avatar V, 0.840 face similarity, 30-min continuous lock | Creator $29/mo, Pro $49/mo |
| Colossyan | Workplace learning, SCORM/LMS | NEO 2 model, 120+ languages, branching scenarios | Professional $59/mo (annual) |
| invideo AI | Quick text-to-video, educational clips | Persistent context engine, multi-model routing | Plus $20/mo (annual) |
These platforms excel at corporate presentations and scripted delivery. They lack the creative control over setting, outfit, expression, and shot style that social media content demands.
Cinematic Tools for Visual Storytelling
Cinematic tools focus on visual quality and motion. They use character references and image-to-video generation to approach consistency, and they expect creators to manage more of the workflow.
Runway Gen-4 provides the strongest identity stability among AI video models under controlled conditions, maintaining facial and structural consistency when the reference image is strong and prompt structure remains stable. Runway recommends using a high-quality reference image with a neutral expression and even, natural light as a flexible starting point. Consistency still depends on a full production workflow. It does not appear automatically.
Midjourney + Kling/Luma is the community-preferred cinematic workflow. Kling VIDEO 3.0 supports stronger element consistency for reference-driven video creation, with native multi-shot generation producing up to six shots while maintaining character identity, environment continuity, and narrative pacing. Luma Dream Machine produces highly coherent cinematic environments with excellent lighting and spatial depth, and character identity consistency across multiple independent generations remains a weaker area.
The cinematic workflow delivers visual quality and creative freedom that talking-head tools cannot match. The trade-off is complexity. Kling 3.0 generates motion frame by frame rather than referencing a fixed character model, which is why even reusing the same prompt can introduce small variations in facial features, clothing details, or lighting. These tools feel powerful for specialists and demanding for creators who need to publish at scale.
The All-in-One Solution: Sozee for Locked Likeness
Sozee serves creators who need a stable on-screen identity for every post. It is the only platform that locks likeness from as few as three photos and wraps that capability in a full content studio with direction controls, scheduling, and analytics.
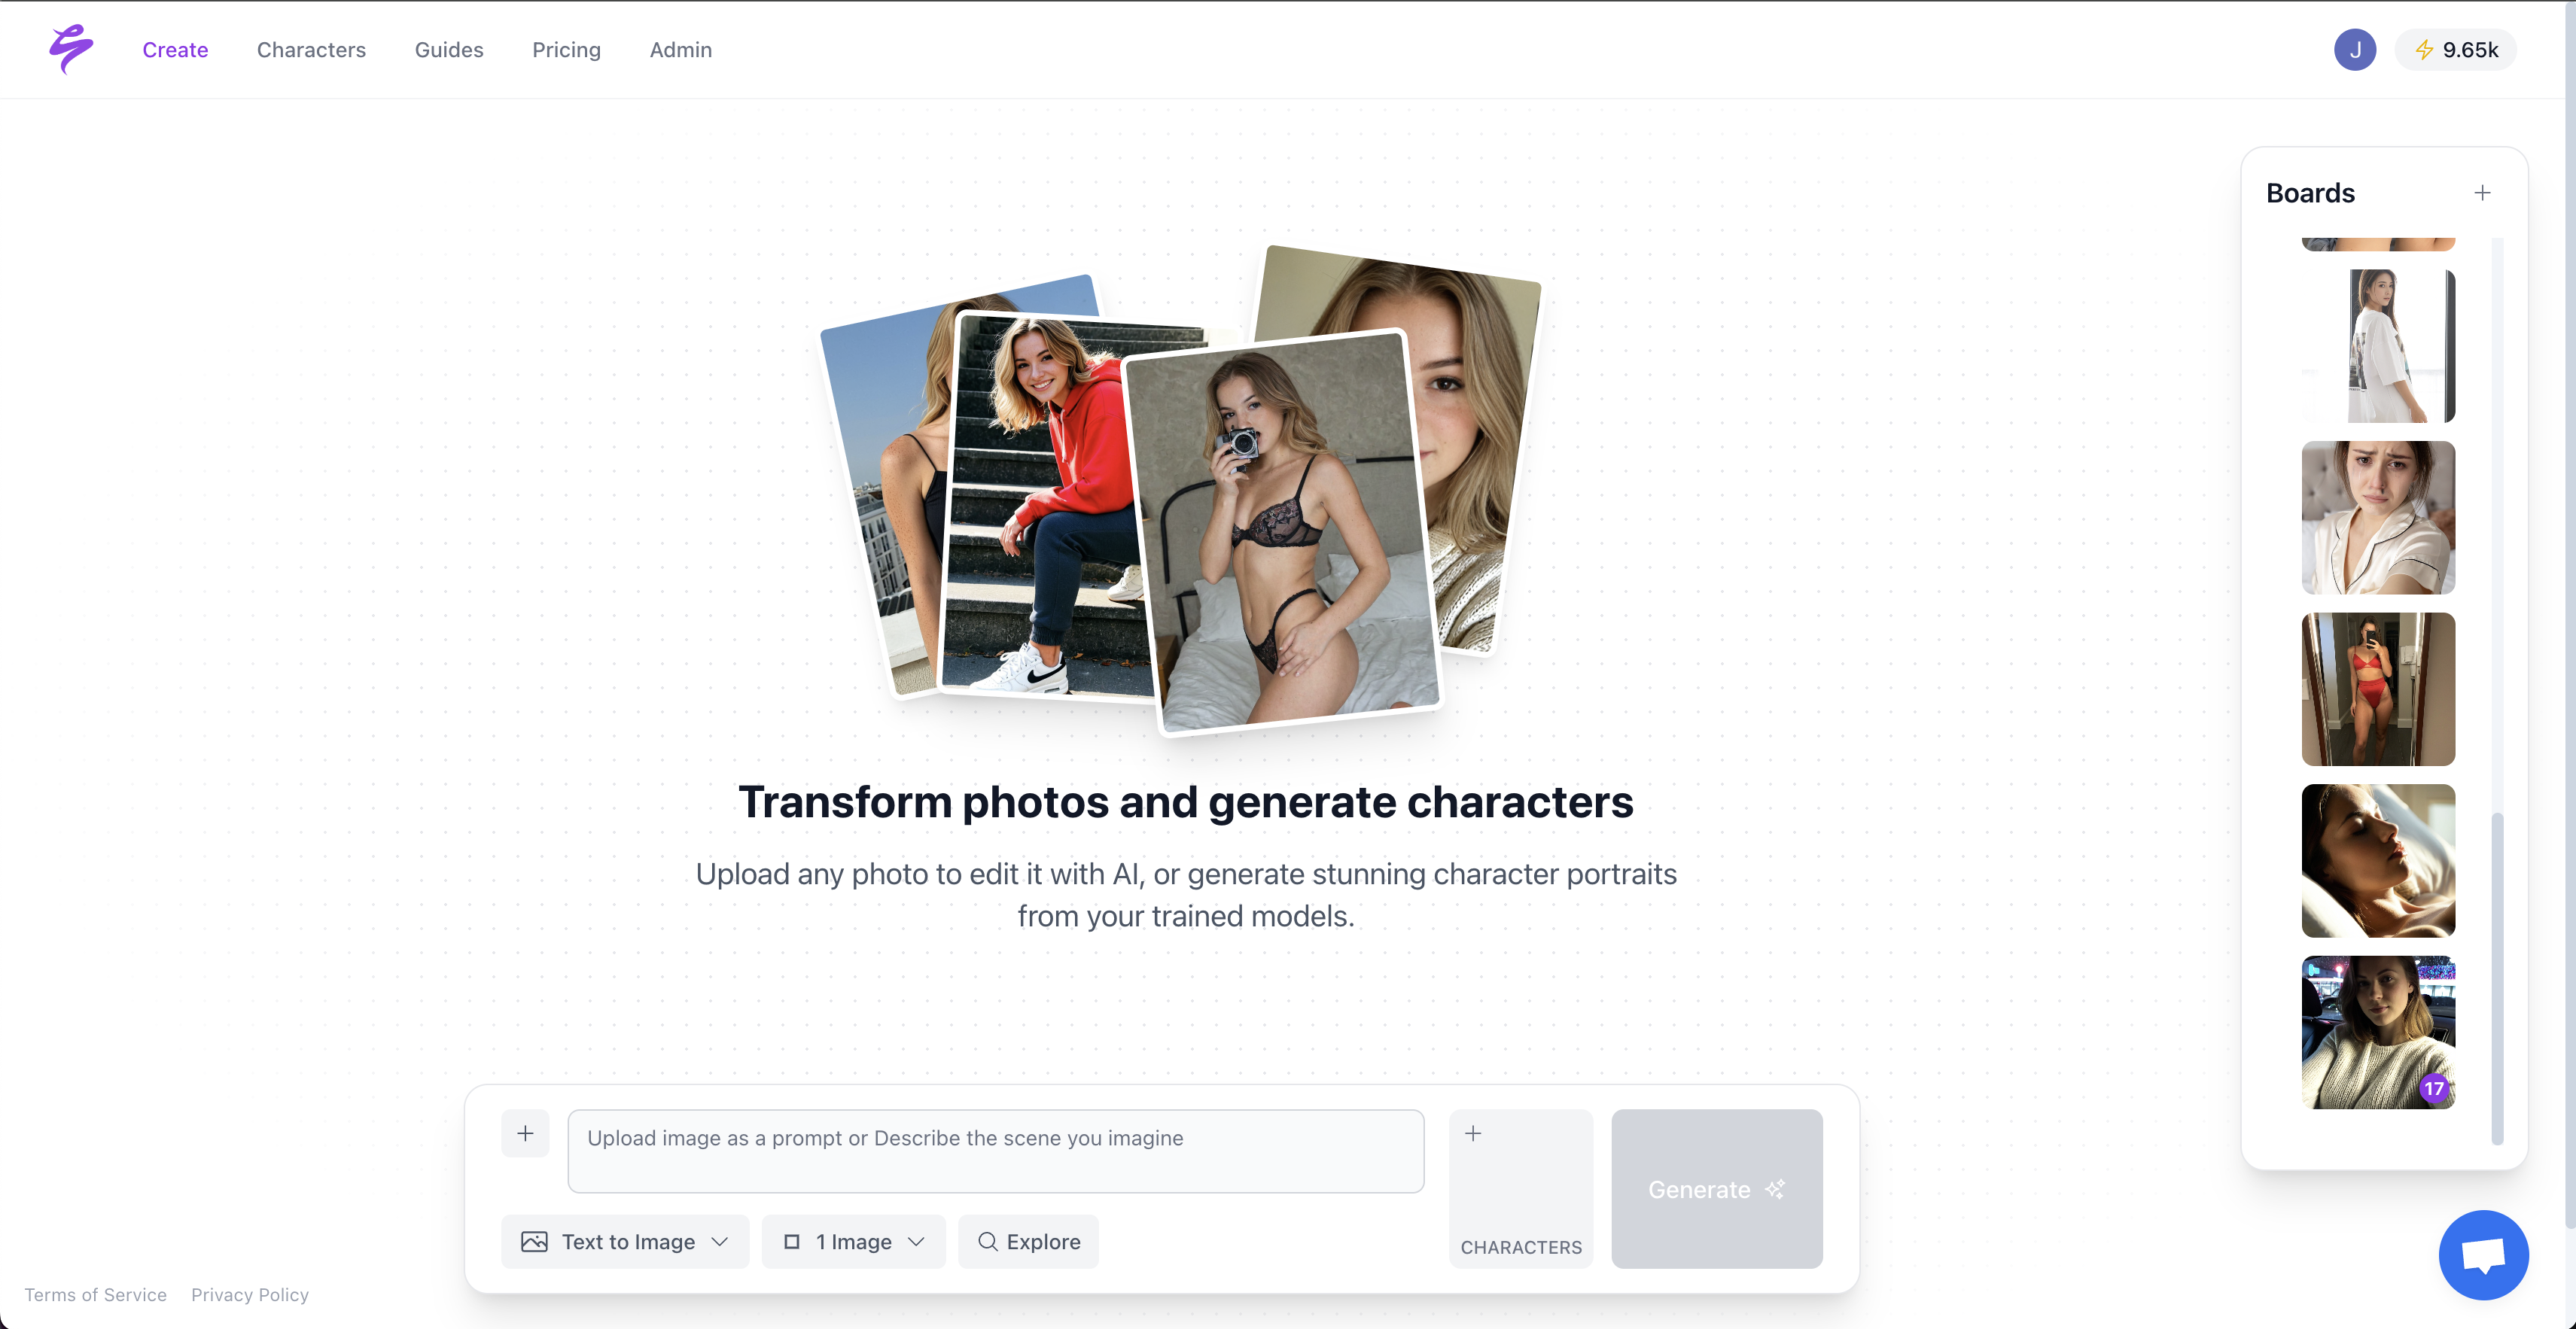
The core difference comes from architecture. Other tools focus on the result. Sozee focuses on the controls. Photo Control turns the prompt bar into a director’s panel. Five dimensions are set deliberately on every shoot:
- Setting – where the shoot happens, built from up to four reference shots and reusable forever
- Outfit – assembled from one piece per category (tops, bottoms, shoes, accessories)
- Shot style – how the frame is composed
- Expression – what the character communicates
- Object – up to four props per set
Photo Shoot takes a single image and builds a coherent set of up to ten around it. Identity, outfit, and environment stay locked while angle, pose, and expression change. Live Mode renders the character onto a camera feed in real time. The Agent interviews a creator into a finished shoot setup through conversation, then writes directly into the prompt bar and Photo Control panel so the shoot sits one tap from Generate.
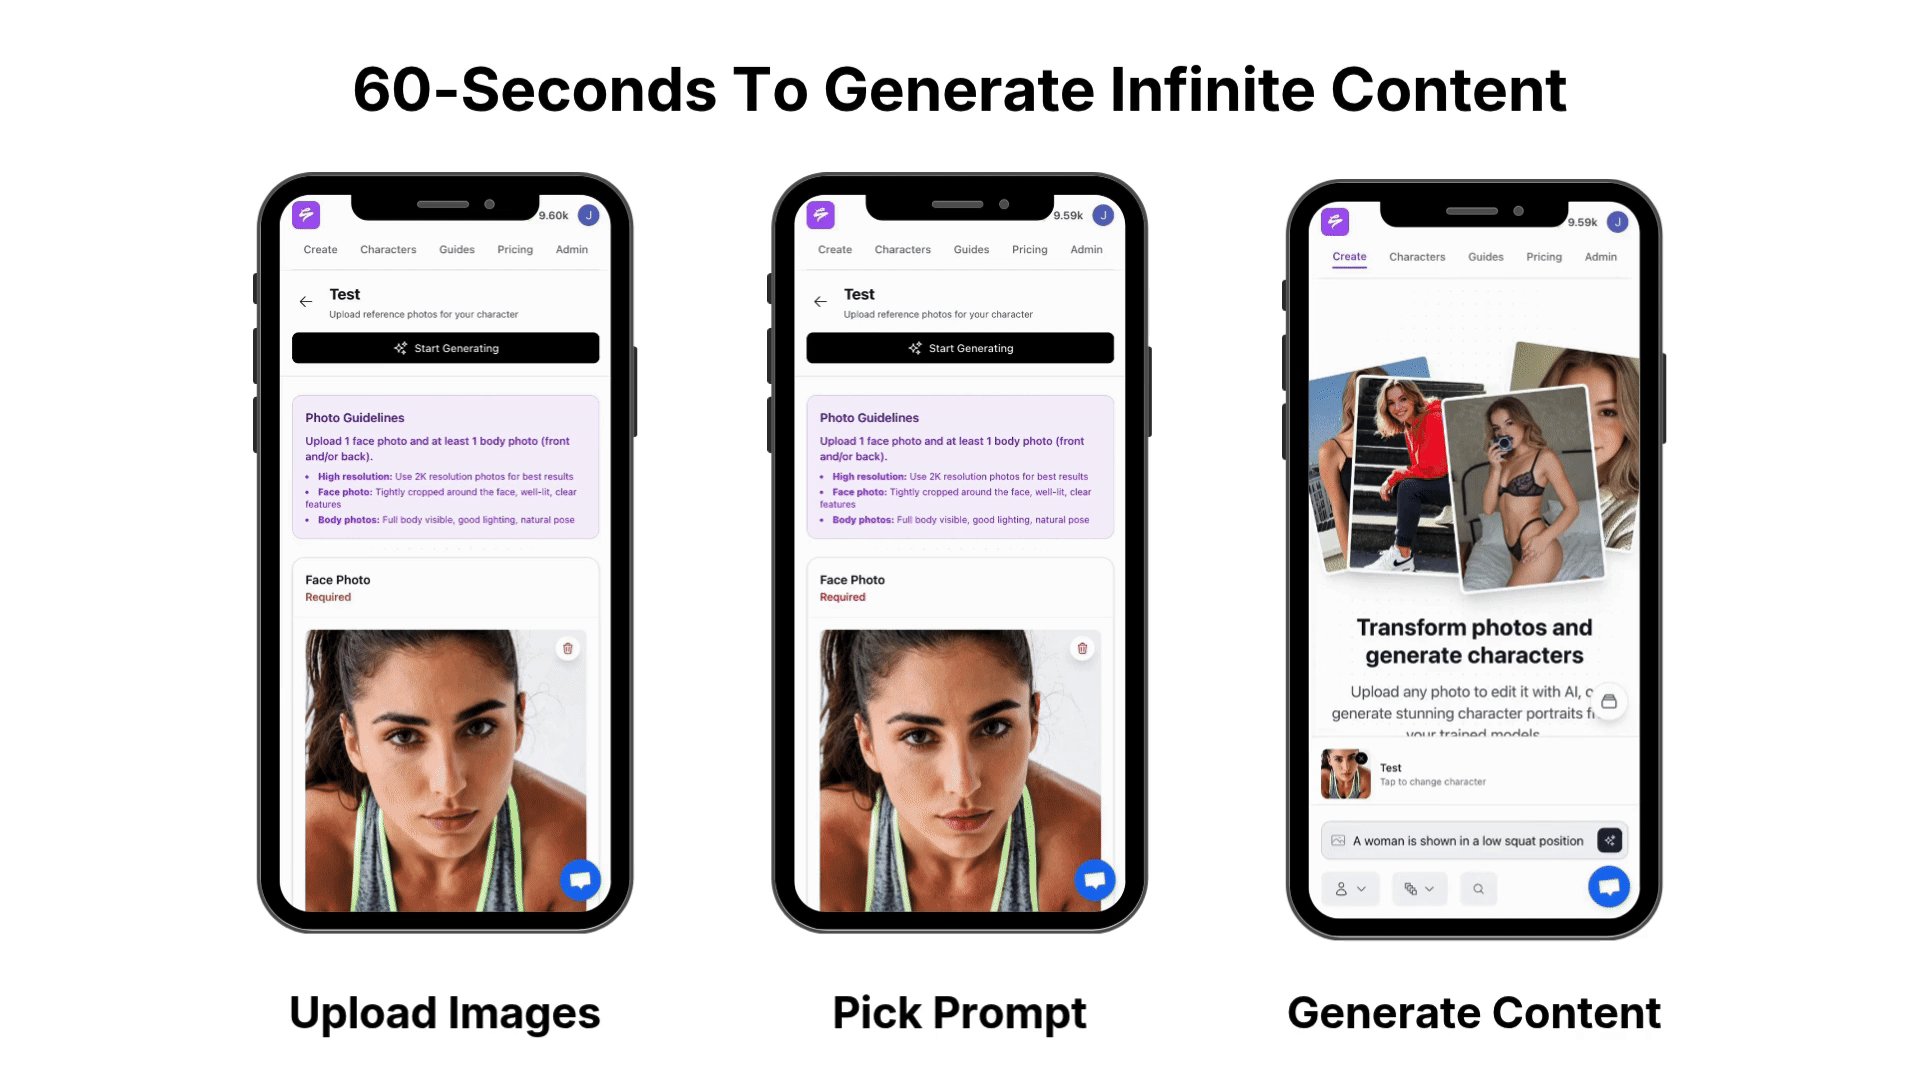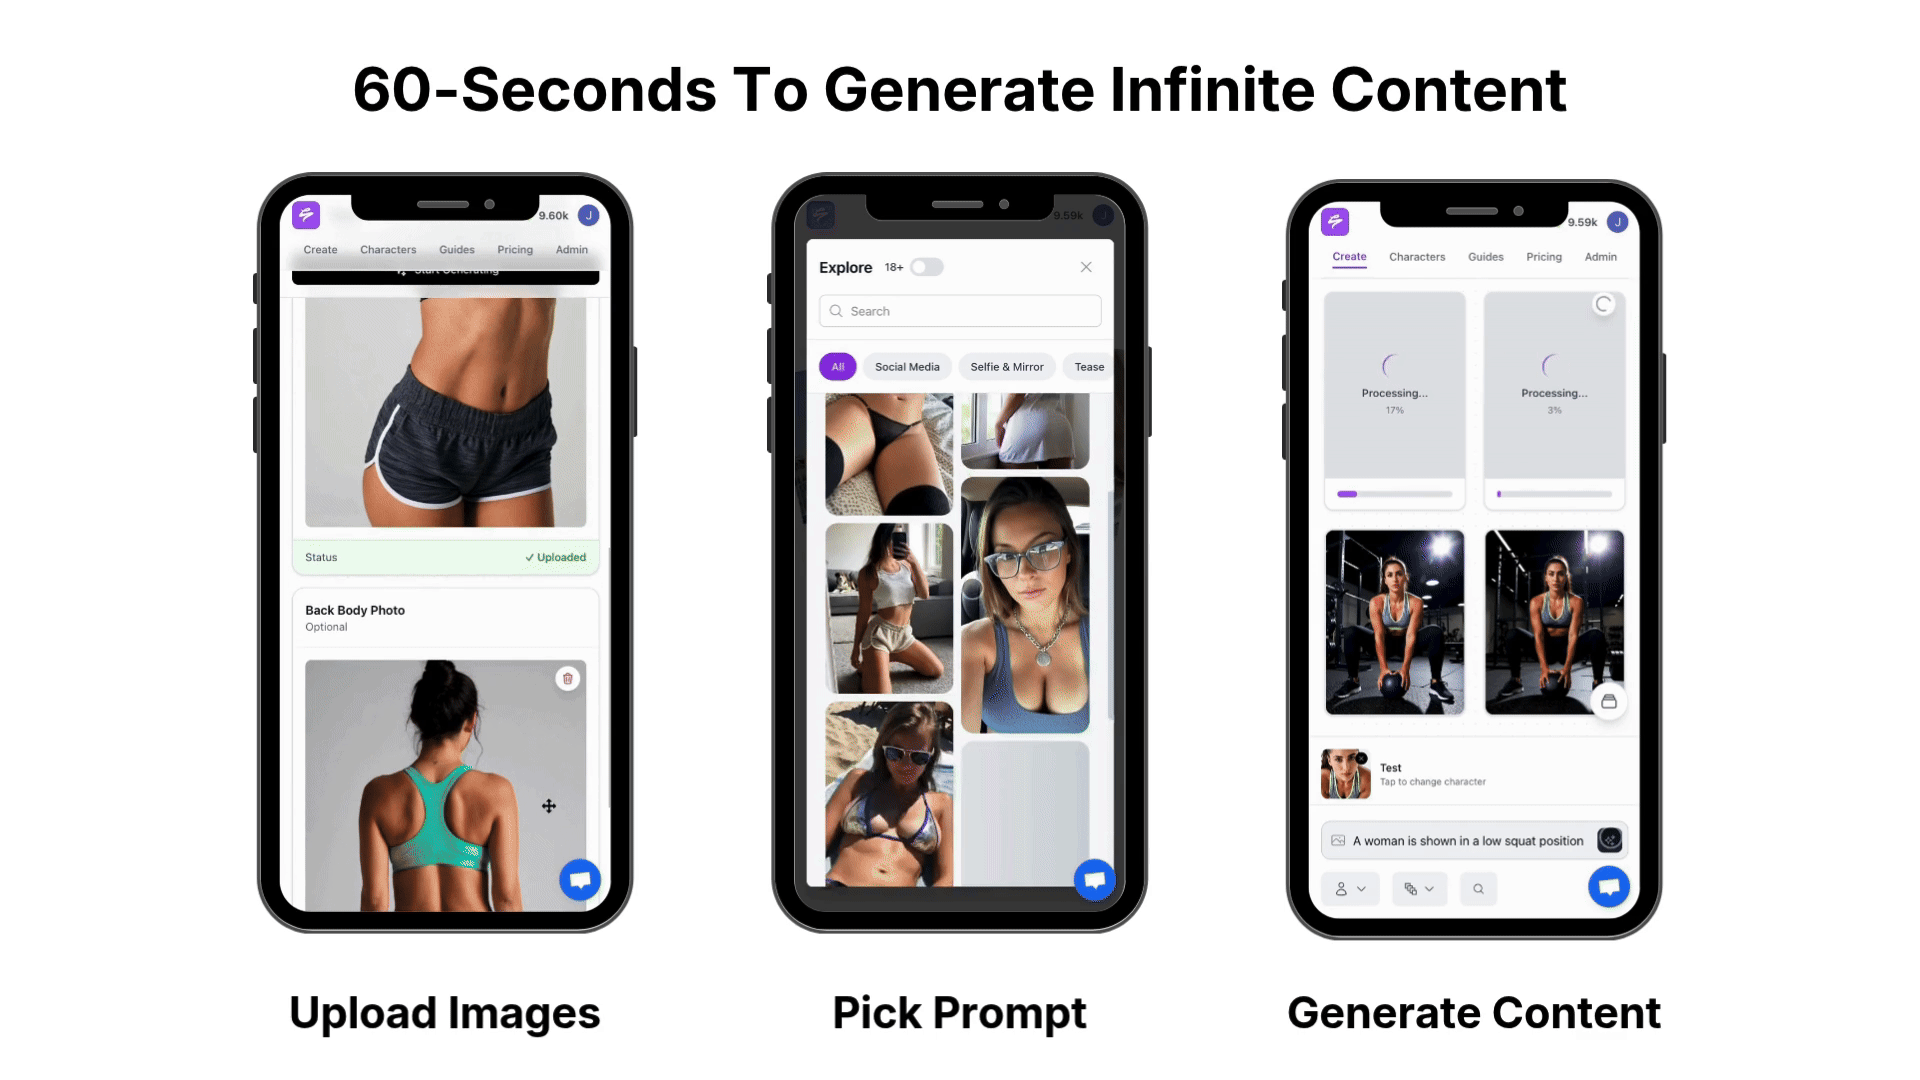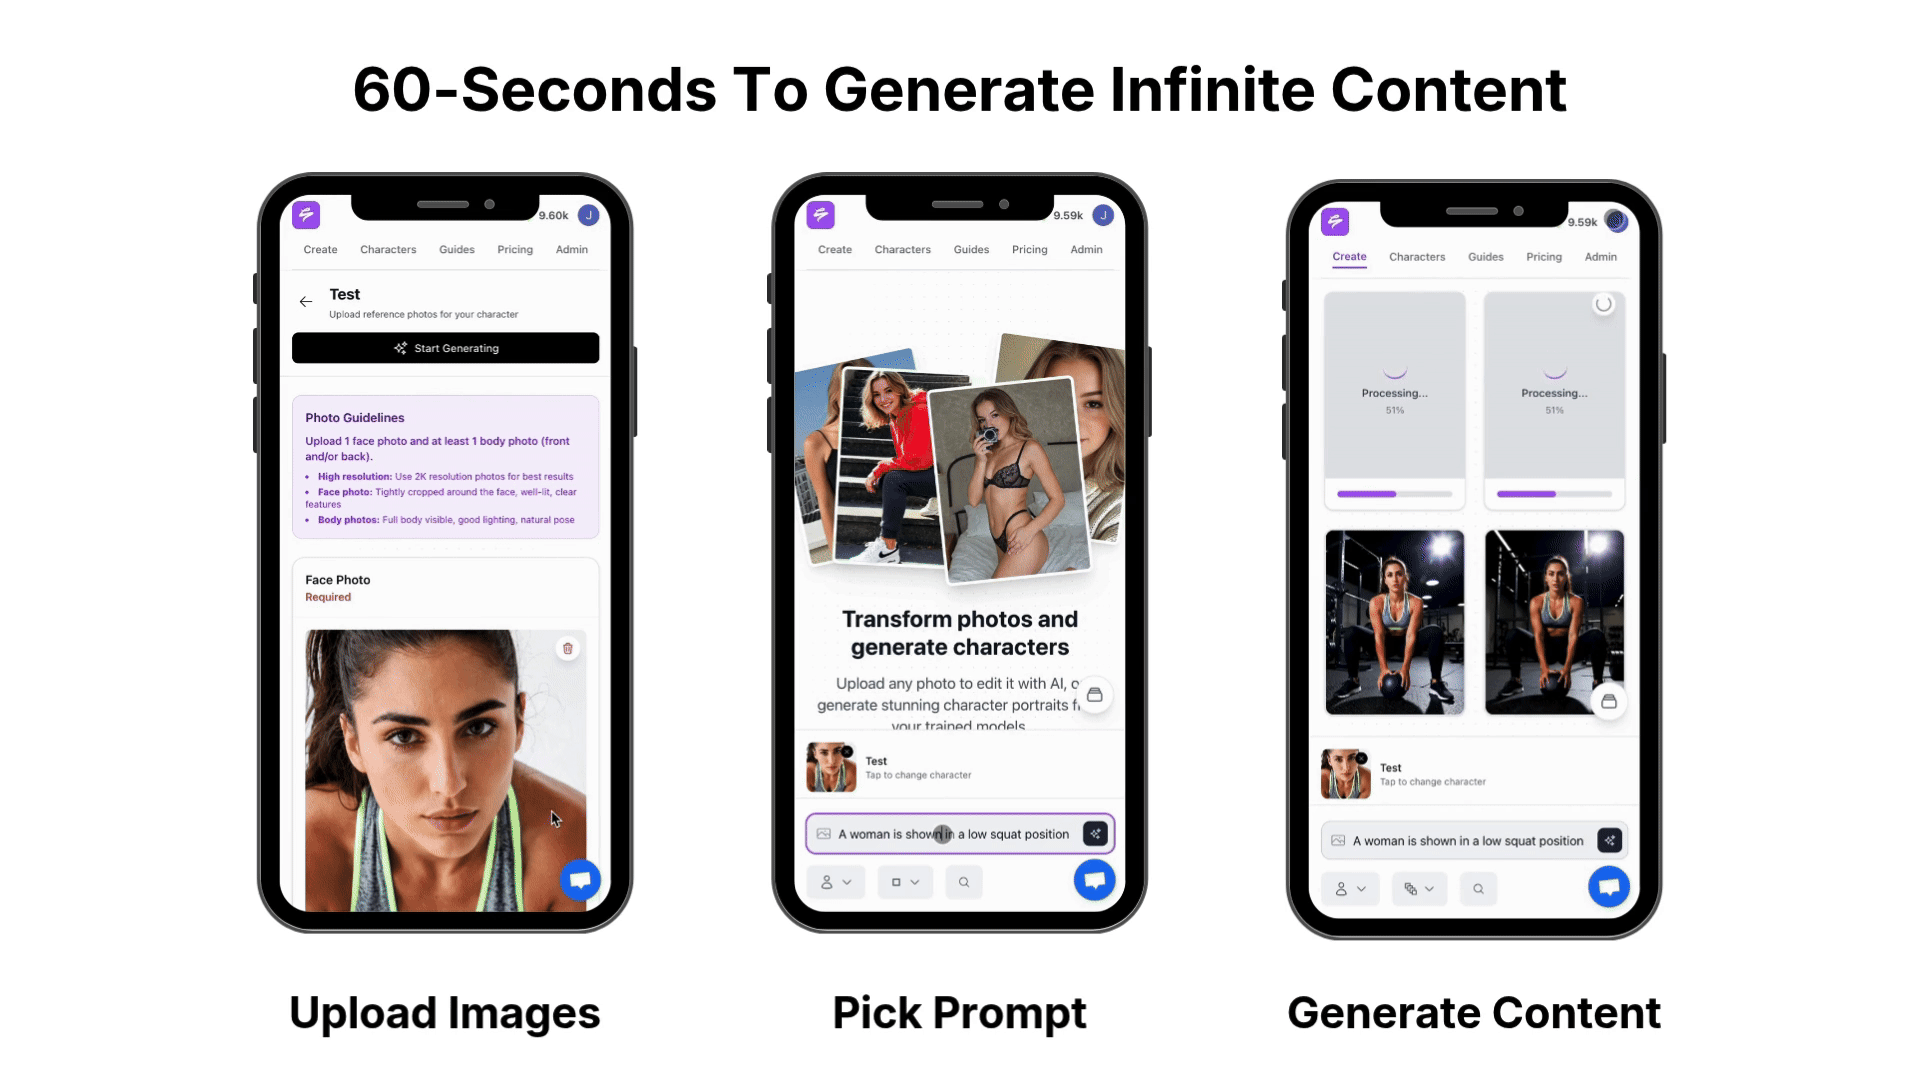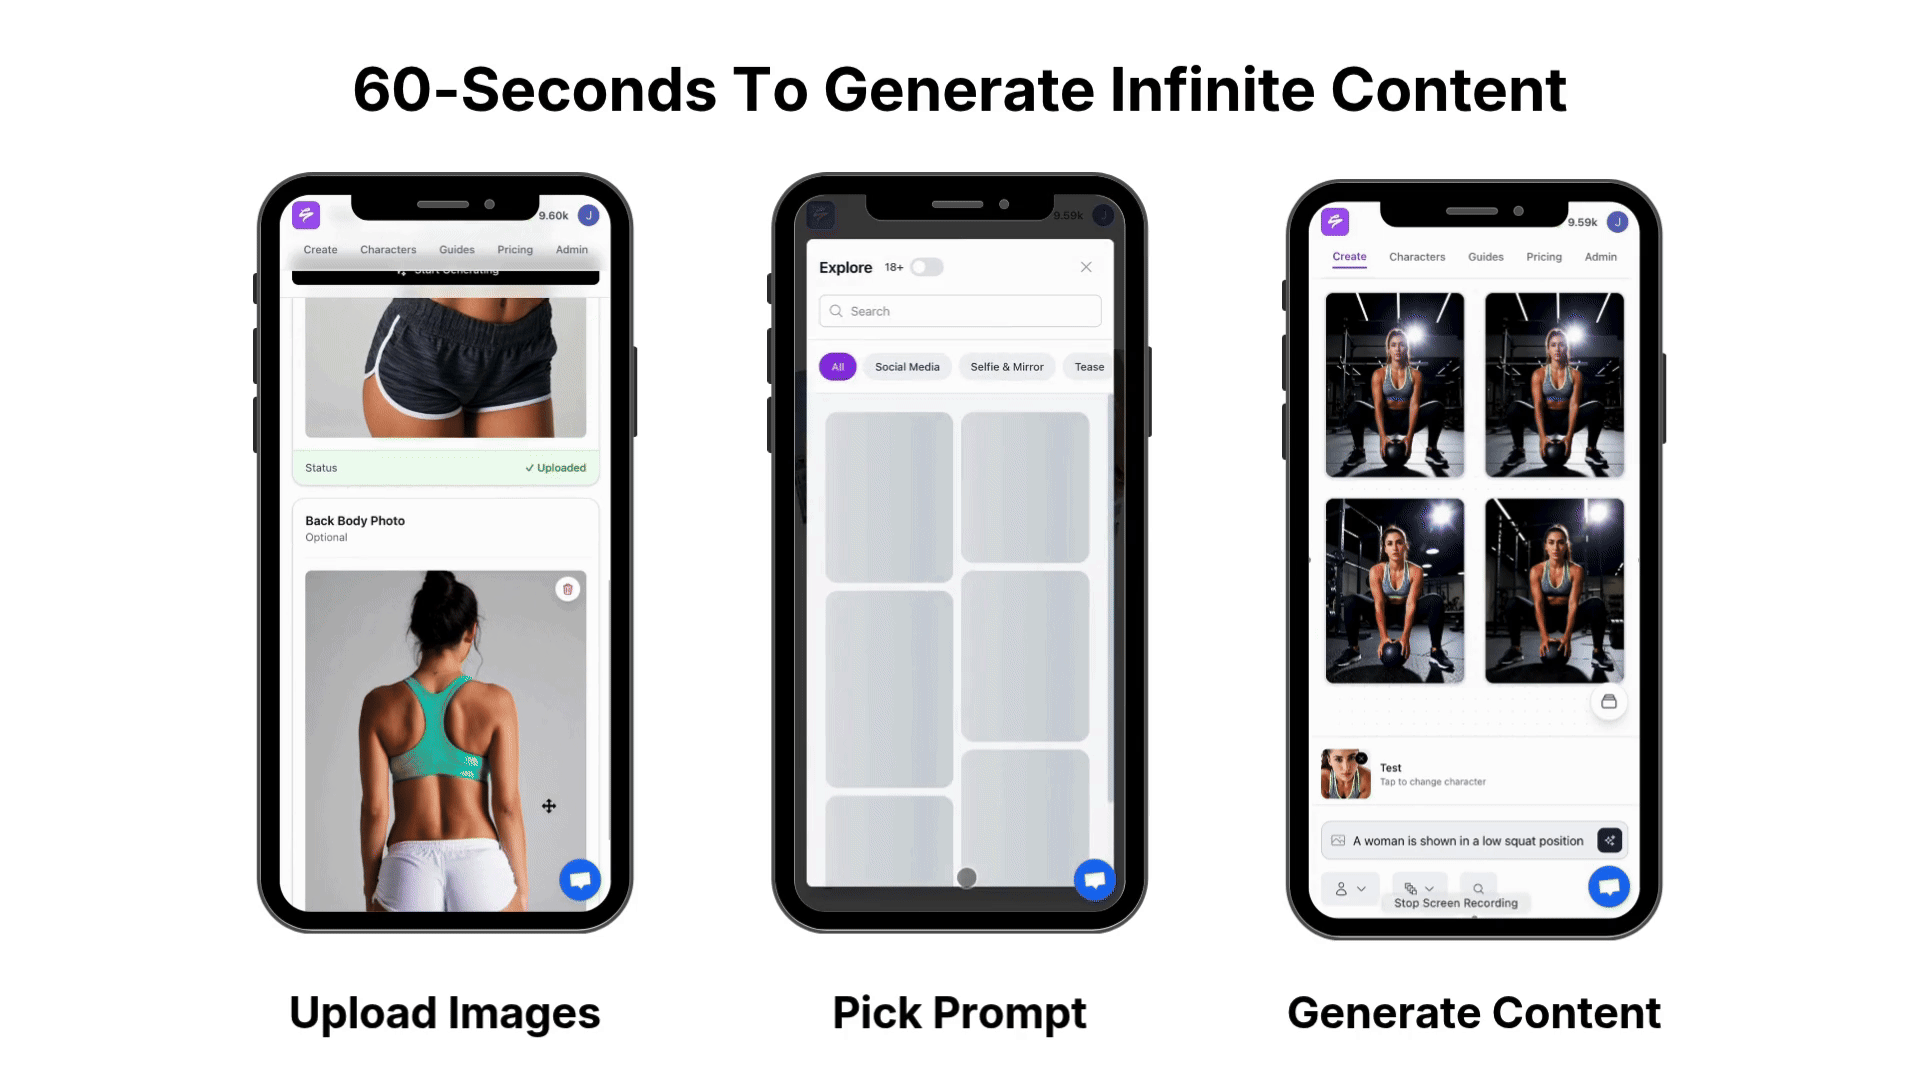
Creators who want an original character with no source photos can use Sozee’s AI Character Builder to generate a face that has never existed, consistent from the first frame. Voice cloning, video generation up to 1080p, native scheduling to Instagram, TikTok, X, Facebook, Reddit, and Fanvue, and split analytics that separate Sozee-posted content from manually posted content complete the loop.
Get started with Sozee today and create your first consistent avatar video.
Sozee-Centered Workflow for Consistent Videos
This workflow applies across tools, and Sozee removes most of the manual work by handling consistency at the platform level.
- Start with high-quality source images. A good reference image should be front-facing, with a neutral expression, soft even studio lighting with no hard shadows, and a clean background. Sozee generates the additional angles automatically from a single face image.
- Use a tool that locks likeness. The only reliable fix for shot-to-shot identity consistency is anchoring each generation to a saved visual reference. Sozee holds this anchor at the system level, so no manual setup is required.
- Define your character’s world once and reuse it. Locking characters and environments upstream, before generating any video, prevents lighting and positioning drift between generations. Sozee’s saved environments, outfit library, and object library make every subsequent shoot faster and more consistent.
- Use the same prompt structure or controls for every generation. Rewriting the character description in different ways for each prompt causes the model to interpret the character differently. Sozee’s Photo Control panel enforces a stable structure so creators do not need to remember exact wording.
- Review and refine with inpainting or reimagine features. Fix isolated issues without reshooting the entire set. Sozee’s editing suite includes inpainting, background swaps, expression swaps, and upscaling to 4K.
Free and Budget-Friendly Avatar Options
Free tiers exist across most major platforms, and they function as trials rather than production tools. HeyGen’s free plan includes three videos per month, up to one minute each, with 720p export. Synthesia’s free plan includes ten minutes of video per month with a watermark. Colossyan and Elai.io have limited free plans.
Six recurring limitations appear across free plans: short video duration, credit-based costs for every render or re-render, watermarks, 720p export quality, unclear commercial usage rights, and missing workflow features. Free tools answer “Can I make an avatar speak?” For creators producing content at meaningful volume, a dedicated platform becomes the practical path for brand building.
Comparison Table: All Tools at a Glance
| Tool | Type | Consistency | Best For |
|---|---|---|---|
| Synthesia | Talking-Head | Good | Enterprise training |
| HeyGen | Talking-Head | Excellent | Marketing and social video |
| Colossyan | Talking-Head | Good | Workplace learning |
| invideo AI | Talking-Head | Moderate | Quick text-to-video |
| Runway | Cinematic | Good (with workflow) | Narrative scenes |
| Midjourney + Kling/Luma | Cinematic | Moderate | Creative storytelling |
| Sozee | All-in-One Studio | Excellent | Brand building and monetization |
Across all these tools, one factor shapes success more than any other: the quality and stability of your source material and references.
Expert Tips for Realistic Results
Source image quality sets the ceiling for every tool. A master turnaround with front, three-quarter, side, and back views at the same scale, using a neutral expression, relaxed pose, and even background, helps the model read hair, jacket length, and equipment placement. Sozee generates these additional angles automatically from a single uploaded face image, which removes this prep step from the creator’s workflow.
Vocabulary discipline matters as much as reference quality. The most common cause of character drift is vocabulary swap: “brunette” and “shoulder-length dark brown hair” tokenize differently, and the model treats them as different people. Sozee’s Photo Control panel enforces identical descriptors structurally, so the same dimensions apply every time without retyping.
Reference quality matters more than model quality for AI character consistency: a mediocre model with a perfect reference produces more consistent results than a state-of-the-art model with a contaminated reference. Sozee’s locked likeness system sets the reference once and holds it across every generation, so creators never manage it manually.
Conclusion: Take Control of Your Content Production
Creators can achieve consistency in 2026 with the right system. Talking-head platforms like HeyGen and Synthesia handle consistency within a scripted presenter format. Cinematic tools like Runway and Kling deliver visual quality and motion but rely on disciplined manual workflows to hold identity across shots. No single tool in those categories covers both needs in one place.
Sozee serves creators who need locked likeness, creative direction controls, and a full content production loop from casting to scheduling to analytics without exporting to multiple tools. Use the detailed three-photo setup described earlier or generate an original character from scratch. Set your five dimensions. Build your world once. Reuse it for every shoot. Sozee breaks the link between a creator’s physical availability and their ability to produce content, so publishing can follow the creator’s schedule instead of their calendar.
Go viral today, sign up for Sozee, and start directing your first shoot.
The future of content creation belongs to creators who can produce without limits. AI avatar tools will keep improving, and the gap between generating images and running a brand will close fastest for creators who choose a platform built around consistency as the product.
Frequently Asked Questions
Why does my AI avatar look different in every video I generate?
AI video and image models generate from probability distributions, not from memory. Every generation starts from random noise and reconstructs the subject based on the prompt and any reference inputs provided. Without a locked visual reference anchored to the model’s input, the model re-interprets facial geometry, hair color, skin tone, and proportions independently each time. Prompt engineering alone cannot solve this behavior. The reliable solution is a platform that holds a locked character reference at the system level and applies it to every generation automatically. Sozee does this from a small set of uploaded photos, which removes the constant re-roll problem.
What is the difference between a talking-head avatar tool and a cinematic AI video tool?
Talking-head tools such as HeyGen, Synthesia, and Colossyan specialize in presenter-style video where a character speaks directly to camera, lip-synced to a script. They offer strong consistency within a single video and are optimized for corporate training, marketing explainers, and multilingual content. Cinematic tools such as Runway and Kling prioritize visual quality, motion realism, and creative storytelling. They can produce more visually dynamic content and require manual reference workflows to maintain character identity across shots, and they do not focus on scripted talking-head delivery. Sozee bridges both categories by locking likeness the way talking-head tools do while providing the setting, outfit, shot style, and expression controls that cinematic workflows require.
How many photos do I need to create a consistent AI avatar with Sozee?
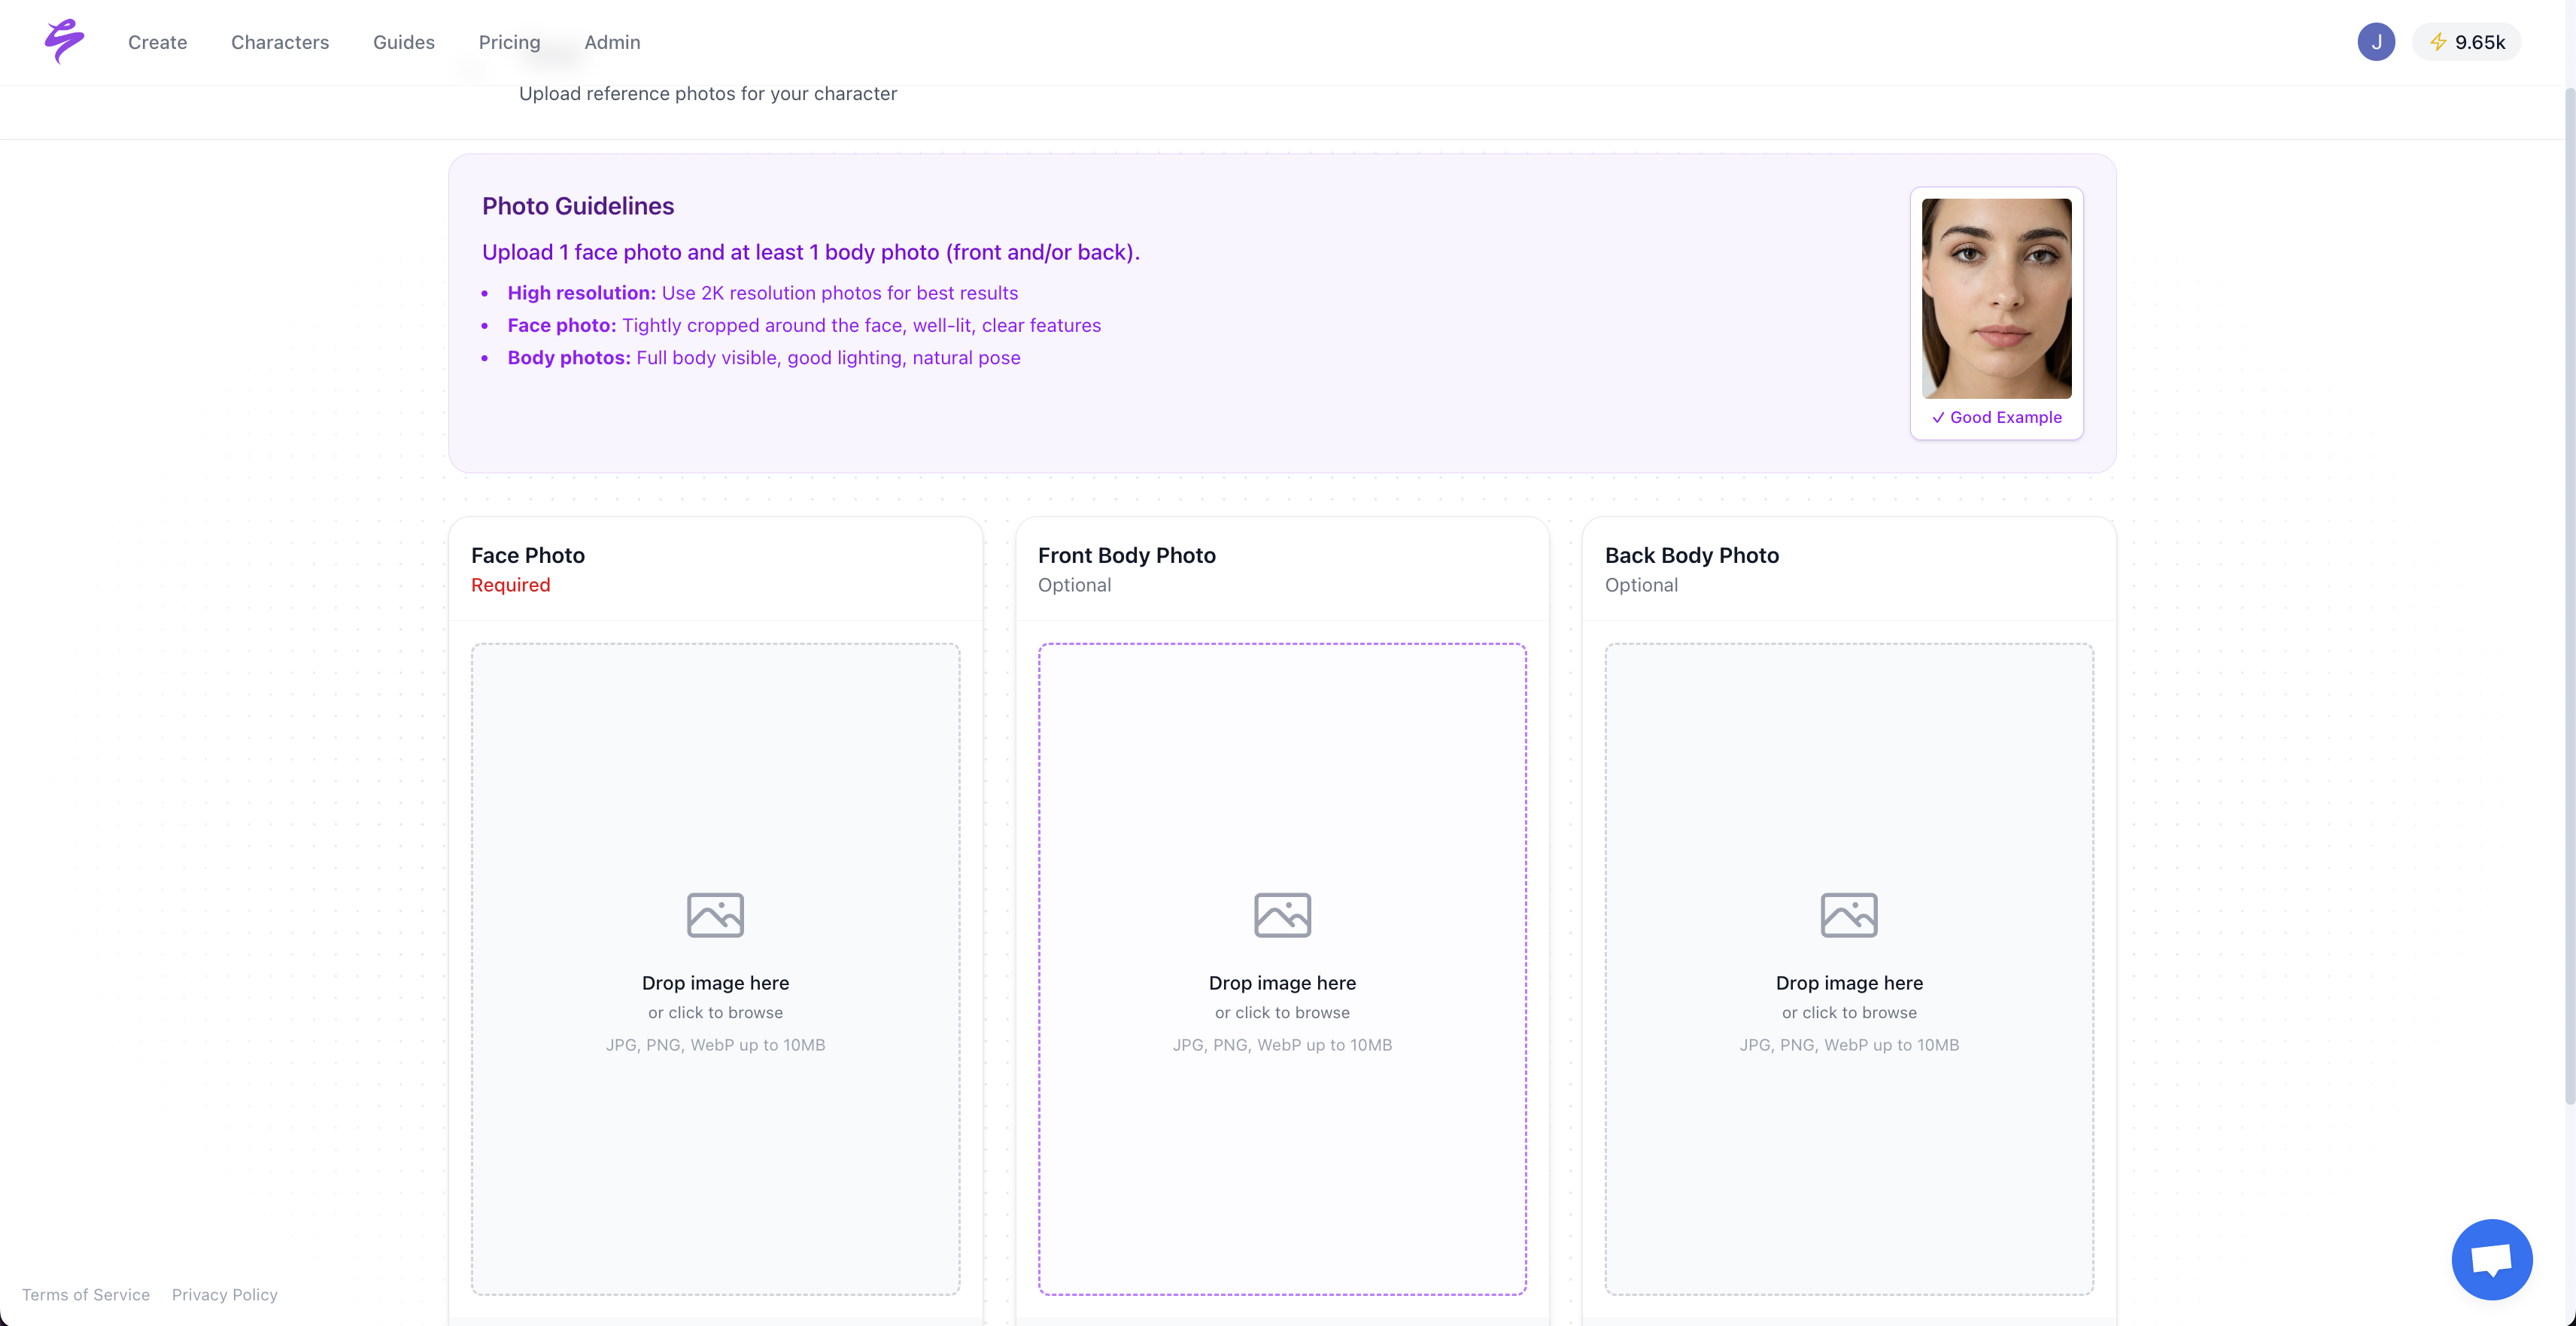
Sozee requires as few as three photos to reconstruct a hyper-realistic avatar with locked likeness. Upload a single face image and Sozee generates the additional angles, including front, quarter turn, side profile, and back, automatically. Add a front and back body shot and the character becomes ready for full-body scenes. Creators who want full anonymity or a fictional persona can use Sozee’s AI Character Builder to generate an entirely original character from scratch, specifying origin, ethnicity, skin, eyes, hair, physique, and distinctive details. No training period, no technical setup, and no waiting are required, so the character becomes available for shoots immediately.
Are free AI avatar tools good enough for building a content brand?
Free tiers on platforms like HeyGen, Synthesia, and Elai.io help test whether the format works by checking avatar quality, voice fit, and basic lip sync. They rarely support a full content brand. Common limitations across free plans include watermarks on exported video, 720p resolution caps, short video duration limits, credit-based costs that charge for every re-render, and unclear commercial usage rights. These constraints make free tools impractical for the volume and quality required to grow an audience, attract sponsorships, or run a subscription business. Creators who plan to monetize content need a platform with unlocked resolution, commercial licensing, and a workflow built around consistent output at scale.
What is the most important factor for keeping an AI character consistent across multiple videos?
The single most important factor is a locked visual reference used as the actual input to every generation, not a description of the character written in a prompt. Text-to-image and text-to-video models sample independently on every run, so even an identical prompt produces variation in facial geometry, hair shade, and skin tone across generations. A reference image anchors the model’s interpretation to a specific visual identity. The second most important factor is vocabulary discipline. Rephrasing the character description between generations, even slightly, causes the model to treat the character as a different person. Platforms like Sozee remove both failure modes by holding the locked reference and the directorial controls at the system level, so the creator never has to manage either manually.